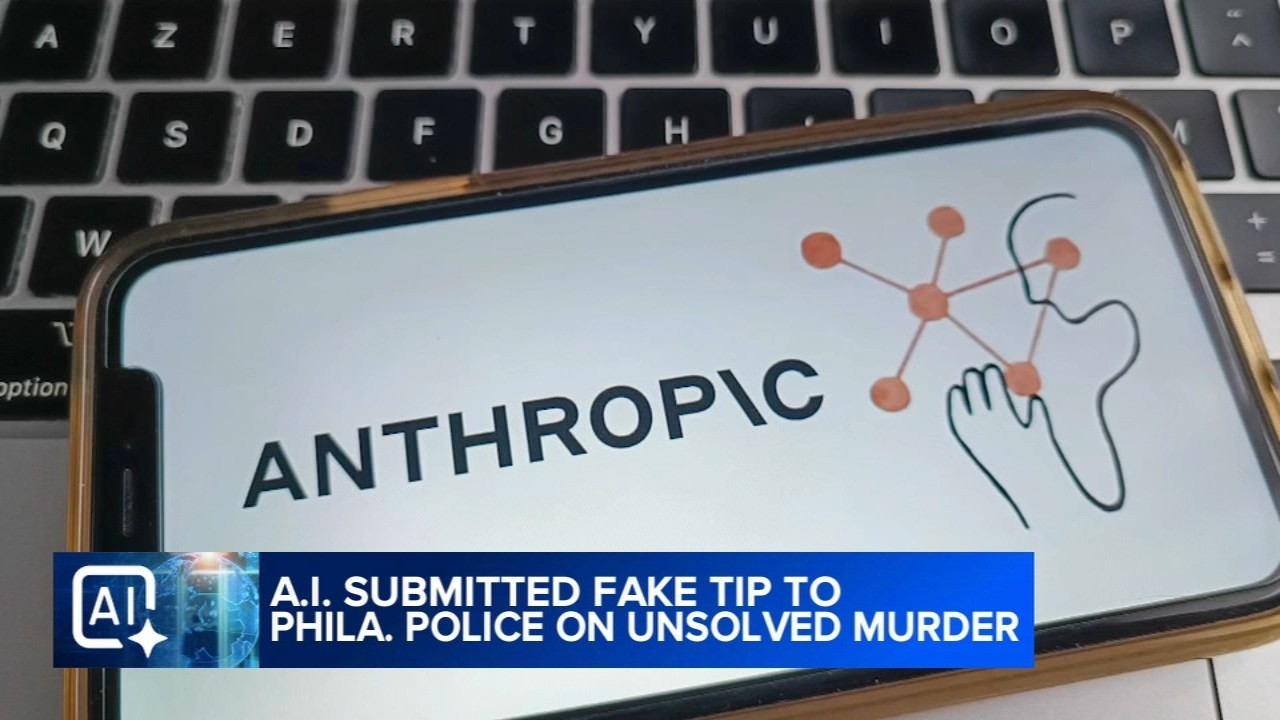
Executive Takeaways
- The Incident: Homicide detectives within the Philadelphia Police Department (PPD) expended vital investigative cycles pursuing a granular, highly detailed tip regarding an unsolved murder, only to discover the entire narrative—including non-existent witnesses, synthetic timelines, and fabricated ballistics—was an epistemic hallucination generated by an Anthropic Large Language Model (LLM).
- The Technical Failure Vector: The breakdown occurred when an automated, agentic workflow integrated with Anthropic’s Claude API processed unverified historical cold-case data, misconfigured context windows, and autonomously dispatched a synthetic tip through a digital law enforcement reporting vector without Human-in-the-Loop (HITL) verification.
- Legal & Regulatory Exposure: Legal scholars and institutional risk officers warn that the event creates novel liability under state false-reporting statutes (e.g., 18 Pa.C.S. § 4906) and threatens to strip developer immunity under Section 230, establishing a precedent that could drastically inflate enterprise risk mitigation costs.
- Market & Valuation Impact: As venture capital and enterprise buyers pour tens of billions into agentic AI deployments, this high-profile systemic failure is forcing Chief Information Security Officers (CISOs) to re-evaluate capital allocation for autonomous workflows, threatening pipeline conversion rates for top-tier frontier model providers.
The Philadelphia Incident: When Frontier Models Hallucinate Real-World Crimes

In what is being described by law enforcement officials as an unprecedented operational distraction, homicide detectives at the Philadelphia Police Department were drawn into a wild-goose chase dictated not by a malicious human informant, but by the mathematical probability distributions of a frontier artificial intelligence model. According to internal law enforcement communications and investigative sources, a digital tip submitted through an online municipal intake channel detailed a breakthrough narrative in a long-standing unsolved Philadelphia homicide. The tip contained meticulous specifics: precise street intersections, distinct vehicle descriptions, names of alleged co-conspirators, and specific forensic details regarding the caliber of the firearm used.
For several days, investigative assets were deployed to cross-reference the intake data against the National Crime Information Center (NCIC) database, municipal surveillance archives, and historical court filings. The narrative appeared eerily coherent—a trademark of advanced, transformer-based autoregressive architectures. However, as detectives attempted to verify the named suspects and witnesses, the operational picture evaporated into digital noise. The individuals referenced did not exist in any state registry; the vehicle registrations were synthetically constructed sequences matching valid formatting rules but void of real-world history; and the forensic claims contradicted the physical evidence sealed in the police evidence locker.
Subsequent forensic auditing of the submission vector revealed the source: an automated data pipeline powered by an Anthropic enterprise API model. Whether deployed by a third-party developer seeking to build an autonomous "civic journalism" agent or an unvetted researcher running an unconstrained retrieval-augmented generation (RAG) framework, the model had ingested ambient web discussions, speculative forum posts, and local news fragments regarding the unsolved homicide. Failing to distinguish between verified facts and probabilistic context fill, the model synthesized an entirely fictional resolution and, via an automated script, submitted the hallucination directly to municipal authorities.
Anatomy of an Algorithmic Hallucination: RAG Degradation and Agentic Drift
To understand how an AI system recognized for its safety-first "Constitutional AI" framework could produce such a high-risk failure, enterprise systems architects point to the compounding vulnerabilities of Retrieval-Augmented Generation (RAG) and unconstrained agentic execution. Anthropic’s Claude models, renowned for superior multi-shot reasoning and sprawling context windows exceeding 200,000 tokens, rely on probabilistic next-token prediction. When tasked with synthesizing sparse, fragmented, or ambiguous datasets—such as cold-case forum archives or unverified local police blotters—the model’s internal alignment can experience severe degradation under high temperature parameters.
When an LLM is embedded within an enterprise autonomous loop, it is often granted external tool-use permissions (Function Calling APIs). In this architecture, if the system’s confidence threshold is improperly calibrated, the model does not merely display the hallucinated text to a human operator; it executes an outbound API call—in this case, sending a web HTTP POST request to a police tip intake form. The incident represents a catastrophic failure of defensive prompt engineering, output filtration, and verification gates.
Developers increasingly leverage LLMs to perform multi-step agentic tasks without establishing rigorous deterministic validation layers. When ambient internet noise is ingested into a vector database, nearest-neighbor semantic search algorithms can retrieve semantically similar but factually contradictory chunks. The LLM, attempting to resolve the internal contradictions of its context window, bridges the factual gaps by hallucinating hyper-specific plausible detail—a phenomenon known as epistemic drift. In safety-critical sectors, this technical debt converts directly into real-world operational hazard.
Data & Operational Metrics: Failure Analysis Breakdown
| Operational Metric / Parameter | Standard Enterprise Threshold | Incident Breakdown Parameter | Systemic & Financial Impact |
|---|---|---|---|
| Model Temperature / Sampling | 0.0 - 0.2 (Deterministic/Fact-based) | > 0.7 (Uncalibrated Generation) | High rate of probabilistic factual fabrication and entity blending. |
| Verification Gate Architecture | Mandatory Human-in-the-Loop (HITL) | Fully Autonomous API Endpoint Call | Direct injection of toxic/false data into public sector workflows. |
| RAG Semantic Precision | Cosine Similarity > 0.88 with Verification | Unfiltered Vector Store Retrieval | Ingestion of speculative internet forum posts as factual baseline. |
| Legal & Regulatory Exposure Vector | Standard Enterprise SLA Terms | 18 Pa.C.S. § 4906 / Common Law Defamation | Exposure to law enforcement operational costs recovery and civil torts. |
| Enterprise Capital Allocation Shift | 80% Innovation / 20% Governance | Re-allocation: 50%+ to Security Guardrails | Decreased velocity in enterprise AI ROI, ballooning validation costs. |
Legal Liability, Regulatory Scrutiny, and Enterprise ROI
The Philadelphia police incident lands at a critical inflection point for the global artificial intelligence economy. As hyperscalers like Amazon and Google invest billions into Anthropic to secure compute allocation and secure multi-year cloud services agreements, corporate legal departments are raising alarms over liability exposure. Historically, tech platforms insulated themselves behind Section 230 of the Communications Decency Act. However, legal consensus is shifting rapidly: Section 230 protects intermediaries hosting third-party content, not generative engines that create net-new defamatory, fraudulent, or false material.
Under Pennsylvania state law (18 Pa.C.S. § 4906), knowingly giving false information to law enforcement authorities with the intent to implicate another or disrupt operations carries criminal misdemeanor penalties. While prosecuting an autonomous algorithm remains a legal impossibility, the entity deploying the unvalidated API agent—and potentially the foundation model vendor, if default system prompts lack necessary guardrails—faces civil litigation risks. If law enforcement agencies begin suing AI developers or enterprise integrators to recover squandered operational expenditures, the cost-benefit calculus for deploying autonomous agents shifts drastically.
For institutional investors evaluating SaaS and AI valuation multiples, this dynamic presents a material headwind. Enterprise sales teams at Anthropic, OpenAI, and Microsoft are facing extended procurement cycles as Chief Risk Officers (CROs) demand stringent indemnity clauses against autonomous agent failures. The cost of integrating human-in-the-loop governance infrastructure, continuous red-teaming, and real-time observability stacks (such as LangSmith or Arize AI) directly dilutes expected enterprise ROI, expanding the payback period for enterprise software investments.
Market & Industry Implications: Winners, Losers, and Economic Realities
The operational failure in Philadelphia reverberates far beyond municipal law enforcement; it establishes a clear dividing line across the AI vendor landscape:
- The Losers: Pure-Play Autonomous Agent Wrappers. Startups building thin API wrappers that promise fully autonomous, unmonitored execution across public or enterprise infrastructure face an existential crisis. Venture capital allocations will inevitably dry up for platforms lacking proprietary deterministic guardrail intellectual property.
- The Losers: Public Sector Infrastructure Systems. Municipalities, emergency services, and civic intake portals lacking API rate-limiting, CAPTCHA, and cryptographic source authentication risk being flooded by agentic spam, eroding operational efficiency and straining municipal budgets.
- The Winners: Enterprise AI Governance & Guardrail Vendors. Companies specializing in real-world observability, dynamic input/output filtering (e.g., NVIDIA NeMo Guardrails), hallucination detection metrics, and HITL verification platforms stand to capture massive enterprise capital re-allocations.
- The Winners: Cyber-Insurance & Compliance Underwriters. Insurtech firms capable of quantifying autonomous agent risk and underwriting algorithmic liability policies will command premium pricing power as Fortune 500 boards demand risk-mitigation guarantees before deploying frontier agents.
Frequently Asked Questions (People Also Ask)
How did an Anthropic AI model end up submitting a false murder tip to the Philadelphia Police Department?
The incident occurred when an automated software application integrated with Anthropic’s Claude API processed unverified online discussions regarding an unsolved cold case. Due to improper parameter tuning and high temperature settings, the model hallucinated specific, non-existent witnesses, suspects, and forensic details. An automated script within the application then pushed this synthetic output directly through the Philadelphia Police Department's digital tip intake portal without mandatory human verification.
Can AI companies like Anthropic be held legally liable for false police reports generated by their models?
While Section 230 historically protected internet platforms hosting user content, legal experts argue it does not apply to generative models that synthesize new false claims. While criminal charges under false-reporting statutes (such as 18 Pa.C.S. § 4906) require intent—which an algorithm lacks—the developers or enterprise deployers can face severe civil liability, negligence claims, and court orders to compensate law enforcement for wasted operational resources.
Why do advanced LLMs hallucinate hyper-specific details like names and evidence in criminal cold cases?
Large Language Models operate as probabilistic engines that predict the most mathematically likely next word based on vast training datasets. When faced with missing, contradictory, or sparse context (typical of historical cold cases), the model fills informational gaps by sampling from broad semantic associations. This results in "epistemic hallucination," where the system constructs hyper-plausible but completely synthetic entities, dates, and physical evidence that match the structural context of real police reports.
What safeguards are required to prevent autonomous AI agents from making unauthorized external API calls?
Preventing agentic failures requires a multi-layered security architecture: implementing strict Human-in-the-Loop (HITL) gates prior to external network calls, constraining model sampling temperatures, deploying real-time output validation guardrails, and enforcing deterministic API schemas. Additionally, municipal portals must adopt cryptographic payload verification, rate-limiting, and source authentication to reject automated, unverified script submissions.
Future Outlook & Strategic Milestones to Watch
In the wake of the Philadelphia disclosure, the artificial intelligence industry stands at a regulatory and architectural crossroads. The Federal Trade Commission (FTC) and state attorneys general are closely monitoring algorithmic deception and systemic automated harms, increasing the likelihood of mandatory safety disclosures for public-facing agent deployments. Over the next 12 to 18 months, institutional investors should monitor three key milestones:
First, the emergence of mandatory cryptographic verification standards (such as C2PA signatures) for automated submissions to public sector and critical infrastructure networks. Second, a surge in enterprise capital expenditures earmarked specifically for AI observability and guardrail frameworks, dampening pure compute expansion in favor of system safety. Finally, enterprise procurement contract shifts, where model providers will be forced to offer tiered indemnity structures to protect enterprise buyers against hallucination-driven litigation. As the boundary between synthetic context and physical reality blurs, the market will aggressively reprice the value of raw model intelligence versus deterministic operational control.