Executive Takeaways
- Deterministic vs. Probabilistic Retrieval: Traditional search engines rely on deterministic index matching, whereas generative AI utilizes probabilistic token prediction, introducing inherent risks of hallucination and factual drift.
- Enterprise ROI and Capital Expenditure: Cloud compute architecture demands for AI-driven search are squeezing infrastructure scalability budgets, forcing CIOs to meticulously weigh operational efficiency against exorbitant query costs.
- Regulatory Compliance Exposure: Financial institutions, legal entities, and healthcare conglomerates face severe regulatory compliance risks when deploying unverified generative answers for mission-critical operations.
- The Strategic Hybrid Model: Market leaders are transitioning toward dual-path workflows, deploying deterministic SQL and semantic search for data retrieval while reserving generative AI strictly for synthesis and summarization.
The Anatomy of the Information Revolution
For nearly three decades, the architecture of human curiosity was dictated by the blue link. Search engines operated as vast, deterministic indexers—sorting through petabytes of unstructured web data to serve exact URL matches based on keyword frequency, PageRank algorithms, and backlink authority. Today, that structural foundation is undergoing a violent tectonic shift. Driven by massive infusions of venture capital, surging valuation multiples for foundational model developers, and relentless consumer demand, generative artificial intelligence has usurped the traditional search bar.
Yet, as Google Trends data indicates unprecedented global search volume for AI-assisted queries, corporate boardrooms and technology analysts are sounding a note of caution. The rush toward conversational web retrieval has exposed a profound structural mismatch: users are applying probabilistic, creative text-generation engines to tasks that demand absolute factual determinism. Understanding when to leverage these cognitive engines—and when to strictly avoid them—has become one of the most critical operational imperatives for enterprise risk mitigation and personal digital hygiene alike.
When You SHOULD Use AI to Search the Web
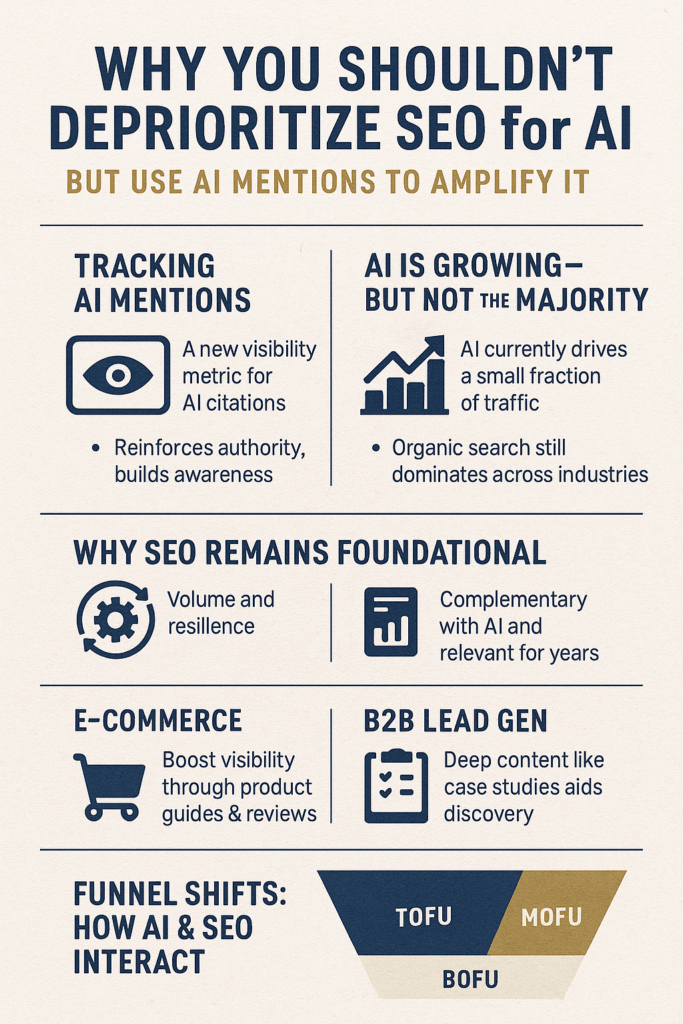
Generative AI search excels in environments where synthesis, unstructured data digestion, and creative ideation outweigh the need for hyper-precise, localized legal citations. When deployed strategically, AI search engines deliver transformative enterprise ROI by compressing hours of manual research into seconds.
- Complex Synthesis and Comparative Analysis: When researching multi-faceted topics—such as comparing the structural differences between European Union and United States antitrust regulations—AI can ingest dozens of diverse web pages and synthesize them into a coherent executive summary.
- Brainstorming and Ideation: For marketing executives, product managers, and developers looking for structural frameworks, naming conventions, or initial user-story outlines, AI search acts as an immediate sounding board, bypassing the friction of manual keyword refinement.
- Coding, Debugging, and Technical Snippets: Developers querying syntax structures, error codes, or algorithmic logic benefit immensely from generative search, as the models can write, annotate, and troubleshoot code snippets in real-time based on public documentation repositories.
- Multilingual Translation and Localization: Navigating foreign-language markets, parsing non-English regulatory filings, or synthesizing global macroeconomic reports is streamlined through AI models capable of contextual nuance far exceeding static translation software.
When You SHOULD NOT Use AI to Search the Web
Conversely, deploying generative search for deterministic queries introduces severe operational vulnerabilities. Because large language models (LLMs) operate on statistical token generation rather than true semantic verification, they are structurally prone to generating convincing falsehoods—colloquially known as "hallucinations."
- High-Stakes Financial and Legal Due Diligence: Relying on AI search for real-time stock prices, earnings report figures, tax codes, or active case law without inspecting primary source documents invites catastrophic financial and compliance liabilities.
- Real-Time Breaking News and Hyper-Local Verification: During live crisis events, natural disasters, or fast-moving geopolitical developments, AI search models frequently suffer from retrieval latency, conflating historical data with breaking developments or propagating unverified social media rumors.
- Medical, Nutritional, and Pharmacological Advice: Searching for precise drug interactions, diagnostic symptom checking, or dosage guidelines via consumer AI tools presents acute safety hazards, as probabilistic generation cannot substitute for clinical trial data and certified medical expertise.
- Exact Boolean Matching and Deep Archival Retrieval: When an investigator or academic requires exact database queries, specific cryptographic hashes, or niche archival document identifiers, traditional keyword and database indexing vastly outperforms semantic estimation.
Comparative Metrics: Traditional Search vs. Generative AI Search
To evaluate infrastructure scalability and financial viability, industry analysts examine the stark divergence in technical and economic metrics between legacy search paradigms and modern generative models:
| Evaluation Metric | Traditional Search (Deterministic) | Generative AI Search (Probabilistic) |
|---|---|---|
| Underlying Technology | Inverted Index, PageRank, Boolean Matching | Transformer-based LLMs, RAG, Vector Databases |
| Query Compute Cost | Low ($0.0001 to $0.001 per search) | High ($0.01 to $0.10+ per inference query) |
| Factual Precision Rate | Very High (Exact index matching to source) | Variable (Susceptible to hallucinations and drift) |
| Primary Ideal Use Case | Navigational lookups, exact facts, URL retrieval | Summarization, synthesis, exploratory ideation |
| Infrastructure Scalability | Mature, optimized distributed data centers | Capital-intensive, constrained by GPU availability |
Industry & Market Implications
The transition in search behavior is actively reconfiguring global capital allocation, corporate IT budgets, and digital publishing revenue models. As enterprises recalibrate their tech stacks, distinct winners and losers are emerging across the macroeconomic landscape.
The Winners: Cloud compute providers, specialized semiconductor manufacturers, and enterprise software platforms implementing Retrieval-Augmented Generation (RAG) architectures are capturing immense valuation upside. Companies that successfully optimize enterprise search compliance are securing robust operating margins by protecting proprietary data silos while harnessing public web synthesis.
The Losers: Traditional content publishers, informational websites, and affiliate marketing networks that relied on organic search traffic are experiencing severe liquidity and ad-revenue compression. Because generative search engines frequently synthesize answers directly on the search results page—bypassing click-throughs to original publisher domains—traffic monetization models are facing existential disruption, triggering widespread antitrust scrutiny and legal battles over intellectual property rights.
People Also Ask (Frequently Asked Questions)
Why do AI search engines make things up (hallucinate), and how can users prevent it?
AI search engines generate responses by predicting the statistically most likely sequence of words based on pattern recognition rather than cross-referencing a verified database for every single claim. To mitigate hallucinations, users should insist on engines utilizing Retrieval-Augmented Generation (RAG) with explicit citation links, and always cross-verify critical statistics against primary source documents.
Is AI search more expensive to run than traditional Google or Bing searches?
Yes. Executing an LLM inference query requires significantly more computational power—often utilizing specialized GPUs—making a generative AI query anywhere from 10 to 100 times more expensive in cloud compute infrastructure costs than a traditional indexed keyword lookup.
How does AI search affect website owners and publishers?
AI search fundamentally alters the digital publishing ecosystem by answering user queries directly on the search results page. This "zero-click" phenomenon reduces organic web traffic to publisher sites, prompting intense industry debate, copyright lawsuits, and the implementation of robotic exclusion protocols.
When will AI search completely replace traditional keyword search?
Complete replacement is unlikely in the near term. Instead, the industry is moving toward a hybrid architecture where deterministic keyword and database indices handle exact navigational lookups and compliance-heavy tasks, while generative models power exploratory research, synthesis, and conversational discovery.
Future Outlook & What to Watch
As the digital information market matures through the next 24 to 36 months, several critical milestones will dictate the trajectory of AI-driven web search. Industry stakeholders must monitor:
- Regulatory Interventions: Antitrust rulings and intellectual property legislation regarding data scraping and copyright indemnification will heavily impact how foundational models ingest web content.
- Infrastructure Scaling and Energy Constraints: The ability of data center operators to secure reliable, sustainable power and next-generation silicon will determine whether operational query costs decline or remain a barrier to universal deployment.
- Agentic AI Evolution: The shift from passive conversational summarization to active "AI agents" capable of executing multi-step web transactions, bookings, and enterprise workflows autonomously.
Ultimately, mastering the art of information retrieval in the age of artificial intelligence requires acknowledging its boundaries. By deploying generative tools where their probabilistic synthesis shines—and maintaining rigorous deterministic verification where accuracy is non-negotiable—enterprises and consumers can successfully navigate the most profound transformation in search history.