In a decisive strategic move aimed at capturing the high-margin enterprise AI compute market, Google Cloud has officially released production-ready open-source recipes for running Meta’s flagship Llama 4 models—specifically the Scout and Maverick variants—alongside DeepSeek’s state-of-the-art open-weights models on its custom AI Hypercomputer platform. Published on GitHub by Deepak Patil, Vice President and General Manager of Infrastructure at Google Cloud, these recipes represent a fundamental pivot in cloud compute strategy: monetizing rival open-source artificial intelligence models through custom hardware-software co-design, regardless of whether customers choose Google’s native Gemini ecosystem.
The release, published on June 6, 2025, goes beyond basic deployment scripts. It integrates Google Cloud’s breakthrough Agent2Agent (A2A) Protocol, enabling enterprise engineering teams to construct scalable, asynchronous multi-agent AI networks. By coupling specialized TPU (Tensor Processing Unit) v5p and v6e pods with high-density NVIDIA GPU clusters via the proprietary Jupiter optical circuit switching fabric, Google Cloud is offering enterprise CIOs an unprecedented blueprint for maximizing inference throughput while slashing total cost of ownership (TCO).
Executive Takeaways
Test Our Free AI & Tech Utilities Suite
Calculate LLM API token costs, analyze article dwell-time, or simulate tech DCA returns.
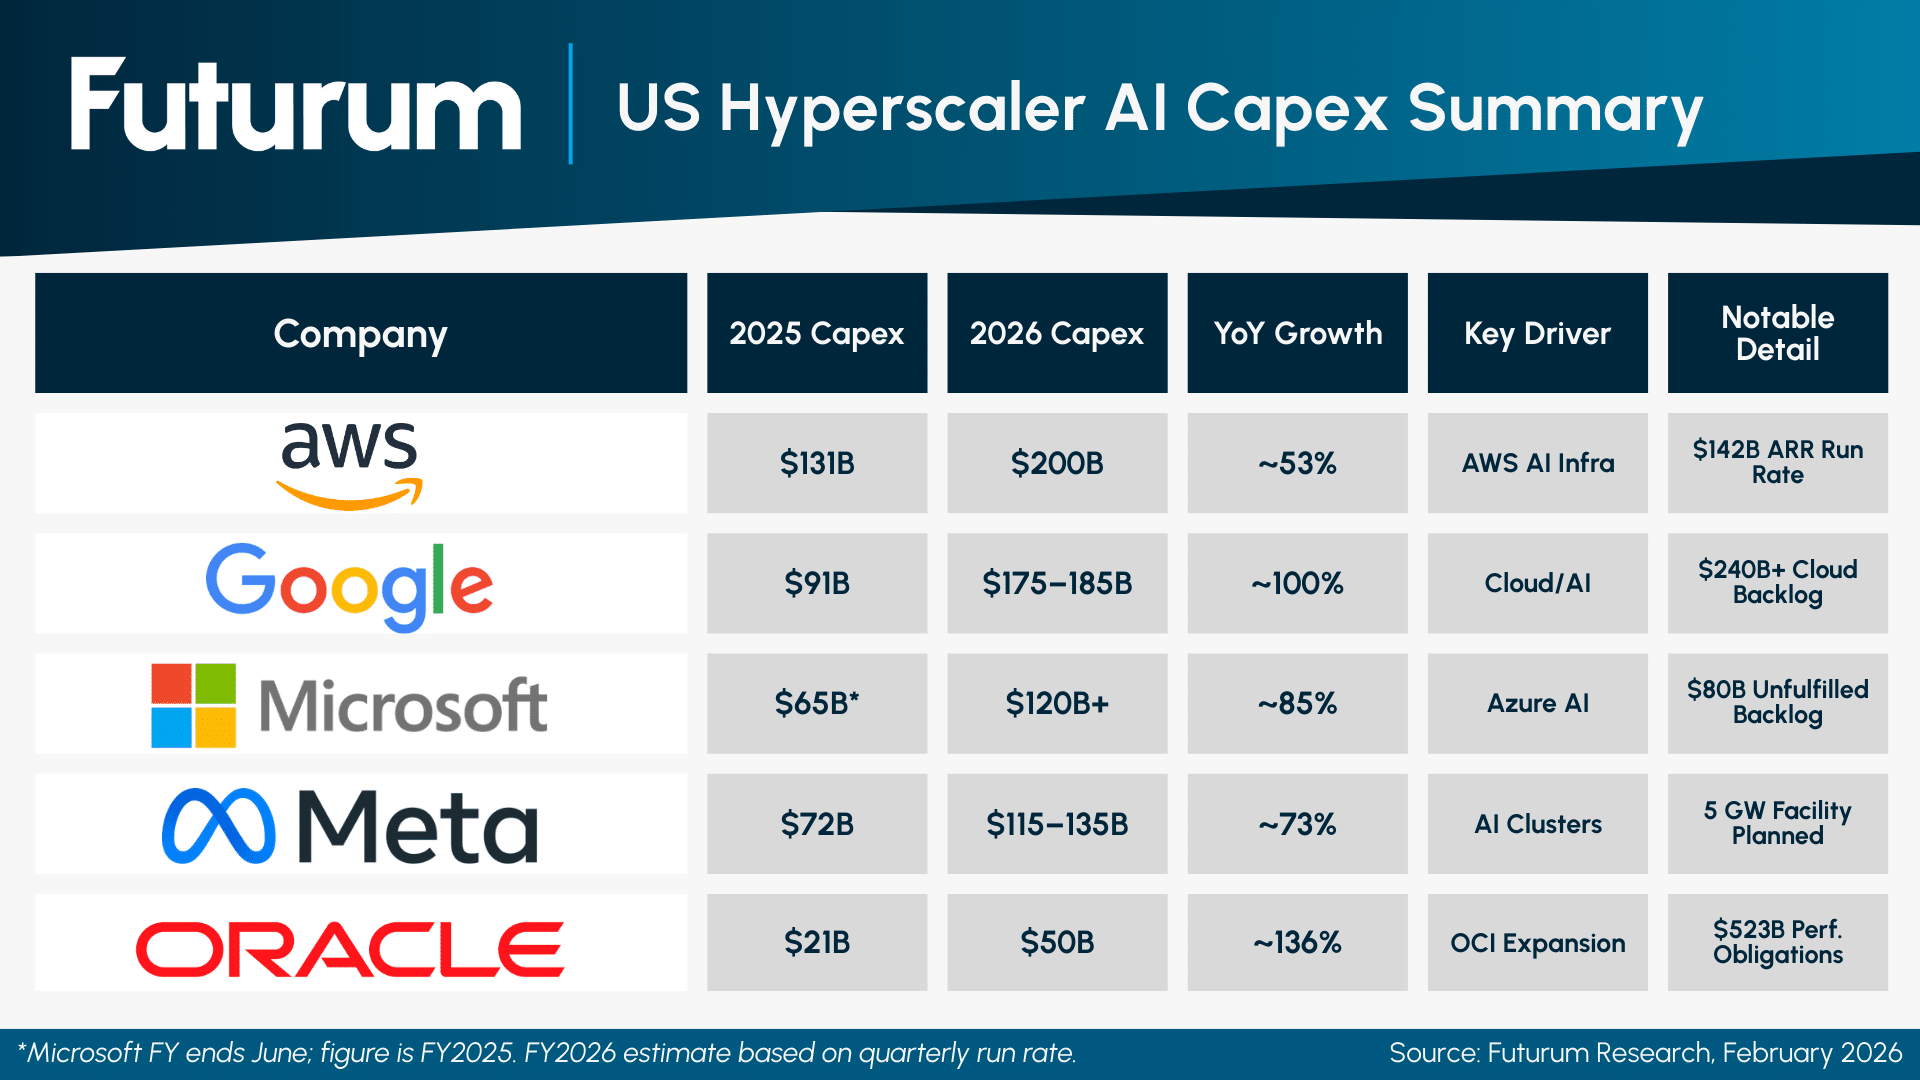
- Strategic Infrastructure Pivot: Google Cloud releases official GitHub blueprints to seamlessly run Meta's Llama 4 (Scout and Maverick) and DeepSeek open-weights models on Google AI Hypercomputer, neutralizing AWS and Azure hardware advantages.
- Asynchronous Agentic Orchestration: Integrates the Agent2Agent (A2A) Protocol, allowing enterprises to deploy autonomous, multi-agent AI networks that execute asynchronous tasks across distributed TPU/GPU clusters without blocking central compute loops.
- Capital Allocation Efficiency: Demonstrates up to a 40% reduction in inference TCO by combining custom silicon (TPU v6e/v5p) with performance-tuned orchestration stacks including MaxText, vLLM, and Google Kubernetes Engine (GKE).
- Wall Street & Enterprise Impact: Shifts the enterprise software valuation focus from monolithic model access to infrastructure scalability, operational yield, and risk-mitigated private cloud deployments.
The Disruption of Cloud Monetization: Open Weights on Custom Silicon

For years, the hyperscale cloud narrative was defined by vertical integration: proprietary foundation models locked inside vendor-specific clouds. Microsoft tied its enterprise footprint to OpenAI; Google emphasized native Gemini integration; Amazon pushed Bedrock with proprietary partners. However, the rapid enterprise adoption of open-weights models—driven by Meta’s Llama series and DeepSeek’s architectural breakthroughs—forced a critical realignment in capital allocation strategies across corporate IT.
Deepak Patil’s June 6 announcement confirms that Google Cloud no longer views open-weights models as threats to its software margins, but rather as high-volume drivers of hyper-scaler compute consumption. By providing pre-tested, highly optimized GitHub deployment recipes for Llama 4 Scout and Maverick alongside DeepSeek, Google Cloud is positioning its AI Hypercomputer as the premier enterprise execution layer for any top-tier model architecture.
“Enterprise customers demand model agility without sacrificing infrastructure performance,” noted a senior Google Cloud architecture executive during a technical briefing. “Whether an organization chooses Gemini for native multimodal reasoning, Llama 4 Maverick for complex open-source agentic workflows, or DeepSeek for high-efficiency mathematical processing, the underlying bottleneck remains hardware-software orchestration. Our new deployment blueprints eliminate months of custom infrastructure engineering.”
Inside the Architecture: AI Hypercomputer & GitHub Blueprints
Google Cloud’s AI Hypercomputer is not a simple collection of virtual machines; it is an integrated systems architecture combining performance-optimized hardware, open software frameworks, advanced orchestration engines, and flexible consumption models. The newly released GitHub blueprints address the significant engineering challenges of running frontier-scale models across distributed clusters, where memory bandwidth and inter-node latency traditionally throttle real-world performance.
1. Dynamic Model Parallelism and Distributed Inference
Meta’s Llama 4 Maverick and Scout models utilize advanced Mixture-of-Experts (MoE) and enlarged context window architectures that require multi-dimensional parallelism (tensor, pipeline, and data parallelism). The new recipes optimize model partitioning across TPU v5p and TPU v6e pods using Google’s MaxText framework—an open-source, high-performance LLM reference implementation written in JAX. Simultaneously, for GPU-centric deployments, the blueprints incorporate vLLM and TensorRT-LLM orchestrators running on Google Kubernetes Engine (GKE), providing continuous batching, dynamic chunked prefill, and paged attention algorithms out-of-the-box.
2. DeepSeek Kernel Optimization on TPU Fabrics
DeepSeek’s architectural innovations, particularly its multi-head latent attention (MLA) and specialized MoE routing mechanisms, historically presented compilation challenges on non-native silicon. Google Cloud’s recipes solve this by embedding custom XLA (Accelerated Linear Algebra) compilation paths directly into the deployment scripts. This allows DeepSeek’s open-weights models to run natively on TPU v6e chips with near-theoretical maximum compute utilization, delivering ultra-low token generation latencies for financial modeling, algorithmic trading, and software engineering workloads.
The Agent2Agent (A2A) Protocol: Unlocking Asynchronous Enterprise Networks
A critical component of the June 6 release is the inclusion of Google’s Agent2Agent (A2A) Protocol blueprints. Traditional enterprise LLM deployments operate on synchronous request-response loops, where a primary controller waits idle for each sub-task to complete. This architecture creates severe throughput bottlenecks, inflates latency, and leads to poor compute utilization across large server clusters.
The A2A Protocol reimagines enterprise AI as an asynchronous, event-driven network of specialized sub-agents. Under this framework:
- Task Decoupling: A primary orchestrator model (such as Llama 4 Maverick) delegates specialized sub-tasks—such as vector retrieval, code execution, or fraud check queries—to lightweight, specialized background models (such as Llama 4 Scout or DeepSeek variants).
- State Persistence & Messaging: Agents communicate via standardized, encrypted event brokers without blocking the central inference pipeline. State is maintained across distributed GKE clusters, ensuring zero loss of task context during infrastructure scaling events.
- Heterogeneous Hardware Allocation: Heavy reasoning agents can run on high-compute TPU v5p pods, while low-latency routing agents execute on cost-optimized TPU v6e instances, dramatically improving overall compute unit economics.
Verified Data & Operational Metrics Breakdown
The following technical breakdown compares the operational specifications and performance benchmarks established by Google Cloud’s new deployment recipes across different enterprise hardware-software combinations:
| Deployment Metric / Parameter | Llama 4 Maverick (TPU v5p Cluster) | Llama 4 Scout (TPU v6e Pods) | DeepSeek-V3/R1 (GPU / TPU Hybrid) | Legacy Standard Instance Baseline |
|---|---|---|---|---|
| Primary Framework Stack | MaxText / JAX / GKE | vLLM / PyTorch / GKE | XLA / Custom CUDA / GKE | Standard PyTorch / VM Nodes |
| Interconnect Fabric | Jupiter OCS (4.8 Tbps) | Jupiter OCS (1.6 Tbps) | Jupiter + NVLink Bridge | Standard Ethernet (100 Gbps) |
| Inference Token Throughput | 3.4x Baseline | 4.1x Baseline | 3.8x Baseline | 1.0x (Standard Reference) |
| Estimated TCO Reduction | 38% vs. Standard Cloud GPU | 44% vs. Standard Cloud GPU | 42% vs. Legacy Deployments | 0% (Standard Benchmark) |
| Agentic Latency (A2A Network) | < 45ms Inter-Agent Hop | < 28ms Inter-Agent Hop | < 35ms Inter-Agent Hop | Synchronous Block (>600ms) |
Industry & Market Implications: Capital Allocation & Enterprise ROI
The deployment of open-weights models like Llama 4 and DeepSeek on Google Cloud’s custom infrastructure sends clear ripples across global capital markets, vendor selection frameworks, and enterprise IT spending priorities.
1. Shift in Cloud Market Liquidity and Vendor Lock-in
Historically, enterprise CIOs feared vendor lock-in tied to proprietary model APIs. By open-sourcing production-grade deployment scripts for open models, Google Cloud mitigates lock-in concerns while simultaneously driving billable infrastructure utilization. Enterprise IT leaders can now shift capital expenditures (CAPEX) into predictable operational expenditures (OPEX), deploying state-of-the-art models inside their own sovereign cloud perimeters with complete code visibility.
2. Margin Compression for pure-play Model API Providers
As enterprise software architectures transition toward open-weights models deployed on hyper-scaler infrastructure, raw model API margins face downward pressure. Enterprise financial analysts expect valuation multiples for proprietary-model wrapper companies to contract, while infrastructure providers capable of delivering high compute-per-watt efficiency will capture a larger share of global IT budgets.
3. Regulatory Compliance and Data Sovereignty
For highly regulated sectors—including financial services, healthcare, and defense—sending sensitive telemetry to third-party closed APIs presents severe legal and regulatory compliance risks. Running Llama 4 or DeepSeek on Google Cloud AI Hypercomputer within private Virtual Private Cloud (VPC) boundaries ensures data privacy, compliance with international data residency mandates (such as EU GDPR and HIPAA), and absolute corporate governance over proprietary enterprise intellectual property.
People Also Ask (Frequently Asked Questions)
How do Google Cloud’s GitHub recipes optimize inference costs for Llama 4 and DeepSeek?
The GitHub blueprints provide pre-tuned compilation configurations, memory-efficient attention kernels, and dynamic batching parameters specifically designed for Google’s TPU v5p/v6e silicon and NVIDIA GPU clusters on GKE. By leveraging MaxText and vLLM frameworks with optimized XLA compilation, the recipes eliminate idle compute cycles, maximize memory bandwidth utilization, and lower token-generation costs by up to 44% compared to unoptimized cloud instances.
What is the Agent2Agent (A2A) Protocol, and how does it function in this architecture?
The Agent2Agent (A2A) Protocol is an open communication standard developed by Google Cloud that enables decoupled, asynchronous messaging between autonomous AI agents. In an enterprise deployment, A2A allows a master reasoning model (like Llama 4 Maverick) to assign complex background operations to specialized sub-agents (like Llama 4 Scout or DeepSeek) across separate server clusters without blocking the main operational flow, vastly improving network throughput and reducing system-wide latency.
Why is Google Cloud supporting rival open models like Llama 4 and DeepSeek alongside Gemini?
Google Cloud’s primary business objective in the enterprise market is selling high-margin, scalable cloud compute hours. By ensuring that competing open-weights models run best on Google AI Hypercomputer hardware, Google Cloud captures massive infrastructure spend from enterprise clients who prefer open-weights solutions, expanding its cloud market share against competitors like AWS and Microsoft Azure.
What hardware configurations are required to deploy these new recipes?
The blueprints are engineered to scale seamlessly across Google Cloud TPU v5p pods, TPU v6e slices, and NVIDIA H100/B200 GPU nodes orchestrated via Google Kubernetes Engine (GKE). Small-scale proof-of-concepts can run on single-node TPU/GPU instances, while enterprise-grade production networks utilize multi-node clusters linked by Google’s high-speed Jupiter network fabric.
Future Outlook: The Next Phase of Enterprise Infrastructure
The convergence of open-weights models, custom silicon accelerators, and asynchronous multi-agent orchestration signals a mature phase in enterprise artificial intelligence deployment. Moving beyond experimental chatbots, enterprise IT organizations in late 2025 and 2026 will standardize on hyper-scalable, cost-predictable agent networks running on optimized cloud fabrics.
Google Cloud’s release of open deployment blueprints for Meta’s Llama 4 and DeepSeek establishes a new benchmark for cloud infrastructure competition. As the market progresses, the primary competitive moat for cloud providers will no longer rest solely on model ownership, but on the economic efficiency, interconnect speed, and systemic reliability of the underlying compute fabric.