EXECUTIVE TAKEAWAYS
- The 96-GPU Standard: The LMSYS SGLang Team released a definitive deployment blueprint on May 5, 2025, detailing how to run massive Mixture-of-Experts (MoE) architectures like DeepSeek-V3 and DeepSeek-R1 efficiently on a modest 96-node NVIDIA H100 cluster.
- Architectural Breakthroughs: By combining Prefill-Decoding (PD) Disaggregation with Large-Scale Expert Parallelism (EP)—underpinned by DeepSeek’s custom DeepEP communication library—engineers have solved the critical bottlenecks of inter-GPU token routing and memory contention.
- Economic & Infrastructure Realities: This breakthrough drastically alters enterprise capital allocation, lowering the barrier to entry for tier-2 cloud providers and cutting the Total Cost of Ownership (TCO) for running state-of-the-art reasoning models.
- Market Disruption: The deployment framework challenges the legacy narrative that running frontier-class intelligence requires hyperscale, thousand-GPU installations, directly impacting valuation multiples across the semiconductor and enterprise AI sectors.
For more than two years, the economic calculus of frontier artificial intelligence has been dictated by a simple, brutal equation: massive intelligence requires massive capital expenditure. Wall Street analysts and corporate treasurers have watched in awe—and mounting anxiety—as hyperscale cloud providers poured billions of dollars into sprawling clusters of NVIDIA H100 and H200 accelerators, operating under the assumption that running models like DeepSeek-V3 or DeepSeek-R1 demanded infrastructure footprints rivaling small municipalities.
That paradigm shifted decisively on May 5, 2025. In a technical release that sent immediate ripples through enterprise boardrooms and quantitative trading desks alike, the LMSYS Org SGLang Team published a comprehensive operational blueprint: "Deploying DeepSeek with PD Disaggregation and Large-Scale Expert Parallelism on 96 H100 GPUs." This landmark documentation provides a rigorous engineering roadmap for deploying advanced Mixture-of-Experts (MoE) models on a tightly constrained, highly optimized 96-GPU footprint. For enterprise Chief Information Officers (CIOs) and cloud architects evaluating their enterprise ROI, the implications are profound: frontier-grade reasoning capability is no longer the exclusive domain of entities commanding thousand-node clusters.
The Structural Bottlenecks of Frontier MoE Deployment
To understand the magnitude of the SGLang team's achievement, one must examine the fundamental architectural friction points of modern Large Language Models (LLMs). Models utilizing Mixture-of-Experts architectures—exemplified by DeepSeek-V2, DeepSeek-V3, and the reasoning-focused DeepSeek-R1—achieve high parameter counts and computational efficiency by routing tokens to specific subsets of neural network "experts." While this dramatically reduces the floating-point operations (FLOPs) required per token during inference, it introduces a nightmarish systems engineering challenge: inter-GPU communication overhead.
In a standard tensor parallelism (TP) or pipeline parallelism (PP) setup, the sheer volume of data moving across NVLink and InfiniBand fabrics during expert routing can easily saturate network bandwidth, creating severe latency bottlenecks. Furthermore, the generation phase of transformer models (decoding) and the initial ingestion phase (prefilling) have fundamentally different operational profiles. Prefilling is compute-bound and heavily parallel, while decoding is memory-bandwidth-bound and latency-sensitive. Co-locating both phases on the same physical hardware forces structural compromises that degrade cluster utilization efficiency, inflate operational expenditure (OpEx), and erode profit margins for cloud service providers.
Decoding the Core Technologies: PD Disaggregation and DeepEP
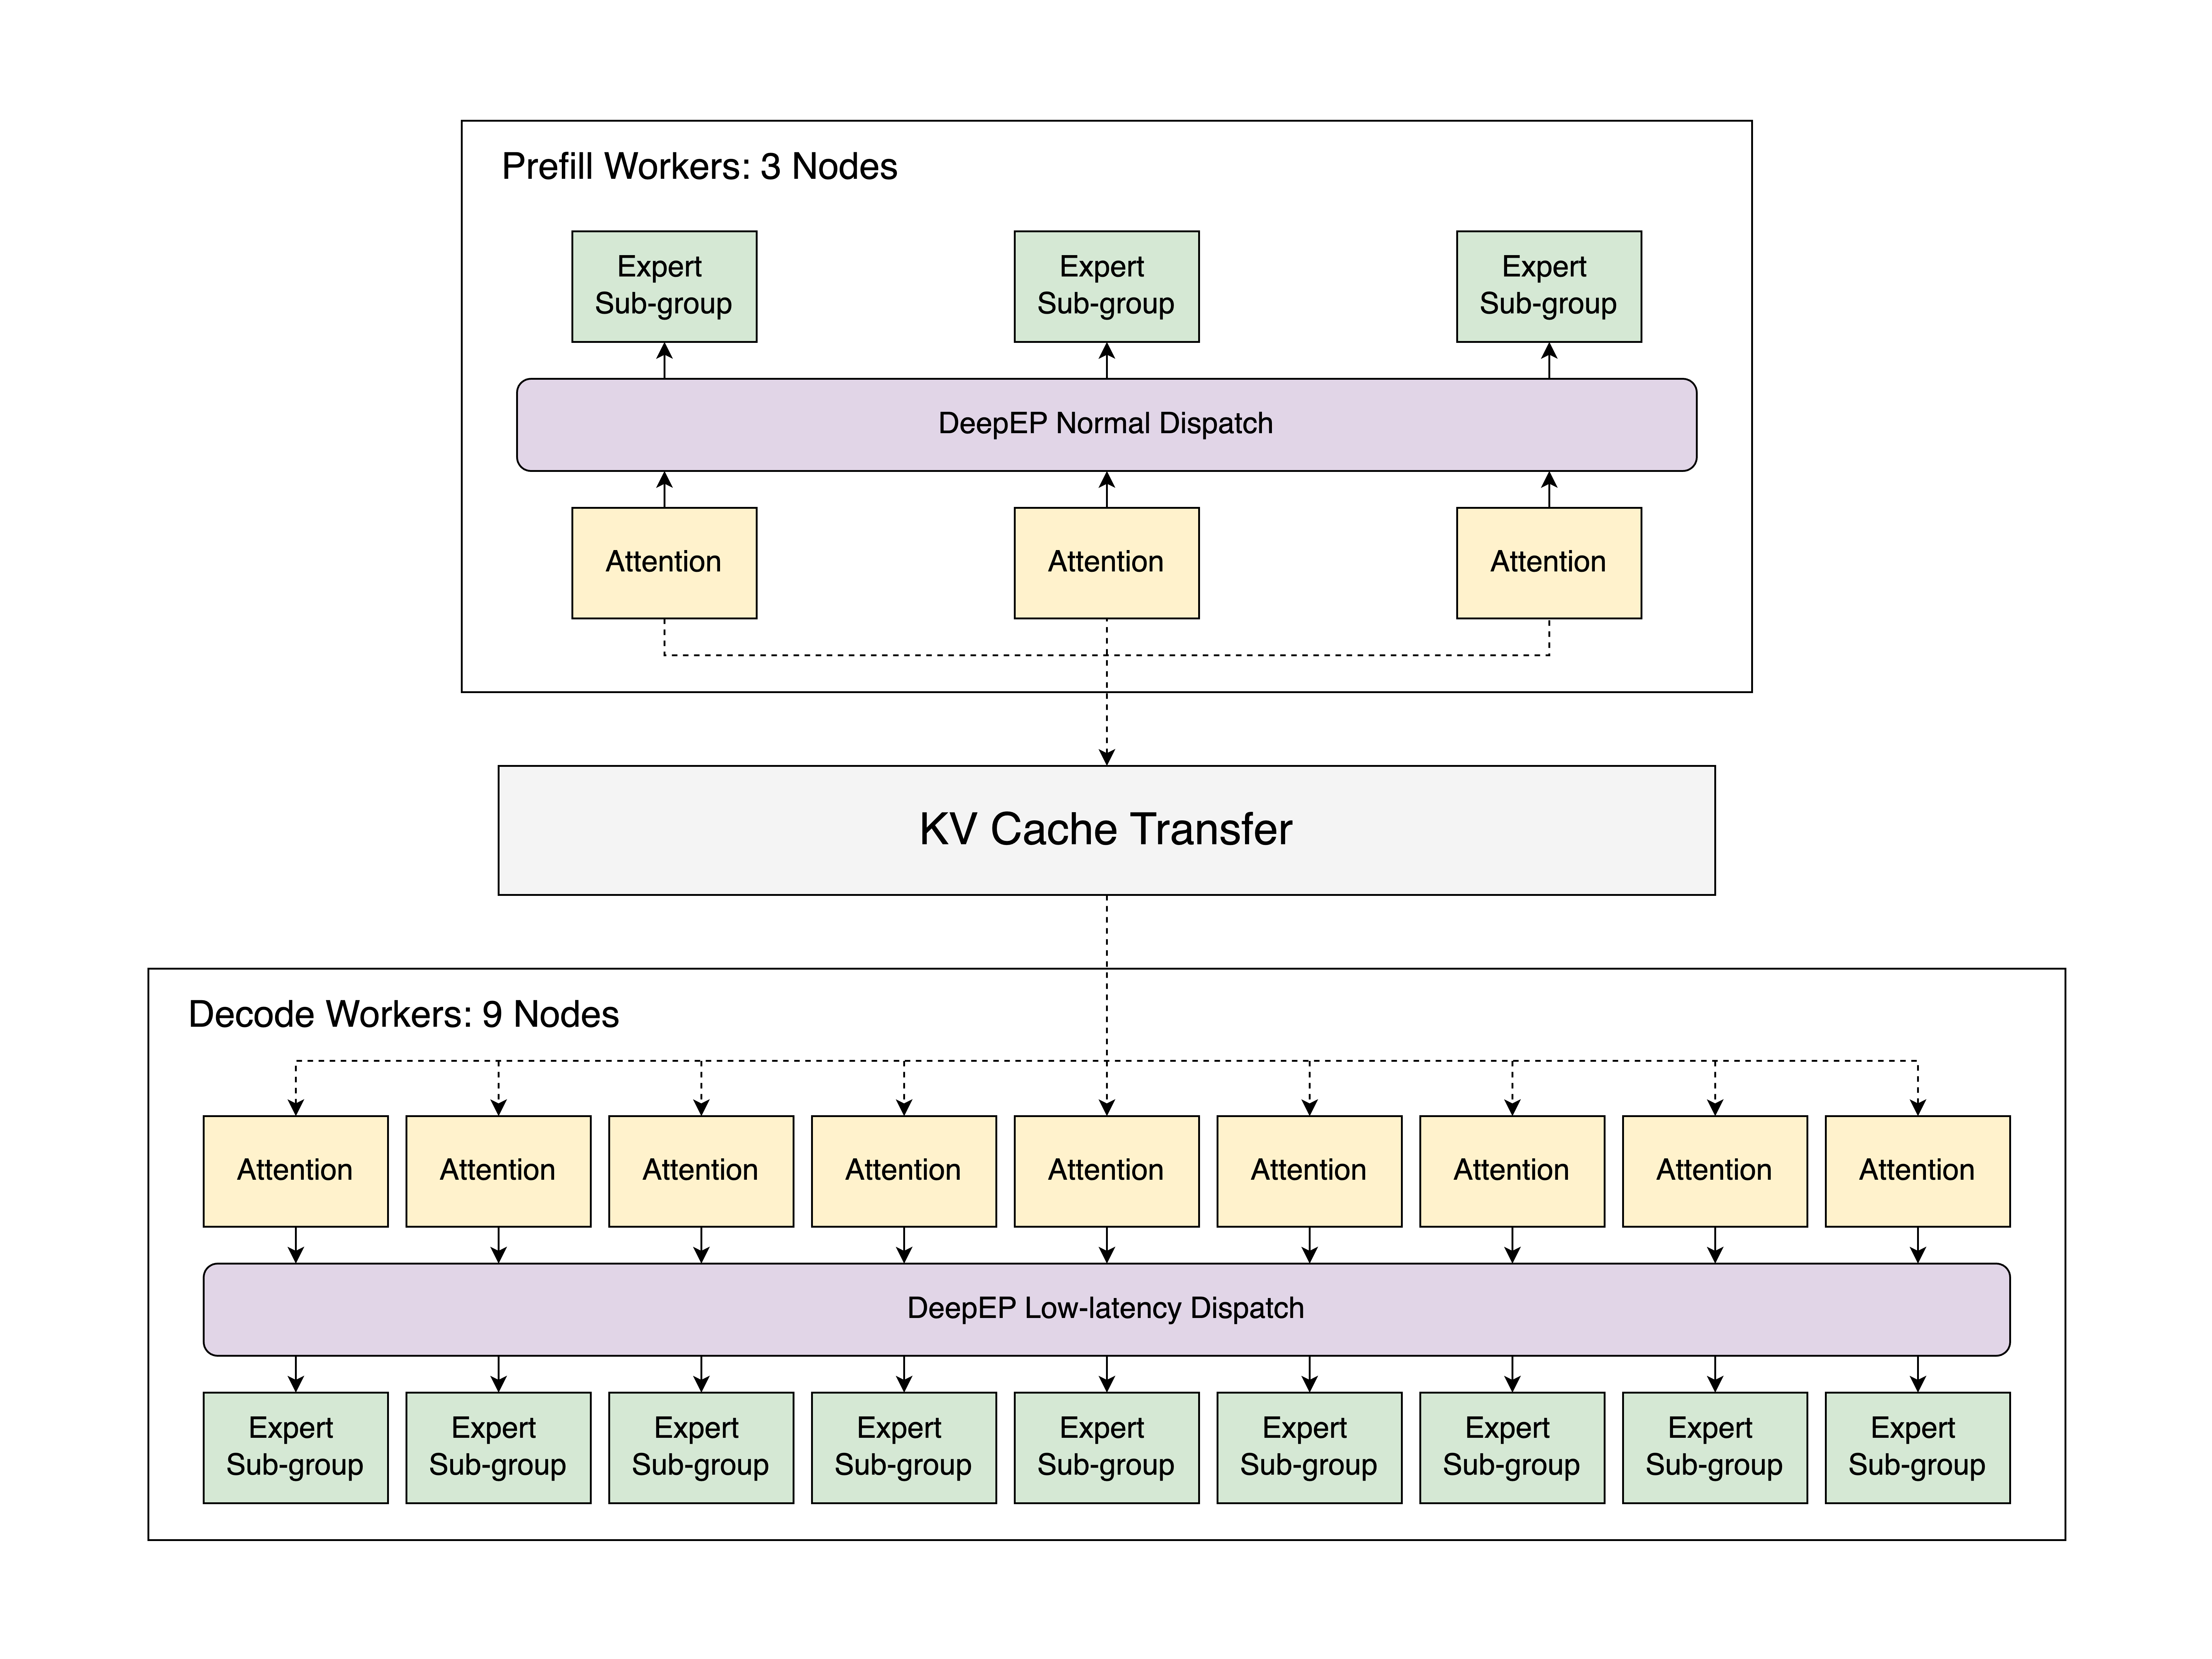
The SGLang deployment framework resolves these systemic inefficiencies through two cornerstone architectural innovations: Prefill-Decoding (PD) Disaggregation and large-scale Expert Parallelism powered by the DeepEP communication library.
- Prefill-Decoding Disaggregation: By physically or logically separating the prefill nodes from the decode nodes within the 96-GPU cluster, infrastructure operators can tailor hardware allocations to the exact workload profile. Prefill nodes are optimized for massive parallel compute throughput, while decode nodes are provisioned to maximize memory bandwidth and minimize time-to-first-token (TTFT).
- Large-Scale Expert Parallelism via DeepEP: Developed natively by the DeepSeek team, DeepEP is a specialized communication library engineered specifically to streamline expert parallelism in MoE models. It circumvents conventional communication inefficiencies by optimizing kernel execution overlap and accelerating token routing across multiple GPUs, ensuring that inter-node chatter does not cripple inference throughput.
| Deployment Dimension | Traditional Co-located Setup | SGLang 96-GPU Optimized Framework |
|---|---|---|
| Hardware Footprint | Variable, often scaled arbitrarily past 256+ GPUs. | Strictly bounded at 96 NVIDIA H100 GPUs. |
| Phase Separation | Prefill and Decode co-resident on same silicon. | Strict Prefill-Decoding (PD) Disaggregation. |
| Expert Routing Mechanism | Standard NCCL collectives / All-to-All bottlenecks. | DeepEP library integration for streamlined EP. |
| Primary Efficiency Gain | High idle times, memory fragmentation under load. | Optimized cluster utilization, minimal TTFT latency. |
Capital Allocation, Risk Mitigation, and Enterprise ROI
From a financial and strategic perspective, the release of this 96-H100 deployment guide acts as a catalyst for risk mitigation in enterprise technology budgets. Historically, corporate adoption of models like DeepSeek-R1 was throttled by prohibitive infrastructure requirements. Organizations unwilling or unable to commit tens of millions of dollars to massive data center expansions were effectively locked out of deploying frontier open-weights intelligence on-premises or in private sovereign clouds.
By demonstrating that a disciplined 96-GPU architecture—when paired with SGLang and DeepEP—can successfully serve these behemoth models, the technical community has radically compressed the capital expenditure curve. Cloud compute architecture can now be scaled horizontally with surgical precision. For Chief Financial Officers, this translates into predictable cloud billing, enhanced capital efficiency, and a clearer path to positive enterprise ROI on generative AI initiatives.
Furthermore, regulatory compliance and data sovereignty mandates—particularly stringent within European financial institutions and healthcare networks—frequently prohibit transmitting sensitive payloads to public multi-tenant clouds. A self-hosted, highly optimized 96-GPU configuration allows regulated enterprises to maintain absolute governance over proprietary data while deploying top-tier reasoning engines locally.
Frequently Asked Questions (People Also Ask)
What is Prefill-Decoding (PD) Disaggregation in the context of DeepSeek deployment?
PD disaggregation is an architectural strategy that separates the initial prompt processing phase (prefilling) from the token generation phase (decoding) across distinct hardware nodes. Because prefilling is compute-intensive and decoding is memory-bandwidth-bound, separating them prevents resource contention, reduces latency spikes, and maximizes overall cluster throughput.
How does the DeepEP library improve Expert Parallelism (EP)?
DeepEP is a communication library custom-built by the DeepSeek engineering team to tackle the specific bottleneck of routing tokens to distributed Mixture-of-Experts across multiple GPUs. It optimizes inter-GPU data transfer and overlapping communication with computation, drastically minimizing the latency overhead traditionally associated with large-scale MoE scaling.
Can this 96-H100 configuration handle both DeepSeek-V3 and DeepSeek-R1?
Yes. LightLLM and SGLang frameworks support various deployment modes tailored for the DeepSeek model family—including DeepSeek-R1, DeepSeek-V2, and DeepSeek-V3. The 96-GPU blueprint provides the necessary parallelism configuration parameters (such as expert parallelism degree and tensor parallelism modes) to accommodate these architectures efficiently.
What are the primary financial benefits for enterprises adopting this deployment model?
By optimizing cluster utilization and proving that frontier models can run on smaller, bounded hardware footprints (96 H100s rather than massive multi-node pods), enterprises can significantly lower their total cost of ownership (TCO), reduce cloud infrastructure waste, and achieve faster ROI on private AI deployments.
Future Outlook and Strategic Milestones
As the artificial intelligence landscape matures past the initial "brute-force scaling" gold rush, efficiency has emerged as the definitive competitive differentiator. The LMSYS SGLang team's May 2025 blueprint marks a turning point where algorithmic ingenuity meets hardware orchestration.
Looking ahead to the remainder of 2025 and into 2026, industry watchers should monitor several critical milestones:
- Adoption by Tier-2 Cloud Providers: Watch for boutique and regional cloud operators offering competitively priced, pre-configured 96-GPU instances tailored specifically for disaggregated MoE inference.
- Integration into Commercial Orchestration Stacks: Anticipate the absorption of DeepEP principles and SGLang PD disaggregation routines into enterprise-grade MLOps platforms, simplifying deployment for non-specialist engineering teams.
- Hardware Diversification: Adaptation of these parallelization strategies to non-NVIDIA accelerators (such as AMD Instinct MI300X and custom enterprise ASICs), further democratizing access to high-efficiency reasoning models.
Ultimately, the message to the market is unambiguous: raw compute might dominate the headline numbers, but systems engineering excellence dictates who captures the economic value. Organizations that master disaggregated, highly parallelized deployment frameworks will dominate the next era of enterprise AI deployment.