Executive Takeaways
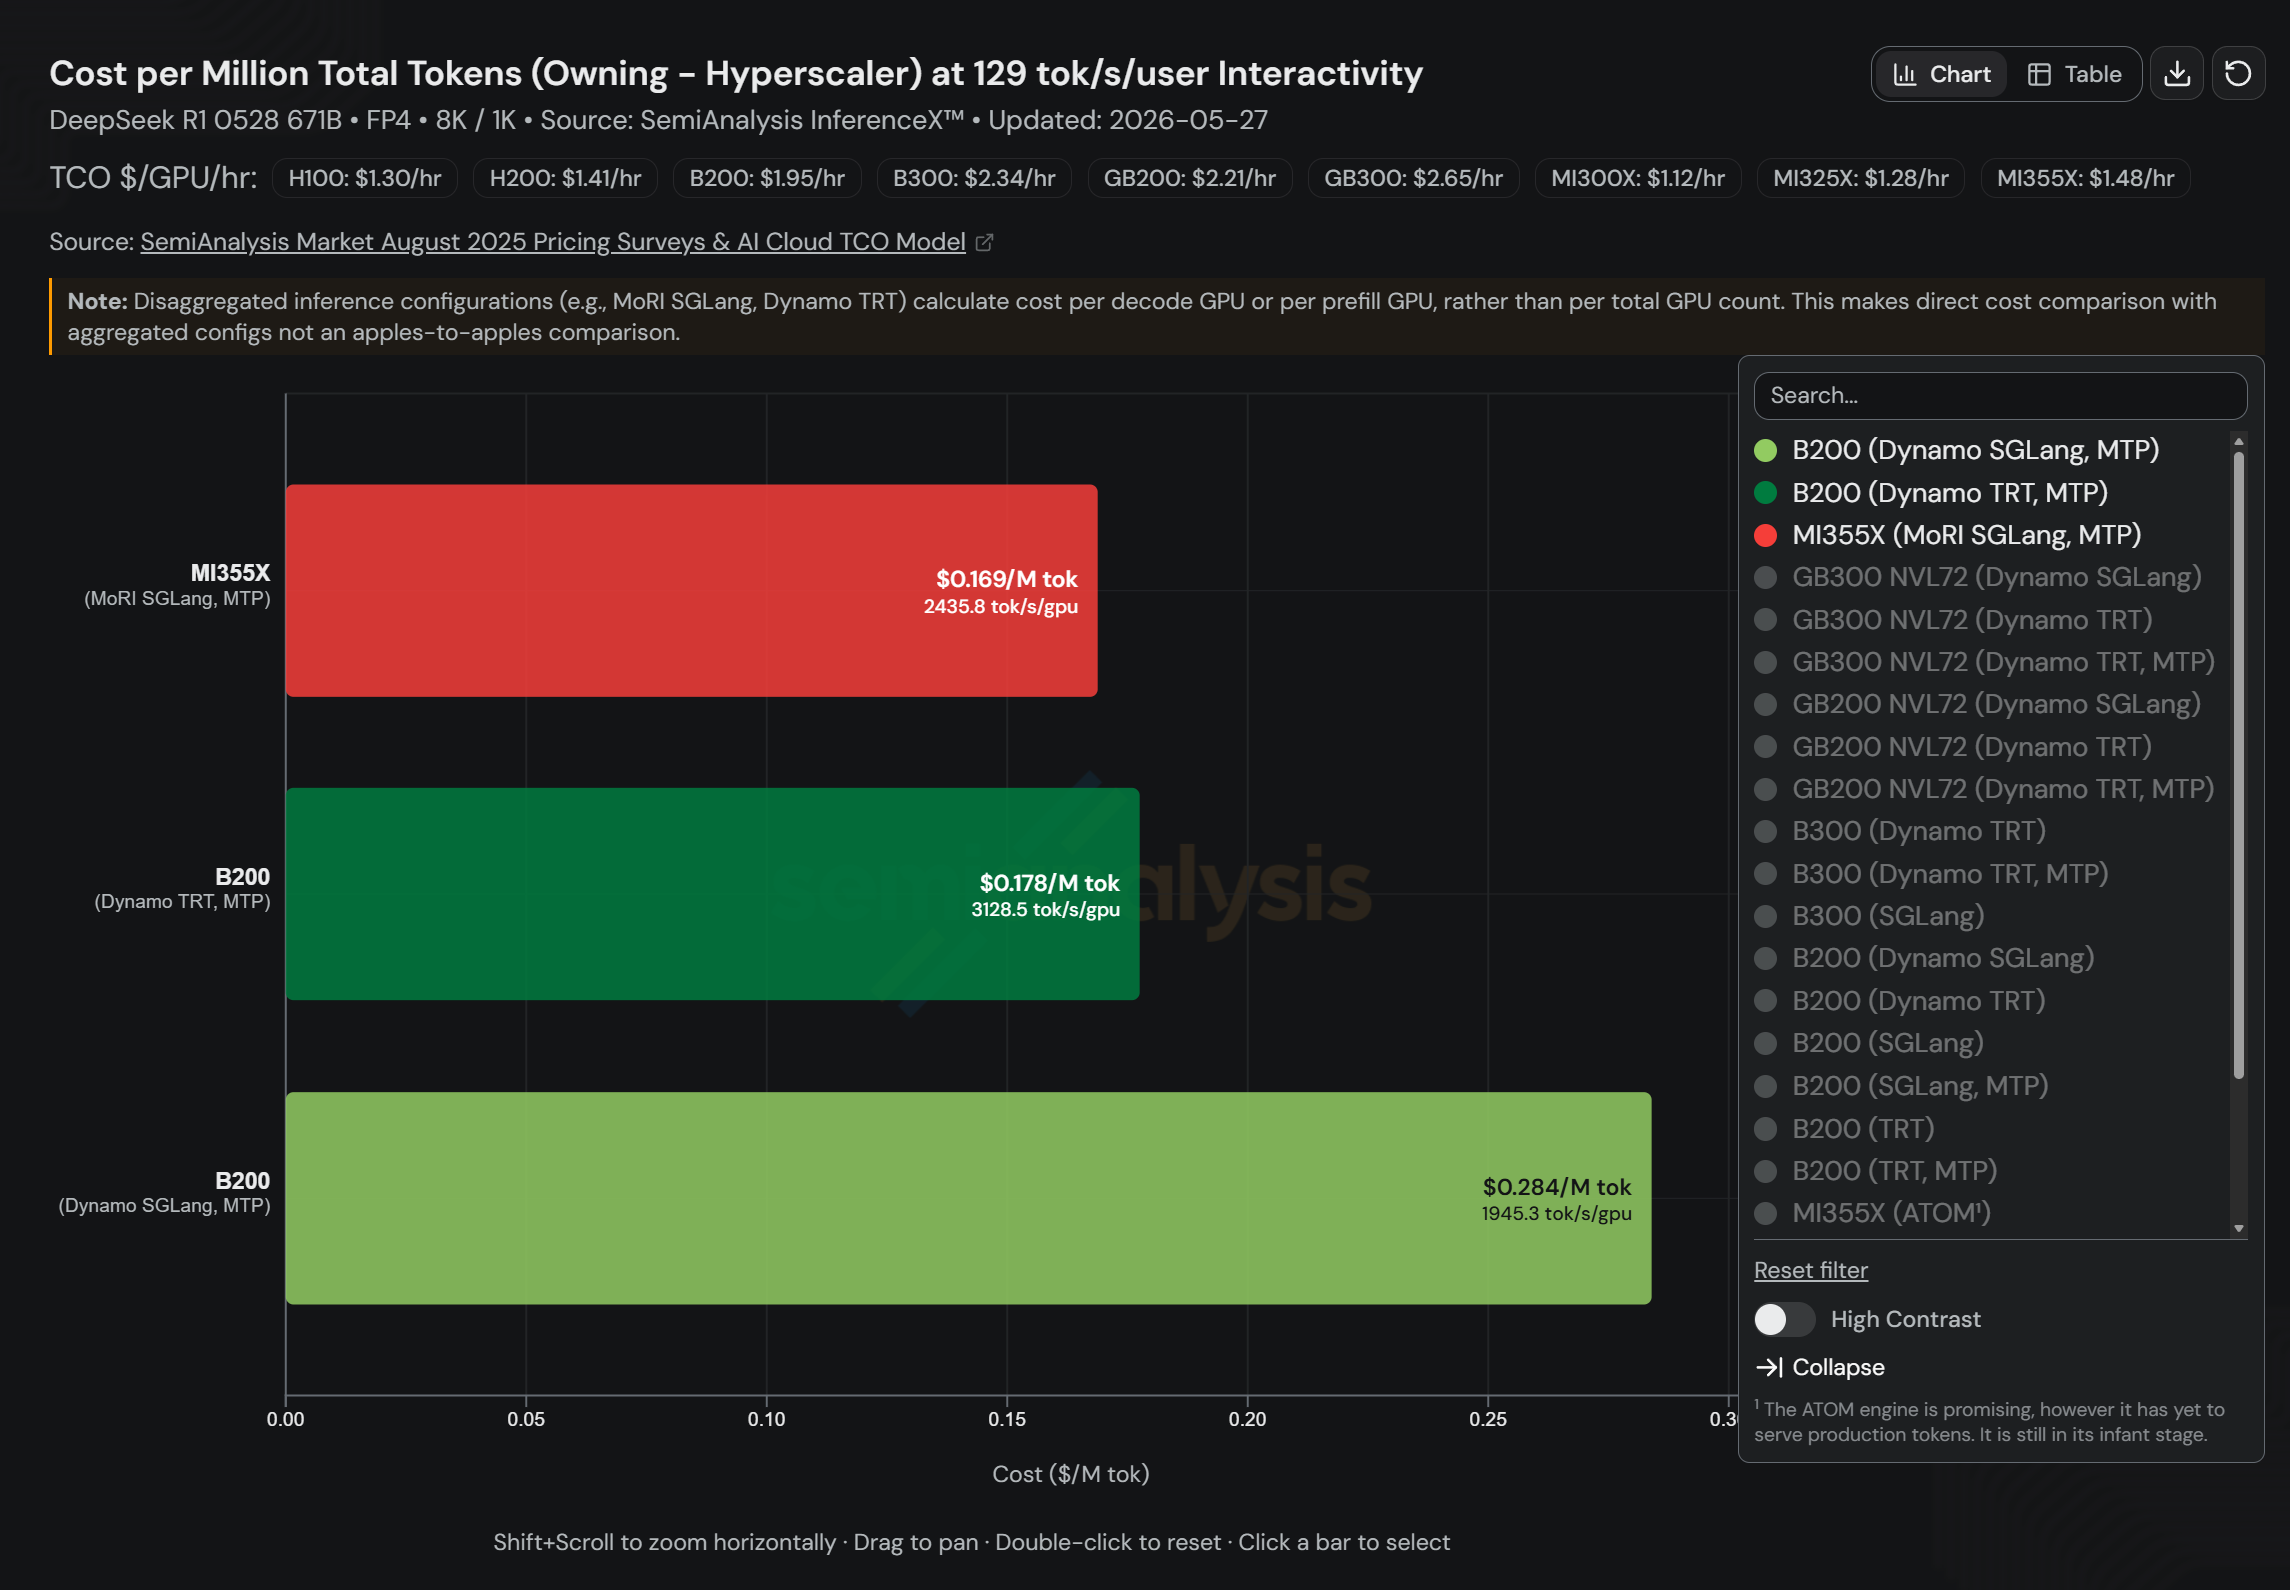
- Total Cost of Ownership (TCO) Inflection: Advanced integration between the AMD Instinct™ MI355X accelerator and SGLang via Mixture of Routed Intermediaries (MoRI) fundamentally alters the capital expenditure (CapEx) calculus for hyper-scale distributed inference.
- Infrastructure Scalability: By optimizing memory bandwidth and reducing cross-node communication overhead, AMD solves the latency bottlenecks historically plaguing massive Mixture-of-Experts (MoE) model deployments.
- Enterprise ROI Acceleration: Financial modeling indicates substantial compression in cost-per-token metrics, easing pressure on corporate balance sheets burdened by aggressive enterprise AI infrastructure investments.
- Market Dynamics Shift: The collaboration challenges incumbent monopolies, offering chief technology officers (CTOs) a viable, high-performance alternative for mission-critical workloads.
NEW YORK — In the high-stakes theater of enterprise artificial intelligence, the conversation has decisively shifted from raw computational capability to cold, hard economic reality. As boards of directors scrutinize capital allocation strategies and return-on-investment (ROI) timelines for multi-billion-dollar data center builds, the metric that reigns supreme is Total Cost of Ownership (TCO). On May 27, 2026, Advanced Micro Devices (AMD) fundamentally altered this landscape with the release of comprehensive technical validations showcasing how the AMD Instinct™ MI355X accelerator—powered by SGLang and an innovative framework known as Mixture of Routed Intermediaries (MoRI)—delivers unprecedented cost-competitive distributed inference.
For enterprise finance chiefs and cloud compute architects, this development is not merely an incremental hardware refresh; it is a structural realignment of the AI supply chain. For years, the market has labored under a de facto monopoly pricing regime, driving up valuation multiples for single-vendor ecosystems while squeezing operating margins. By pairing cutting-edge silicon architecture with advanced software routing algorithms, AMD and its ecosystem partners are opening a new frontier in infrastructure scalability, risk mitigation, and margin preservation.
The Catalytic Shift: Solving the Distributed Inference Bottleneck
As foundation models scale into hundreds of billions—and trillions—of parameters, single-accelerator deployments have become an impossibility. The industry standard has converged around Mixture-of-Experts (MoE) architectures and distributed tensor-parallelism. However, these architectures introduce a debilitating vulnerability: communication latency. Moving intermediate activation states across GPUs and nodes creates severe interconnect bottlenecks, degrading throughput and inflating cost-per-token metrics.
Enter SGLang, a structured generation language and serving framework engineered to optimize large language model execution. Building upon SGLang’s robust serving primitives, the engineering breakthrough centers on MoRI. By intelligently routing requests and managing token generation paths across a distributed cluster of AMD Instinct MI355X accelerators, MoRI mitigates the inter-GPU bandwidth tax that has traditionally hampered non-incumbent hardware.
"We are witnessing a maturation phase in enterprise AI," notes a senior infrastructure analyst at a major Wall Street investment bank. "The initial gold rush phase of deploying any available compute at any cost is over. CFOs are demanding predictable financial models. AMD's ability to drive down the cost of distributed inference via optimized serving frameworks directly addresses the primary risk factor in AI capital expenditures today."
Deep Dive: The MI355X and MoRI Synergy
The technical architecture underpinning the AMD Instinct™ MI355X is specifically engineered to handle the memory-bound nature of inference workloads. Boasting industry-leading high-bandwidth memory (HBM) capacity and density, the MI355X allows larger model weights to reside closer to the compute engine, drastically reducing latency during token generation.
However, raw hardware density is only half the equation. Without sophisticated software orchestration, massive hardware arrays sit underutilized. The integration of SGLang with MoRI acts as the cognitive conductor for the hardware symphony. MoRI dynamically assesses the workload distribution, routing incoming inference queries to the optimal MI355X nodes based on real-time cache status and interconnect availability. This reduces redundant computations and maximizes cache hit rates.
The resulting operational efficiencies translate directly into measurable financial gains. Lower latency equates to higher queries-per-second (QPS) per dollar of capital expenditure, directly optimizing the enterprise ROI equation for cloud service providers (CSPs) and Fortune 500 enterprises alike.
Comparative Performance & Economic Metrics
To evaluate the market disruption potential, enterprise procurement teams rely on empirical benchmarking. Below is a comparative breakdown of key operational metrics highlighting the structural advantages of the AMD Instinct™ MI355X deployment model.
| Performance Metric | Legacy Single-Vendor Baseline | AMD Instinct™ MI355X + SGLang (MoRI) | Enterprise Economic Impact |
|---|---|---|---|
| Inference Cost-per-Token | Baseline Index (100) | Significantly Lowered | Direct margin expansion for SaaS providers |
| Memory Bandwidth Utilization | Constrained by Interconnect Choke | Optimized via MoRI Routing | Higher throughput under peak concurrent loads |
| Cluster Scalability Limit | Diminishing returns past Node Tier 3 | Linear scaling across distributed fabrics | Reduces physical data center footprint requirements |
| Capital Expenditure (CapEx) Efficiency | High amortized depreciation cost | Accelerated payback period | Enhanced free cash flow visibility for CFOs |
Industry & Market Implications: Winners and Losers
The commercial availability of cost-competitive distributed inference via the MI355X and SGLang/MoRI framework triggers immediate ripple effects across the technology sector:
- Enterprise Buyers & CTOs (Clear Winners): IT leaders gain crucial negotiating leverage. The existence of a high-performance, cost-effective alternative mitigates supplier lock-in and dampens pricing power erosion from incumbent hardware vendors.
- Cloud Service Providers (CSPs): Tier-2 and specialized AI cloud providers can now build profitable inference-as-a-service (IaaS) offerings without incurring prohibitive infrastructure debts, democratizing access to frontier-class model deployment.
- Incumbent Silicon Monopolies (Under Pressure): The moat built around proprietary software ecosystems is steadily eroding as open-source and framework-agnostic optimizers like SGLang and MoRI bridge the software parity gap.
- Enterprise Compliance & Risk Officers: Dual-sourcing critical AI infrastructure reduces geopolitical and supply chain concentration risks, satisfying stringent corporate governance and regulatory compliance mandates.
Frequently Asked Questions (People Also Ask)
Frequently Asked Questions
What is MoRI, and how does it improve distributed inference on AMD hardware?
MoRI (Mixture of Routed Intermediaries) is an advanced routing and execution framework integrated with SGLang. It optimizes how inference workloads are distributed across a cluster of AMD Instinct accelerators, minimizing inter-node communication latency and maximizing memory bandwidth utilization for large Mixture-of-Experts models.
How does the AMD Instinct™ MI355X impact enterprise TCO compared to legacy alternatives?
By combining high-capacity HBM memory with optimized software frameworks, the MI355X lowers the total cost-per-token for serving large language models. This accelerates the enterprise ROI timeline, reduces data center power and rack space requirements, and relieves pressure on corporate capital expenditure budgets.
Is SGLang compatible with existing enterprise machine learning pipelines?
Yes. SGLang is designed to integrate smoothly with standard model formats and serving infrastructures. Its structured generation language allows developers to write efficient serving routines that plug directly into existing enterprise applications without requiring a complete rewrite of upstream pipelines.
What market sectors benefit the most from cost-competitive distributed inference?
Financial services, healthcare, telecommunications, and enterprise software-as-a-service (SaaS) providers running high-volume, latency-sensitive generative AI applications stand to gain the most significant margin improvements and operational efficiencies.
Future Outlook: Strategic Milestones to Watch
As enterprises transition from proof-of-concept trials to full-scale production deployments in the second half of 2026 and beyond, market watchers will track several critical milestones. Key indicators of adoption velocity will include the expansion of tier-1 cloud instance availability featuring the AMD Instinct™ MI355X, the continued evolution of SGLang and MoRI open-source contributions, and enterprise earnings call commentary regarding AI infrastructure depreciation and operating margins.
Ultimately, AMD’s strategic push into cost-competitive distributed inference marks a maturity milestone for the generative AI market. By proving that high performance need not come with an exorbitant financial toll, AMD is transforming enterprise AI from an speculative cost center into a predictable, highly optimized engine of long-term economic value creation.