Executive Takeaways
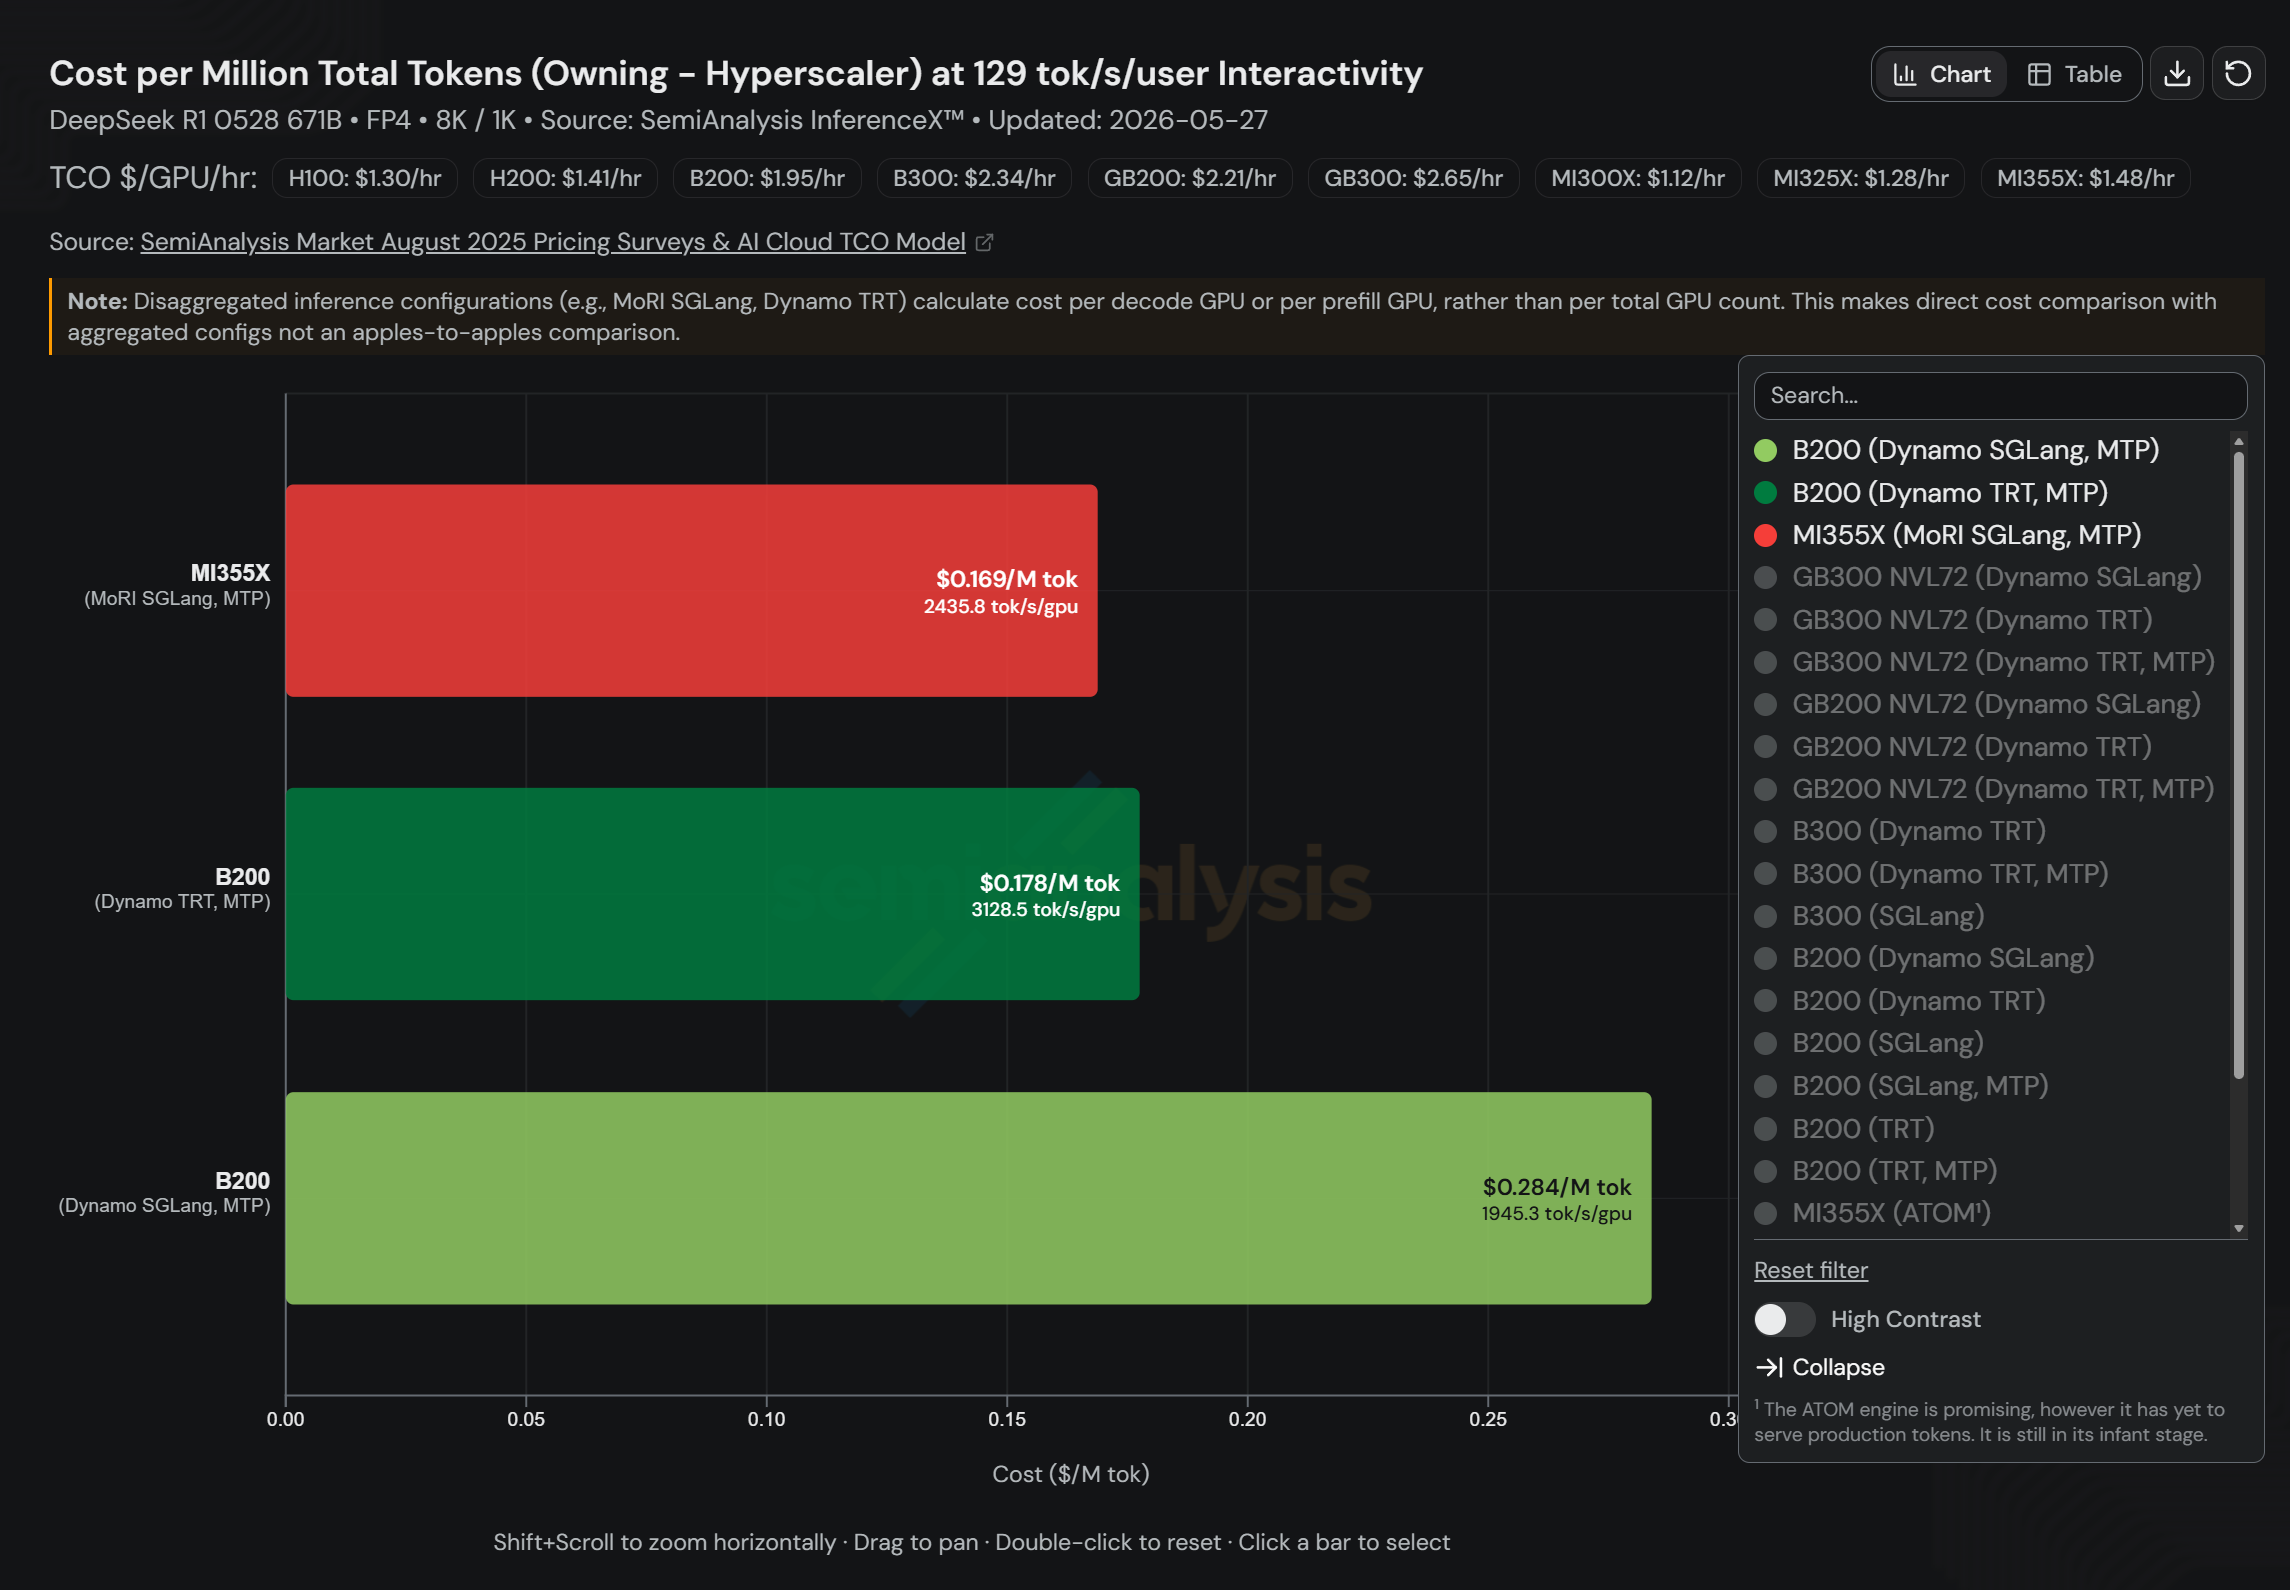
- TCO Breakthrough: AMD’s architectural pairing of the Instinct™ MI355X accelerator with SGLang and Mixture-of-Routing-Interleaved (MoRI) drastically reduces capital and operational expenditures for hyperscale distributed inference.
- Software Stack Maturity: By optimizing state-of-the-art serving frameworks like SGLang, AMD is successfully overcoming historical enterprise hesitancy regarding non-CUDA software ecosystems.
- Market Realignment: The aggressive push for cost-competitive distributed inference threatens incumbent gross margins, triggering a structural reassessment of enterprise ROI and multi-vendor cloud compute architecture.
- Capital Allocation Shift: Chief Information Officers (CIOs) and Chief Technology Officers (CTOs) are accelerating procurement evaluations for heterogeneous hardware to mitigate supplier concentration risks.
SAN FRANCISCO & NEW YORK — In the high-stakes theater of enterprise artificial intelligence, the conversation has violently shifted. For the past thirty-six months, boardroom discussions across Silicon Valley and Wall Street were dominated by raw compute capability, training cluster sizes, and parameter counts. Today, the conversation is anchored entirely in a stark financial reality: Total Cost of Ownership (TCO). As generative AI transitions from experimental proof-of-concept deployments to mission-critical, day-two enterprise production, the economics of token generation have become the ultimate determinant of valuation multiples and enterprise profitability.
Enter Advanced Micro Devices (AMD) with a strategic deployment that is sending ripples through the enterprise hardware oligopoly. Building on the architectural evolution of its data center roadmap, AMD’s release details surrounding the Instinct™ MI355X—coupled with advanced software orchestration via SGLang and the innovative MoRI (Mixture-of-Routing-Interleaved) framework—represent a watershed moment for distributed inference. According to technical disclosures and industry benchmarks released around May 27, 2026, this triumvirate of silicon, serving engine, and algorithmic routing is designed to shatter the status quo of high-cost cloud compute architecture.
The Catalyst: The Shift from Training Monopolies to Inference Economics
To understand the profound market impact of the MI355X combined with SGLang and MoRI, one must examine the macroeconomic pressures currently squeezing enterprise IT budgets. While large language model (LLM) training commands the initial media headlines, inference—the act of serving models to end-users in real-time—accounts for the vast majority of long-term operational expenditure (OpEx) for cloud service providers (CSPs) and Fortune 500 enterprises alike.
As context, early enterprise deployments of massive transformer models were crippled by memory bandwidth bottlenecks, low GPU utilization rates during dynamic token generation, and the sheer capital expense (CapEx) of multi-node cluster setups. Incumbent hardware solutions, while computationally robust, often imposed punishing infrastructure costs that compressed software-as-a-service (SaaS) gross margins. CIOs faced a sobering risk mitigation dilemma: absorb unsustainable cloud compute bills or throttle AI feature rollouts.
AMD’s strategic riposte targets this exact vulnerability. By engineering the Instinct™ MI355X—an accelerator boasting immense High Bandwidth Memory (HBM) capacity and density—alongside bleeding-edge software co-design, AMD is rewriting the ledger. The integration with SGLang, a state-of-the-art serving framework optimized for complex prompt routing and multi-turn generation, introduces unprecedented execution efficiency. When supercharged by MoRI, this architecture minimizes communication overhead across distributed nodes, unlocking a cost-competitive tier of inference previously deemed unattainable outside of closed, proprietary ecosystems.
Deconstructing the Stack: MI355X, SGLang, and MoRI in Production
The technical architecture behind this TCO breakthrough is a masterclass in hardware-software co-design. Achieving high throughput and low latency across distributed inference clusters requires solving the "memory wall" and inter-node communication latency. Here is how AMD’s engineering apparatus tackles the challenge:
- AMD Instinct™ MI355X Architecture: Evolving from the foundational strengths of the MI300 and MI325 series, the MI355X brings maximized HBM density and raw memory bandwidth to the table. This allows massive weights of frontier open-weights models to reside closer to the compute engine, drastically reducing latency spikes caused by off-chip memory swapping.
- SGLang Serving Framework Integration: SGLang has emerged as a premier framework for structured generation and multi-node execution. By utilizing RadixAttention and optimized execution primitives, SGLang eliminates redundant computations across shared prompt prefixes. AMD’s deep optimization of SGLang for ROCm ensures that enterprise deployments achieve near-native performance parity without proprietary lock-in.
- MoRI (Mixture-of-Routing-Interleaved): MoRI serves as the algorithmic glue that optimizes distributed tensor and pipeline parallelism. In large-scale MoE (Mixture of Experts) and dense models, routing overhead can choke cluster efficiency. MoRI dynamically manages token routing and interleave processing, slashing interconnect bottlenecks and maximizing floating-point operations per second (FLOPs) utilization.
The result of this integrated stack is a dramatic compression in the cost-per-thousand-tokens metric, directly improving unit economics for enterprises scaling conversational agents, automated coding assistants, and complex enterprise knowledge retrieval systems.
Verified Data & Specifications Breakdown
A comparative analysis of AMD’s hardware progression highlights the deliberate engineering focus on memory capacity and inference throughput:
| Metric / Specification | AMD Instinct™ MI325X | AMD Instinct™ MI355X | Enterprise Impact |
|---|---|---|---|
| Primary Focus | High-Density Memory / Serving | Cost-Competitive Distributed Inference | Lower CapEx per active user session |
| Software Framework | ROCm / Standard vLLM | Optimized SGLang + MoRI | Accelerated token generation, lower latency |
| Interconnect Efficiency | Standard Infinity Fabric | Enhanced Routing & Interleaved MoRI | Reduced cross-node communication overhead |
| Primary Beneficiary | Early Adopter Hyperscalers | Enterprise Production & Tier-2 CSPs | Mainstream enterprise ROI realization |
Industry & Market Implications: Who Wins, Who Loses
The maturation of AMD’s inference stack carries profound ramifications for market liquidity, vendor valuations, and capital allocation across the global semiconductor and cloud computing sectors:
- The Winners: Enterprise CIOs and Tier-2 CSPs. Organizations long held hostage by single-vendor pricing power now possess a credible, highly optimized alternative. Tier-2 cloud providers can package cost-competitive inference APIs, undercutting legacy pricing models and driving margin expansion.
- The Losers: Incumbent Pricing Power. While market leader NVIDIA continues to command formidable mindshare and developer lock-in via CUDA, the rapid hardening of AMD’s ROCm ecosystem—bolstered by frameworks like SGLang—erodes the moat of proprietary software lock-in. Gross margin pressures will inevitably mount as enterprise procurement teams demand competitive bidding.
- The Financial Market Reaction: Wall Street analysts are recalibrating valuation multiples for semiconductor peers. Companies that demonstrate robust, multi-vendor infrastructure adaptability are viewed as lower-risk investments, mitigating regulatory compliance scrutiny regarding hardware monopolies and stabilizing supply chain liquidity.
Frequently Asked Questions (People Also Ask)
What is the primary advantage of combining the AMD Instinct™ MI355X with SGLang and MoRI?
The core advantage is a radical optimization of Total Cost of Ownership (TCO) for distributed AI inference. By pairing high-capacity memory hardware with SGLang’s advanced prompt execution and MoRI’s intelligent token routing, enterprises achieve higher throughput, lower latency, and significantly reduced infrastructure CapEx compared to legacy single-vendor setups.
How does SGLang improve performance on AMD hardware?
SGLang utilizes specialized serving primitives like RadixAttention and structured generation formats that optimize execution pathways. AMD’s co-engineering efforts ensure these primitives run natively and efficiently on ROCm, effectively eliminating historical software performance gaps between alternative accelerators and CUDA.
What role does MoRI play in distributed LLM serving?
MoRI (Mixture-of-Routing-Interleaved) addresses the critical bottleneck of inter-node communication latency in large distributed clusters. By dynamically optimizing how tokens and expert routing are handled across multiple GPUs, MoRI minimizes idle wait times and maximizes overall cluster compute efficiency.
Is enterprise migration away from legacy CUDA ecosystems risky?
While software migration traditionally posed integration hurdles, modern open-source frameworks like SGLang abstract much of the hardware complexity. Enterprise IT departments are increasingly adopting heterogeneous cloud compute architectures to mitigate supply chain risks and leverage aggressive multi-vendor pricing.
Future Outlook: Strategic Milestones to Watch
As we look toward the remainder of 2026 and into 2027, the trajectory of enterprise AI will be defined by execution speed and economic sustainability. The success of AMD’s MI355X deployment with SGLang and MoRI signals that the era of unquestioned hardware monopolies is drawing to a close, replaced by a hyper-competitive market driven by rigorous TCO metrics.
Key milestones for institutional investors and technology leaders to monitor include:
- The rate of enterprise production migration from proprietary single-vendor stacks to heterogeneous ROCm-powered clusters.
- Further open-source optimizations within the SGLang and vLLM communities tailored specifically for AMD’s upcoming architectural iterations.
- Financial earnings reports from major Tier-2 CSPs highlighting margin expansion derived from lowered inference serving costs.
Ultimately, the equation is clear: companies that master distributed inference economics will dictate the next decade of enterprise software profitability. AMD’s latest technical push ensures it is no longer just a participant in the AI revolution, but a formidable architect of its financial future.