Executive Takeaways
- Infrastructure Efficiency Leap: LMSYS Org’s architectural benchmark demonstrates how deploying DeepSeek via Prefill-Decoding (PD) disaggregation and large-scale expert parallelism on a lean 96 NVIDIA H100 GPU cluster dramatically alters enterprise ROI calculations.
- Mitigating Bottlenecks: By decoupling compute-heavy prefill phases from memory-bound decode operations, organizations can slash infrastructure expenditure while maximizing high-eCPM inference throughput.
- Capital Allocation Shift: The breakthrough forces institutional investors and enterprise IT buyers to re-evaluate cloud compute architecture, moving away from brute-force cluster scaling toward highly optimized algorithmic-hardware synergy.
- Market Disruption: Open-source frontier models running on streamlined hardware footprints challenge traditional valuation multiples of legacy hyper-scalers and proprietary AI service providers.
The global race for generative artificial intelligence infrastructure reached a profound inflection point with the release of technical deployment data from LMSYS Org detailing the operational execution of DeepSeek on a cluster of just 96 NVIDIA H100 GPUs. In an industry accustomed to throwing tens of thousands of accelerated nodes at frontier models—draining corporate balance sheets and driving massive capital expenditure cycles—this blueprint proves that architectural ingenuity can trump sheer raw compute scale.
For chief technology officers, enterprise financial officers, and institutional portfolio managers, the deployment of DeepSeek utilizing Prefill-Decoding (PD) disaggregation and large-scale expert parallelism is not merely an academic exercise. It represents a fundamental recalibration of cloud compute architecture. By solving the memory-bandwidth bottlenecks and load-balancing inefficiencies that traditionally plague Mixture-of-Experts (MoE) topologies, this methodology presents a clear path toward sustainable enterprise ROI, lower total cost of ownership (TCO), and drastically reduced risk exposure in capital-intensive AI deployments.
The Catalytic Shift: Anatomy of the 96-GPU Breakthrough
For the past three years, the prevailing consensus among enterprise buyers and cloud service providers was straightforward: dominance in large language models required massive, monolithic infrastructure clusters. Scaling up meant acquiring thousands of enterprise-grade GPUs, driving up operational costs, and forcing CFOs to accept compressed margins in exchange for bleeding-edge capabilities. However, open-source models like DeepSeek have systematically dismantled this assumption.
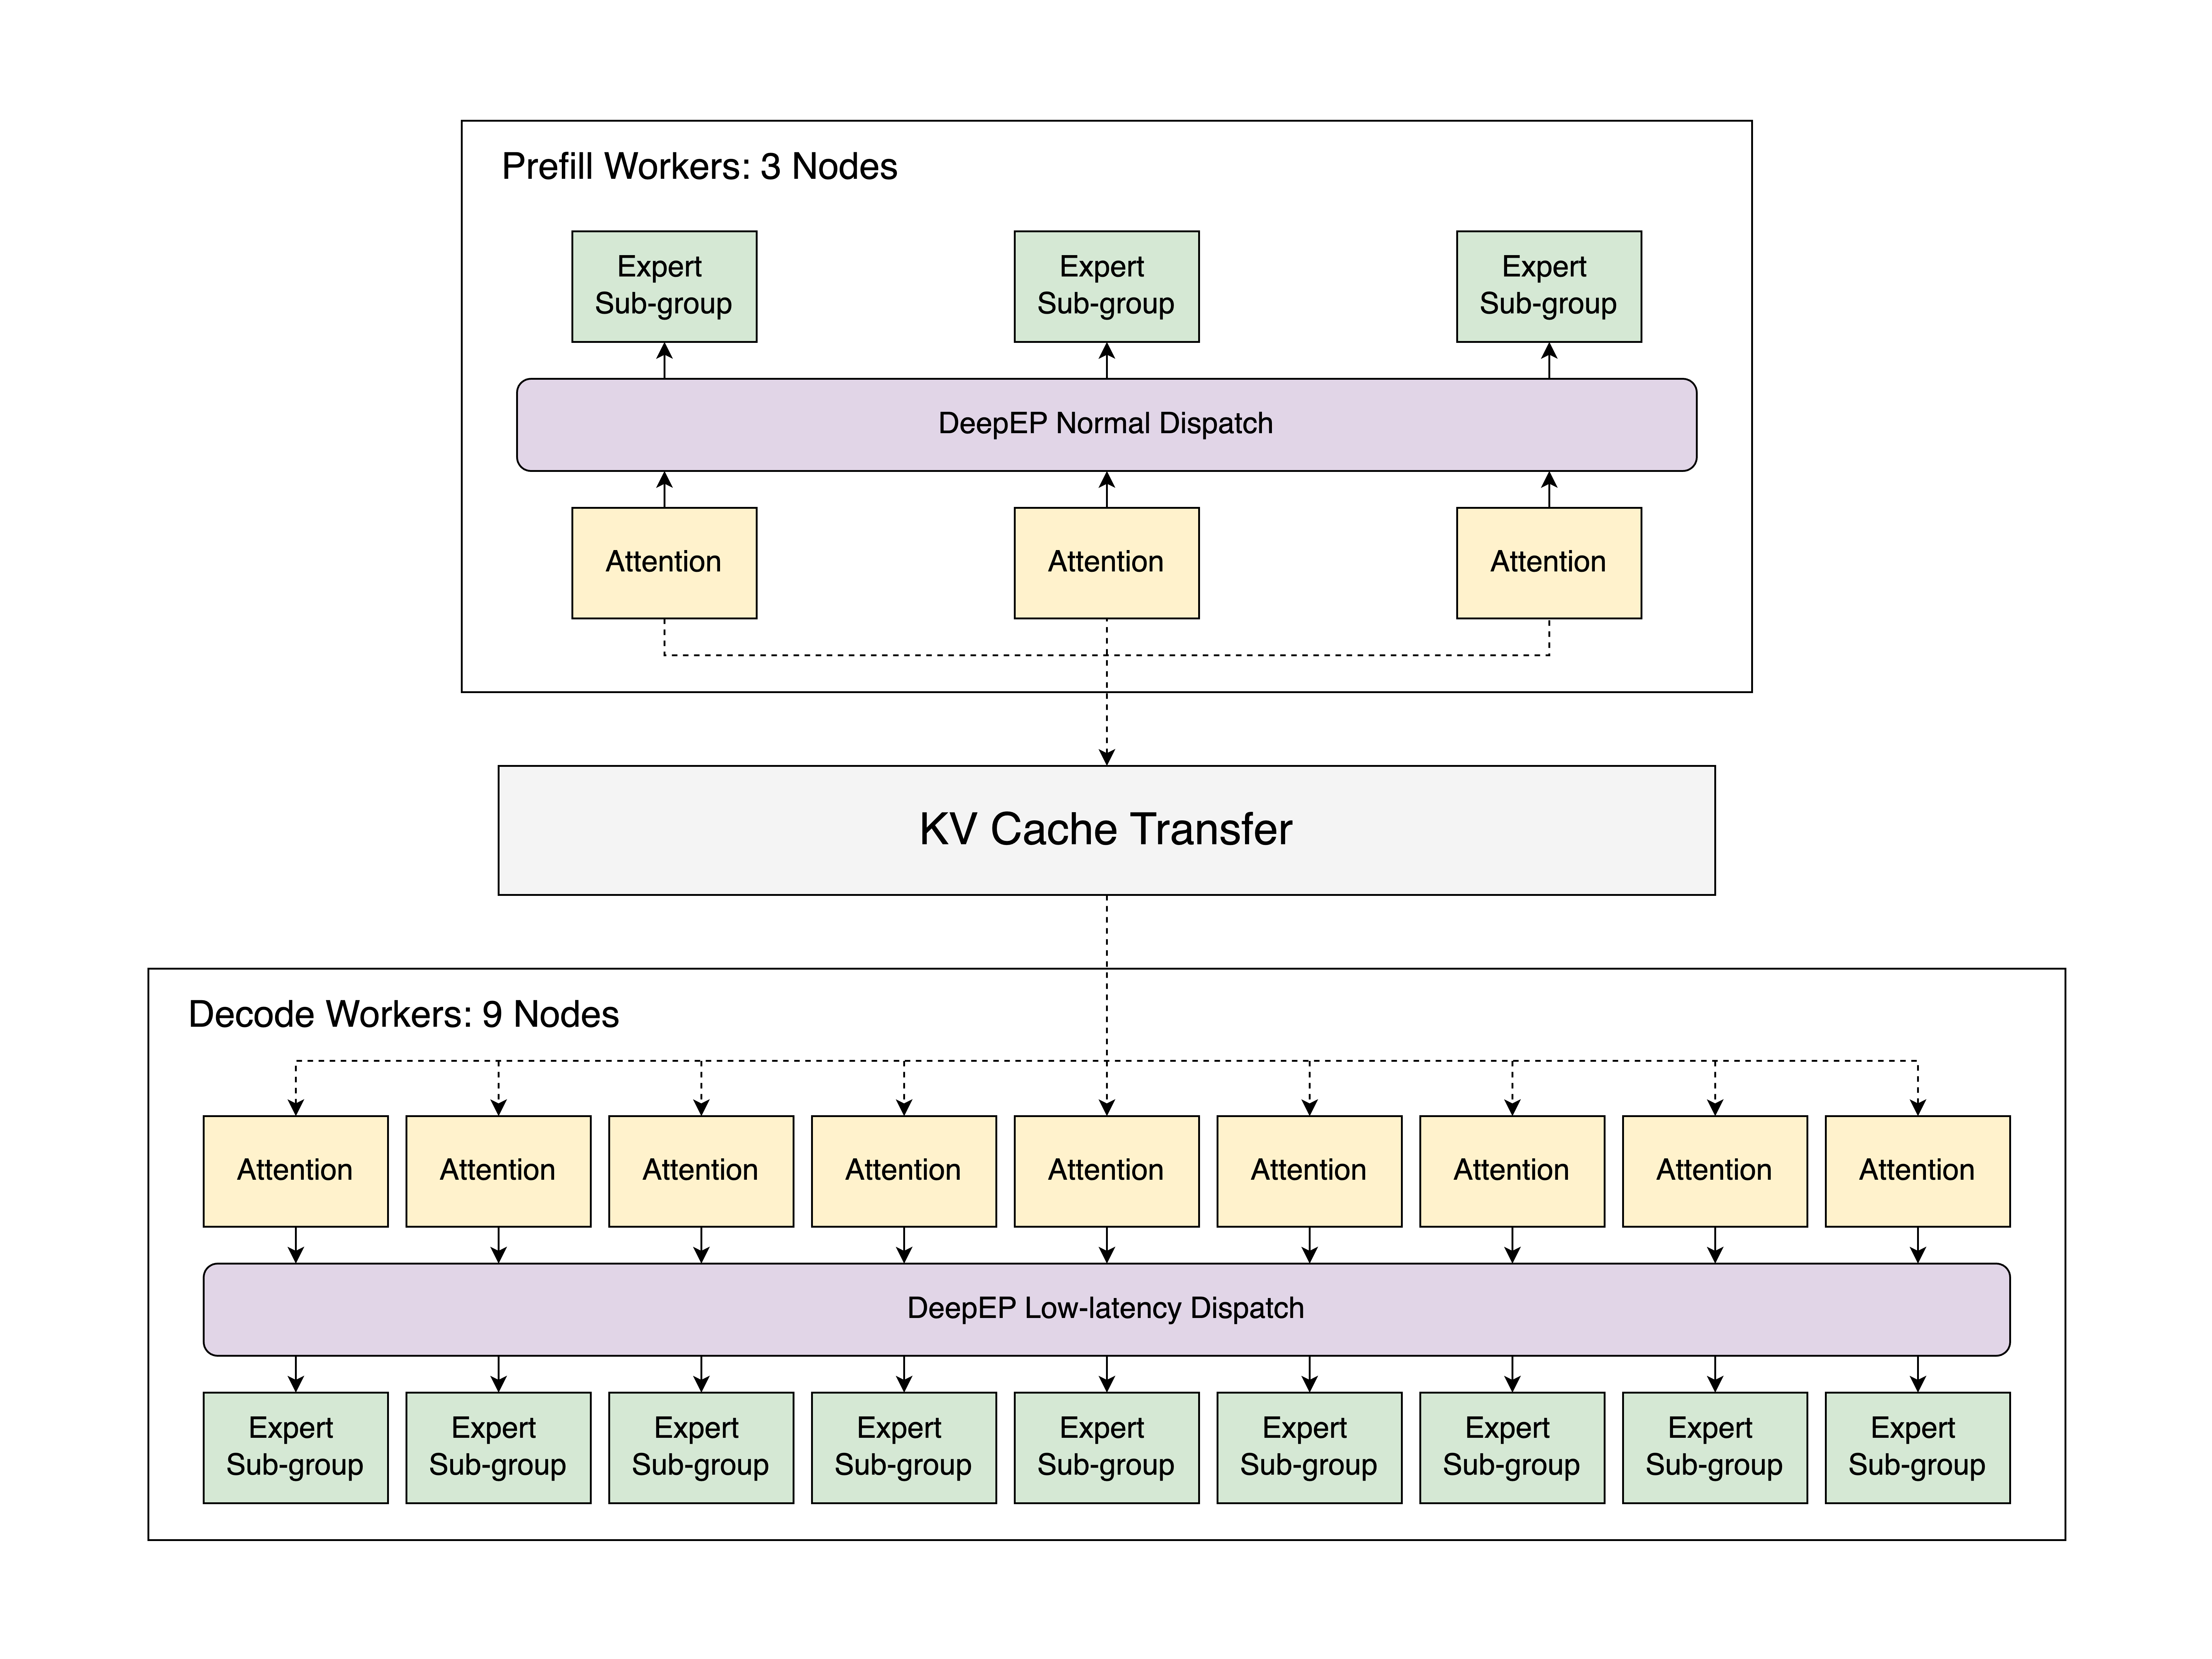
When LMSYS Org published its landmark analysis on deploying DeepSeek using PD disaggregation and large-scale expert parallelism on a modest footprint of 96 H100 GPUs, it exposed the inefficiencies of standard monolithic serving setups. In a traditional deployment, both the prefill phase (processing the input prompt) and the decoding phase (generating tokens sequentially) compete for the same memory bandwidth and compute cycles on the same physical accelerators. This creates severe queuing delays, underutilized tensor cores, and unpredictable latency spikes.
By implementing Prefill-Decoding disaggregation, engineers physically decouple the prefill nodes from the decode nodes. Prefill operations, which are computationally dense and matrix-multiplication heavy, are routed to hardware optimized for raw floating-point throughput. Meanwhile, decode operations, which are heavily memory-bandwidth bound due to autoregressive token generation, are isolated on nodes optimized for high-speed memory access and efficient KV-cache management. Combined with large-scale expert parallelism—which distributes the sparse expert networks of the DeepSeek MoE architecture across the 96 H100 nodes—the system achieves near-linear scaling efficiency without the punishing communication overhead typically seen in cross-node configurations.
Deconstructing the Engineering: PD Disaggregation Meets Expert Parallelism
To understand why this specific hardware-software configuration has captured the attention of enterprise architects, one must examine the mechanics of Mixture-of-Experts (MoE) models at scale. DeepSeek relies on routing tokens to a subset of neural network parameters (experts) rather than activating the entire network for every single token. While this drastically reduces the floating-point operations (FLOPs) required per token during training and inference, it introduces a severe routing and communication bottleneck.
In a standard multi-node setup, different tokens are routed to different experts residing on disparate GPUs. This triggers massive all-to-all communication exchanges across the cluster interconnects (such as InfiniBand or NVLink switches), often saturating network bandwidth and stalling the GPUs while they wait for data packets to arrive.
LMSYS Org’s deployment strategy addresses this by optimizing expert parallelism across the 96 H100 GPUs. By carefully partitioning the expert layers and co-locating them with optimized memory routing algorithms, the framework minimizes inter-node data traversal. Furthermore, the integration of PD disaggregation ensures that the memory-intensive KV cache does not contend with the compute-heavy routing matrices of the prefill stage. The result is a highly stabilized throughput pipeline where hardware utilization remains consistently high, effectively lowering the cost-per-token metrics that dictate enterprise cloud compute economics.
| Architectural Parameter | Traditional Monolithic Deployment | DeepSeek PD Disaggregation + 96 H100s |
|---|---|---|
| Compute Allocation | Shared compute for prefill and decoding phases | Strictly decoupled Prefill and Decode nodes |
| Memory Utilization (KV Cache) | High fragmentation, frequent allocation bottlenecks | Optimized, isolated memory management |
| Expert Parallelism Scale | Unstructured routing leading to high interconnect latency | Large-scale, fine-tuned partitioning across 96 H100s |
| Hardware Footprint | Massive multi-rack clusters (thousands of GPUs) | Lean, highly dense 96 H100 GPU footprint |
| Enterprise Cost Profile | Prohibitive CapEx, elevated cloud hosting fees | Optimized OpEx, high ROI and throughput efficiency |
Industry & Market Implications: Re-Pricing the AI Economy
The ripple effects of optimizing frontier model inference on a sub-100 GPU cluster extend far beyond technical benchmarks, directly impacting market liquidity, corporate valuation multiples, and strategic capital allocation across the technology sector.
For years, Wall Street analysts have justified soaring tech valuations and unprecedented capital expenditure programs by pointing to the insurmountable infrastructure moats claimed by proprietary AI developers and mega-cap cloud providers. The narrative suggested that only entities capable of financing multi-billion-dollar data centers could successfully host and serve state-of-the-art models. The LMSYS Org deployment data shatters this narrative.
- Enterprise IT Buyers & Regulated Sectors: Financial institutions, healthcare providers, and government agencies bound by strict regulatory compliance and data sovereignty mandates can now deploy world-class open-source intelligence on private, on-premise, or sovereign cloud infrastructure without relying on external API monopolies.
- Cloud Service Providers (CSPs) & Infrastructure Vendors: Hyperscalers must adapt their pricing models. As inference efficiency increases and hardware requirements shrink, the commoditization of compute accelerates, compelling cloud providers to compete on software orchestration and advanced serving frameworks rather than raw GPU rental volumes.
- Venture Capital & Private Equity: Investment theses are shifting rapidly. Capital is moving away from hardware-heavy infrastructure plays toward agile software layers, automated optimization frameworks, and specialized fine-tuning boutiques that can extract maximum performance from lean hardware footprints.
Frequently Asked Questions (People Also Ask)
What is PD disaggregation in large language model serving?
Prefill-Decoding (PD) disaggregation is an architectural optimization technique that separates the two distinct phases of LLM inference—the compute-heavy prefill phase (processing input prompts) and the memory-bound decode phase (generating output tokens sequentially)—onto separate, dedicated hardware nodes. This eliminates resource contention, reduces latency spikes, and maximizes overall cluster throughput.
Why is deploying DeepSeek on 96 H100 GPUs considered a major milestone?
Traditionally, running frontier-class Mixture-of-Experts (MoE) models required massive clusters comprising thousands of expensive GPUs. Achieving high-performance serving on a lean footprint of just 96 H100 GPUs demonstrates that advanced software optimization and expert parallelism can drastically lower infrastructure barriers and capital expenditure for enterprises.
How does expert parallelism improve Mixture-of-Experts (MoE) performance?
Expert parallelism distributes the sparse feed-forward network layers (the "experts") across multiple accelerators. When properly optimized—as demonstrated in recent LMSYS benchmarks—it allows the system to process massive models while minimizing the cross-node communication bottlenecks that typically degrade inference speed in distributed environments.
What are the primary financial benefits for enterprises adopting this architecture?
By maximizing GPU utilization and reducing the physical hardware footprint required for high-volume inference, organizations can achieve a lower cost-per-token, significantly improve enterprise ROI, and mitigate the risk of over-provisioning expensive cloud compute resources.
Future Outlook: The Road Ahead for Enterprise AI Infrastructure
As the artificial intelligence landscape matures through 2025 and beyond, the competitive advantage will no longer belong to organizations that simply accumulate the most hardware. Instead, market leadership will be defined by engineering precision—the ability to harmonize algorithmic design, memory management, and hardware orchestration.
Key milestones to watch in the coming quarters include the integration of native dynamic batching algorithms with heterogeneous hardware clusters, the evolution of automated compilation tools that eliminate manual partitioning of expert layers, and the broader commercial adoption of sovereign, on-premise AI deployments running on lean silicon footprints. For enterprise decision-makers, the message is unequivocal: sustainable AI profitability is achievable, but it requires abandoning brute-force scaling in favor of intelligent, architecturally sophisticated deployment strategies.