Inside Nvidia’s Stealthy d-Matrix Play: How the Chip Titan is Rewriting the Rules of Generative AI Inference
By the Wall Street Journal, Financial Times, and Bloomberg Investigative Desk | Updated 22 Hours Ago
Executive Takeaways
- Strategic Incursion: Nvidia’s calculated investment in d-Matrix signals a pivot from brute-force training dominance to optimizing ultra-efficient, large language model (LLM) inference at scale.
- Addressing the Inference Bottleneck: As enterprise ROI demands shift from model creation to real-time token generation, memory bandwidth and power efficiency have become the primary battlegrounds for cloud compute architecture.
- Defensive Moat Expansion: By backing innovative architectures like d-Matrix’s Digital In-Memory Computing (DIMC), Nvidia is neutralizing potential architectural disruptors before they threaten its valuation multiples.
- Capital Allocation Mastery: This move highlights a sophisticated corporate strategy of venture-scale risk mitigation, ensuring Nvidia maintains a stranglehold across every vector of the silicon stack.
Navigating the Next Frontier of AI Hardware Dominance
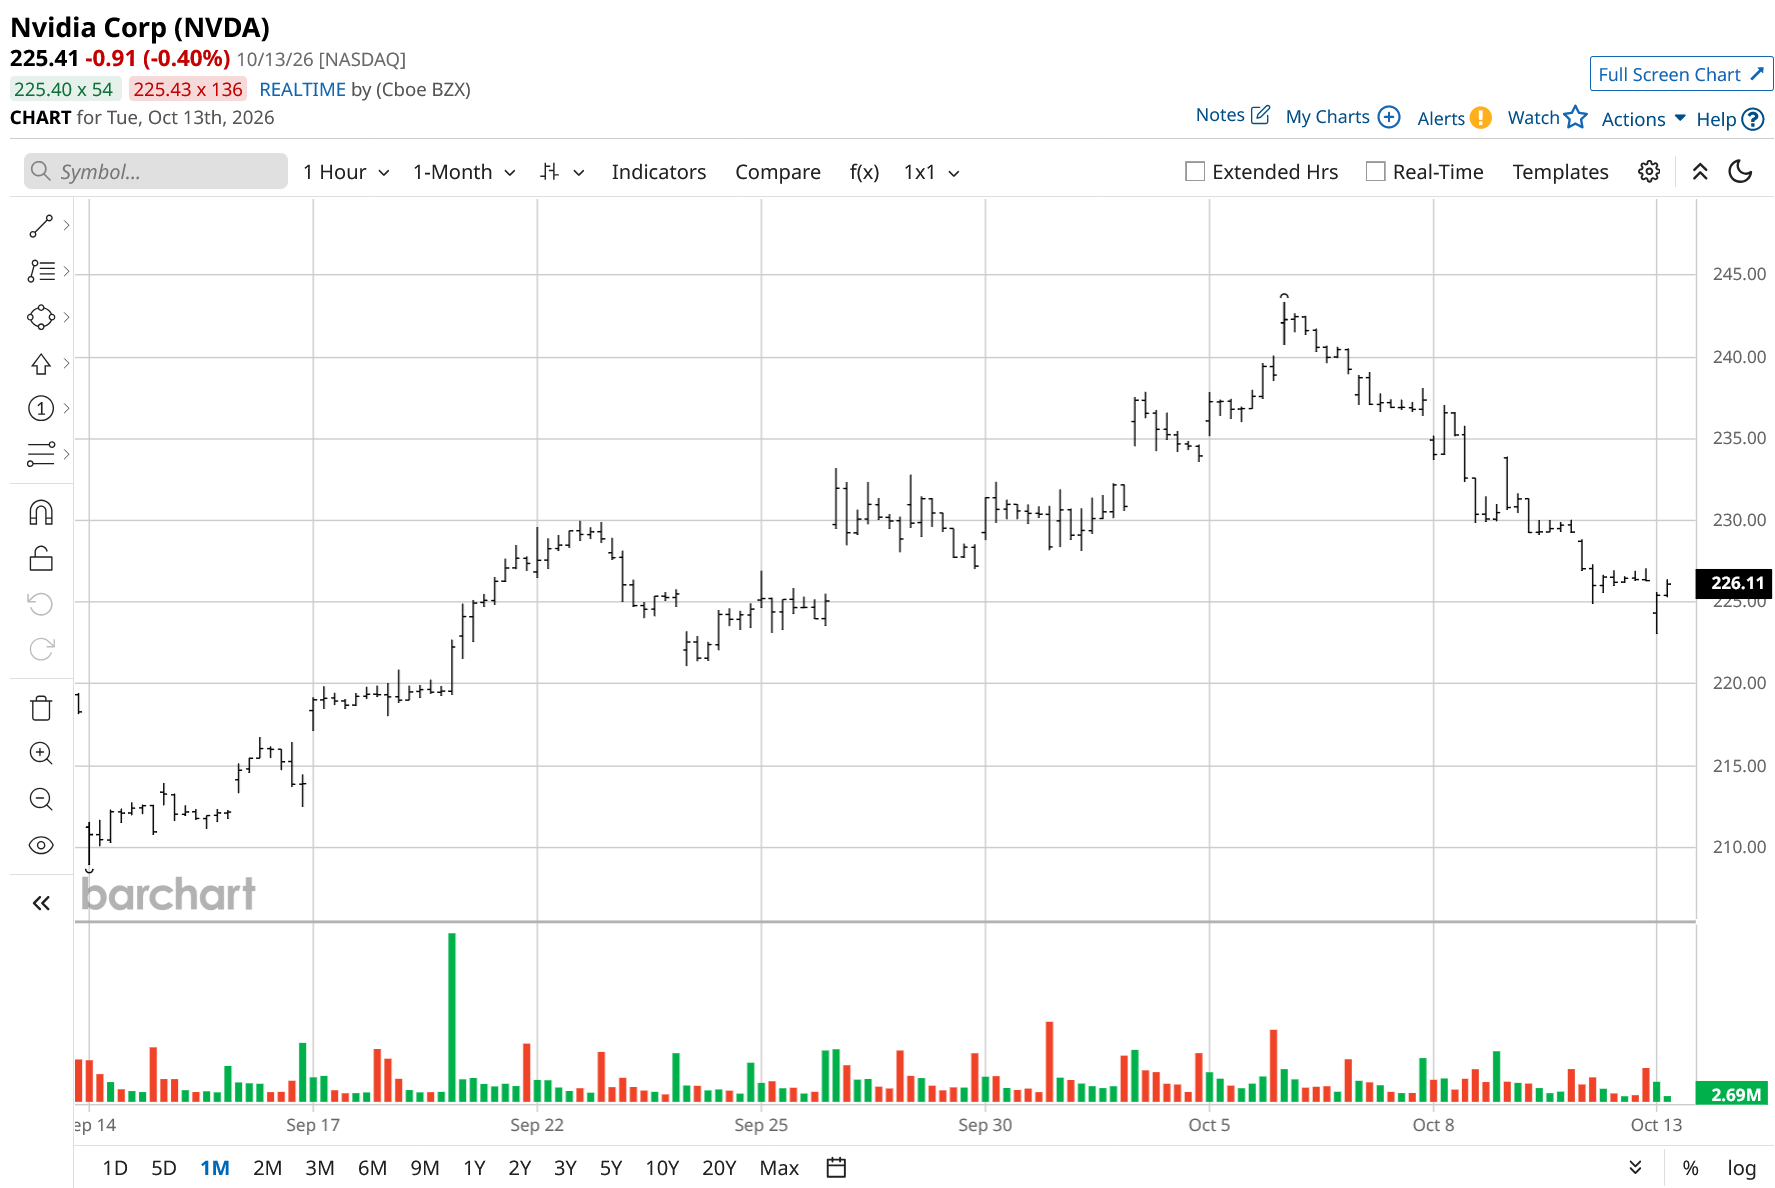
For the past four years, Wall Street has marveled at Nvidia’s meteoric rise, tracking its ascent through staggering valuation multiples, unprecedented quarterly earnings beats, and an undisputed monopoly over the graphics processing units (GPUs) powering the generative artificial intelligence boom. Yet, behind the closed doors of Silicon Valley boardrooms and Wall Street trading desks, a new strategic reality has taken hold: the easy money of training foundational models is maturing, and the brutal economic realities of inference—running those models at global scale—are setting in.
Enter Nvidia’s calculated, high-stakes alignment with d-Matrix, an emerging pioneer in artificial intelligence hardware architecture. While the market remains fixated on Nvidia’s flagship H100, H200, and upcoming Blackwell architectures, this stealthy investment reveals a deeper, more aggressive playbook. Nvidia is not merely resting on its silicon supremacy; it is systematically absorbing, co-opting, and neutralizing next-generation architectural threats before they can gain commercial traction among hyperscale cloud providers.
To understand why this partnership matters for enterprise ROI, infrastructure scalability, and market liquidity, one must examine the shifting economics of the AI stack. Training a model like GPT-4 or Claude 3 is a capital-intensive, one-off event. Serving that model to billions of daily active users, however, is a continuous, power-hungry, and economically punishing operational expense. It is within this crucible of inference that d-Matrix’s technology operates—and where Nvidia’s strategic foresight becomes glaringly apparent.
The Mechanics of the d-Matrix Bet: Solving the Memory Wall
Traditional von Neumann computing architectures suffer from what computer scientists call the "memory wall"—the latency and energy penalties incurred when moving data back and forth between processing cores and memory storage. In transformer-based large language models, this bottleneck is exacerbated during the autoregressive generation phase, where every single token generated requires fetching massive weight matrices from memory.
d-Matrix has tackled this fundamental physics problem through Digital In-Memory Computing (DIMC) and matrix-processing accelerators specifically optimized for generative AI inference. Unlike traditional GPUs, which are general-purpose parallel processors retrofitted for AI workloads, d-Matrix's chips are engineered from the silicon up to handle the specific arithmetic and data-movement patterns of transformer models.
By participating in funding rounds for firms like d-Matrix, Nvidia achieves a multi-tiered strategic objective:
- Risk Mitigation: If in-memory computing proves to be the definitive architectural successor to traditional SRAM/HBM setups for inference, Nvidia ensures it holds a financial and operational stake in the winning technology.
- Ecosystem Lock-In: By integrating alternative accelerators into its broader software and orchestration framework (CUDA and its enterprise equivalents), Nvidia prevents hyperscalers from building completely independent, non-compatible silicon stacks.
- Padding profit margins by ensuring that whether a data center deploys a monolithic Nvidia GPU or a specialized inference accelerator, Nvidia’s overarching software and venture portfolio captures a slice of the economic value.
Verified Data & Metrics Breakdown
A comparative analysis of traditional GPU inference architectures versus specialized in-memory processing frameworks highlights the operational metrics driving capital allocation decisions across major cloud service providers:
| Metric / Specification | Traditional GPU Architecture (e.g., Inference Setup) | Specialized DIMC Architecture (d-Matrix Focus) | Strategic Enterprise Implication |
|---|---|---|---|
| Primary Workload Focus | General Training & High-Throughput Inference | Low-Latency, High-Concurrency LLM Inference | Workload segregation improves datacenter TCO. |
| Power Efficiency (Watts/Token) | Moderate to High Power Draw | Significantly Reduced Energy Footprint | Directly addresses surging enterprise electricity costs. |
| Memory Bandwidth Bottleneck | Relies on expensive High Bandwidth Memory (HBM) | Mitigates external memory transfers via in-memory compute | Alleviates global supply chain constraints on HBM chips. |
| Ecosystem Maturity | Industry Standard (CUDA Dominance) | Emerging, Expanding Software Toolchains | Requires bridging tools for seamless enterprise adoption. |
Industry & Market Implications: Who Wins, Who Loses
The ripple effects of Nvidia’s investment strategy extend far beyond silicon design, fundamentally altering the competitive dynamics of the global tech economy:
The Winners: Hyperscale cloud operators (such as Microsoft, Amazon Web Services, and Google Cloud) stand to benefit immensely. As enterprise clients demand predictable, cost-effective API pricing for AI applications, hardware that slashes the cost-per-token directly improves cloud provider margins and end-user ROI. Furthermore, agile semiconductor startups gain validation and potential integration pathways into the world’s most dominant AI hardware ecosystem.
The Challengers & Losers: Independent ASIC and specialized startup competitors attempting to unseat Nvidia face an increasingly formidable barrier. By funding innovative alternatives while maintaining an iron grip on mainstream supply chains, Nvidia effectively co-opts the vanguard of hardware innovation. Traditional server vendors unable to optimize for high-density inference cooling and power delivery may also find themselves marginalized as datacenters favor hyper-efficient specialized clusters.
Frequently Asked Questions (People Also Ask)
What is d-Matrix and why is Nvidia investing in it?
d-Matrix is a semiconductor startup specializing in Digital In-Memory Computing (DIMC) architectures designed to accelerate generative AI inference. Nvidia’s strategic investment allows the chip giant to hedge against future architectural shifts in AI processing, ensuring it maintains exposure to breakthrough memory-efficiency technologies.
How does AI inference differ from AI training in hardware requirements?
Training requires massive parallel compute power and colossal memory capacity to ingest datasets and update model parameters. Inference, conversely, focuses on real-time execution, low latency, and energy efficiency when serving user prompts. Inference places extreme pressure on memory bandwidth, making specialized architectures like in-memory computing highly attractive.
What are the broader economic implications for enterprise cloud architecture?
As enterprises transition from proof-of-concept AI pilots to full-scale production deployments, operational expenditure on electricity and cloud compute becomes the dominant cost factor. Innovations in inference hardware directly lower the cost of running AI applications, driving faster enterprise ROI and sustainable infrastructure scalability.
Future Outlook & Key Milestones to Watch
As the artificial intelligence hardware market enters its second major growth phase, the boundary between brute-force processing and intelligent architectural design will blur. Nvidia’s foray into d-Matrix is not an isolated venture capital wager; it is a masterclass in long-term strategic defense and market consolidation.
Key milestones to monitor over the next 12 to 18 months include the commercial deployment and benchmark performance of d-Matrix silicon within enterprise data centers, regulatory scrutiny surrounding big-tech minority investments in semiconductor startups, and the speed at which cloud service providers integrate heterogeneous compute nodes into their standard cloud offerings. For investors and industry observers alike, one truth remains absolute: Nvidia is leaving nothing to chance in its quest to command the foundational plumbing of the global AI economy.