Executive Takeaways
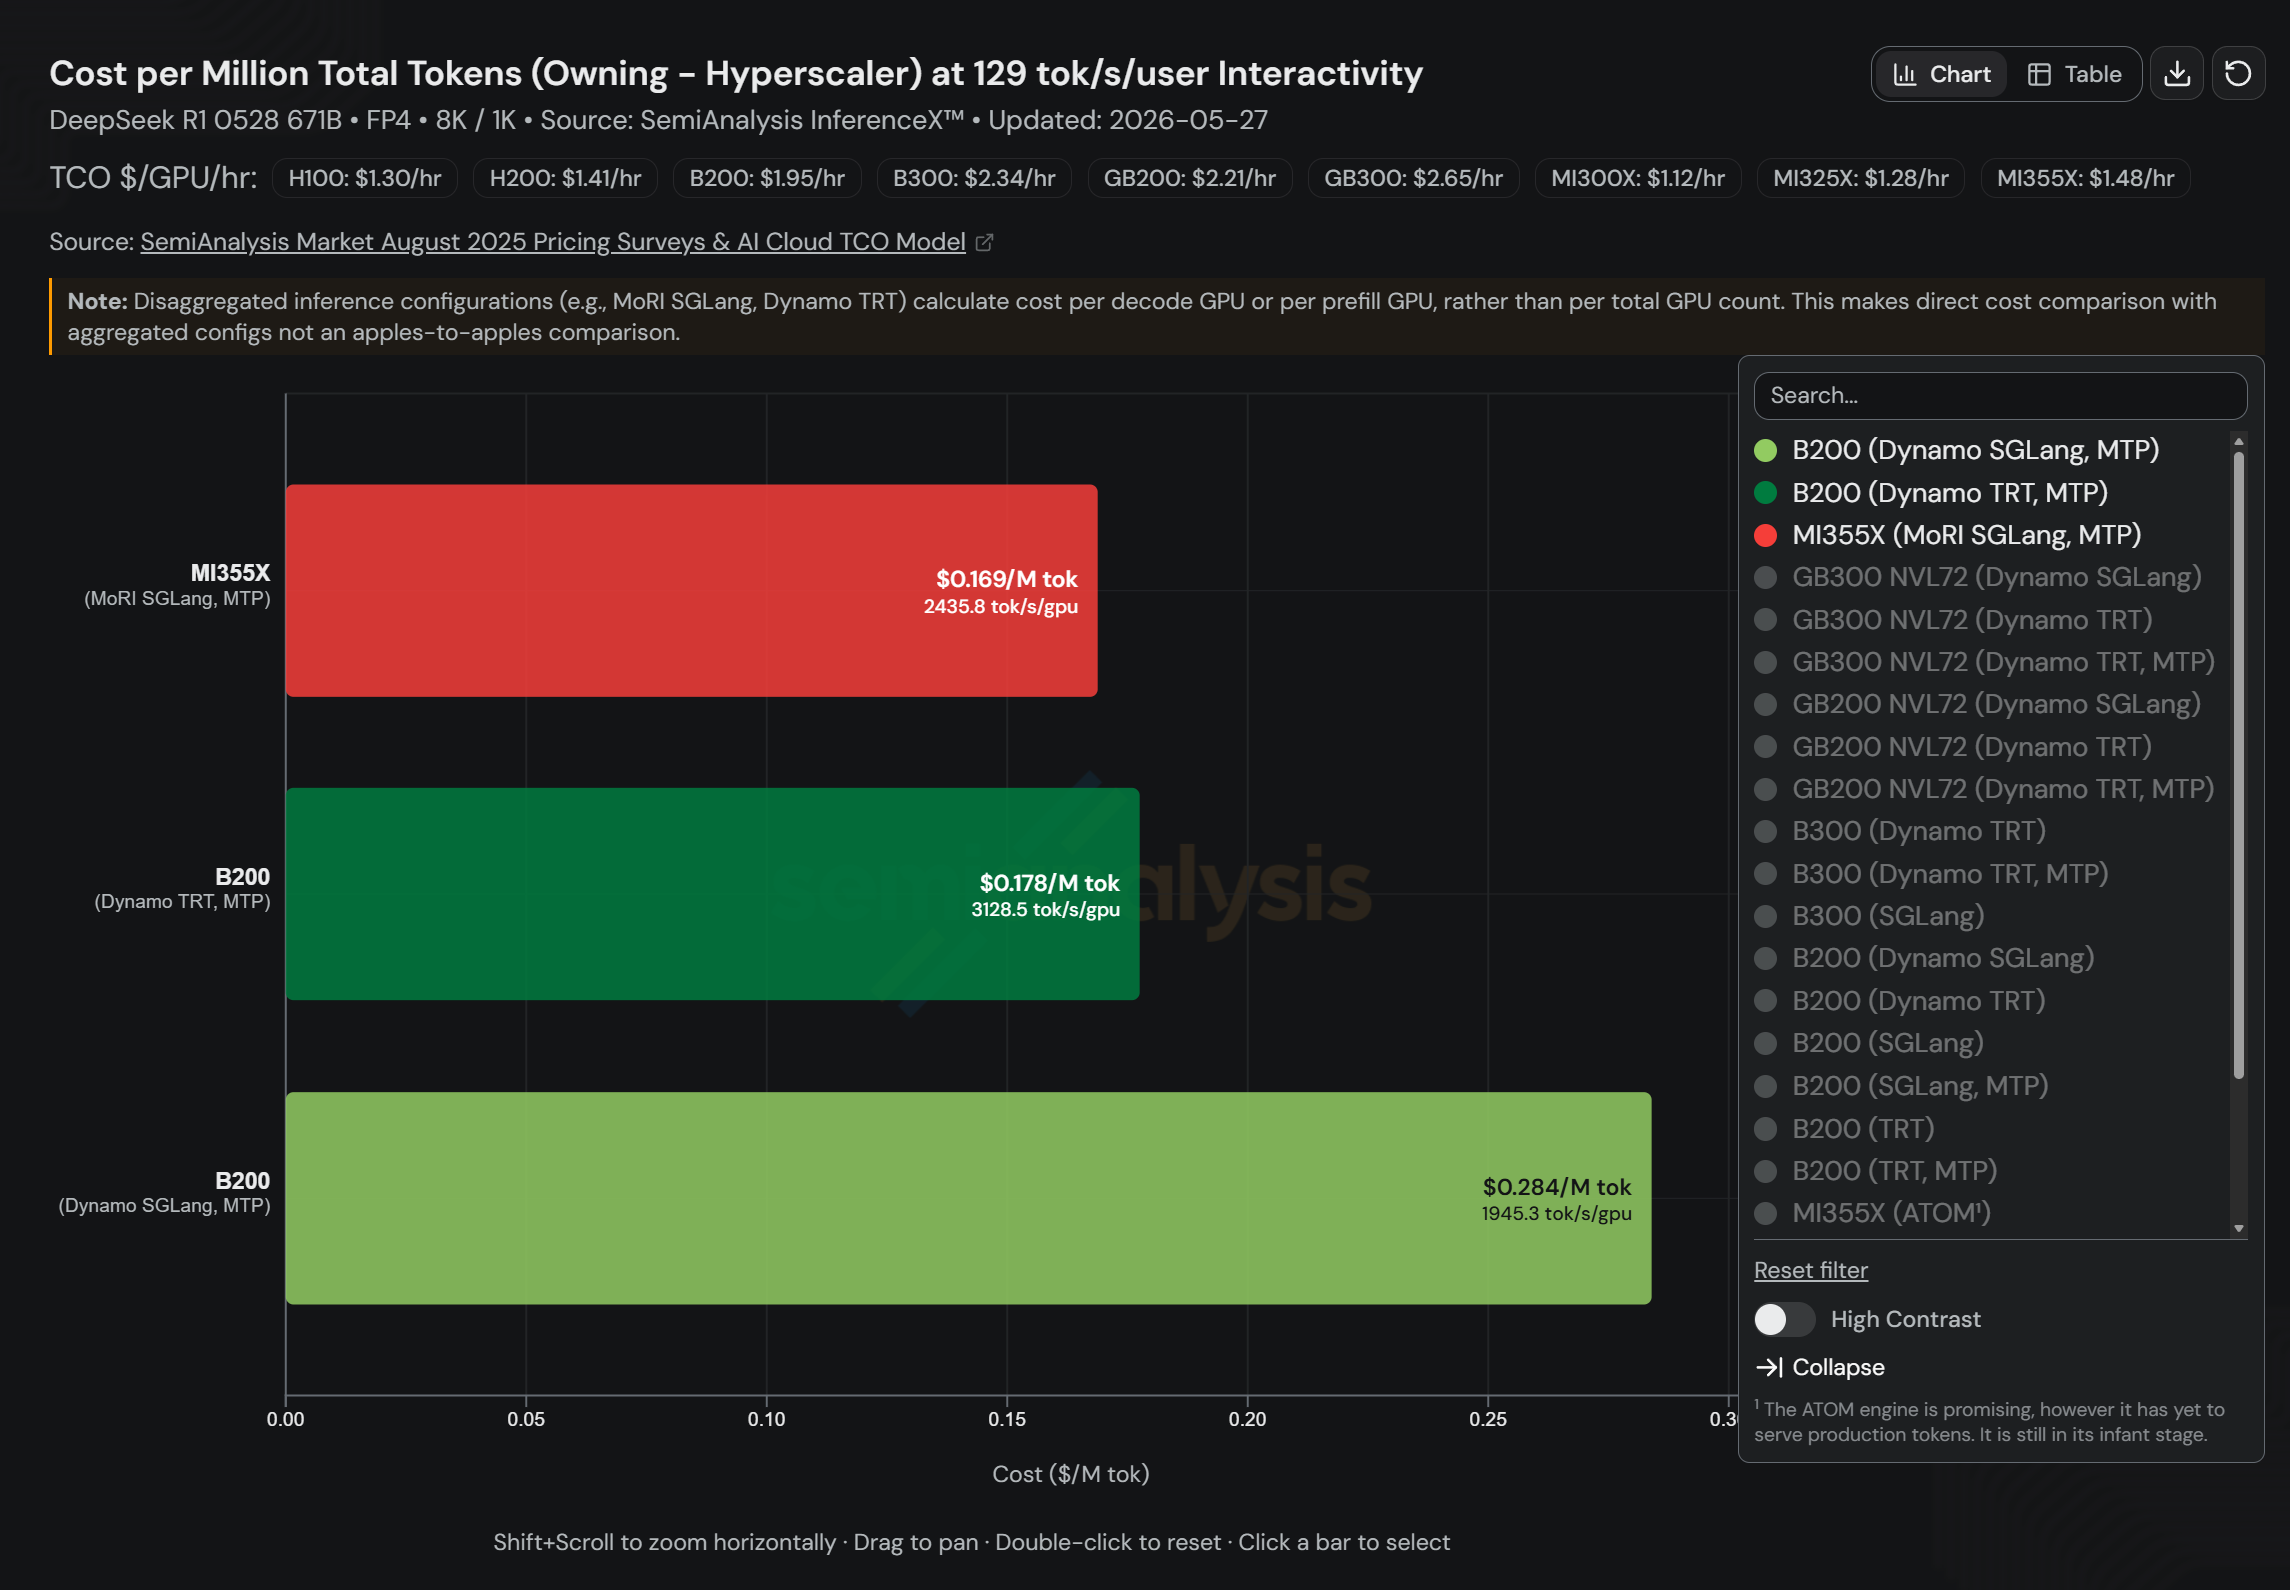
- Total Cost of Ownership Breakthrough: The synergy between the AMD Instinct™ MI355X accelerator and SGLang’s Mixture-of-Routing-Experts (MoRI) architecture delivers a paradigm shift in enterprise capital allocation for large language model (LLM) serving.
- Capital Efficiency at Scale: By optimizing distributed inference workflows, AMD systematically addresses the runaway infrastructure scalability costs that currently pressure corporate earnings and cloud capital expenditures.
- Market Disruption: This technical milestone challenges dominant valuation multiples in the high-end hardware sector, introducing genuine pricing competition and risk mitigation for enterprise buyers dependent on singular vendor ecosystems.
- Financial & Strategic Impact: Chief Technology Officers and Chief Financial Officers now have a viable, highly performant pathway to deploy multi-billion parameter models without compromising on latency or inflating operational expenditure (OpEx).
The economics of enterprise artificial intelligence are undergoing a brutal, unsparing recalculation. For the past thirty-six months, corporate boards have signed off on ballooning capital expenditure budgets under the implicit assumption that enterprise ROI requires a singular, heavily monopolized hardware ecosystem. That orthodoxy is now facing its most rigorous structural challenge to date. In a move that threatens to upend traditional valuation multiples across the semiconductor sector, Advanced Micro Devices (AMD) has unveiled a masterclass in systems-level engineering: the deployment of the AMD Instinct™ MI355X paired with SGLang utilizing the Mixture-of-Routing-Experts (MoRI) framework.
This is not merely an incremental bump in floating-point operations per second (FLOPS). It is a fundamental realignment of how distributed inference is architected, financed, and executed at enterprise scale. As cloud compute architecture strains under the immense pressure of token-generation demand, the industry’s most pressing mandate has shifted from raw compute velocity to ruthless, unyielding cost-per-token optimization. With the MI355X-MoRI stack, AMD has directly targeted the Achilles' heel of modern large language model deployment: inference cost.
The Structural Crisis of Enterprise Inference Economics
To understand the profound significance of the AMD Instinct™ MI355X deployment with SGLang and MoRI, one must examine the broader financial ledger of the generative AI boom. While initial market enthusiasm focused on training massive foundational models—where capital allocation was measured in billions of dollars—the long-term financial viability of corporate AI hinges entirely on inference. Every time a consumer queries a model or an enterprise workflow executes an automated reasoning chain, capital is expended.
Historically, distributed inference across massive clusters has suffered from severe bandwidth bottlenecks, suboptimal memory utilization, and crippling communication overhead between accelerators. Companies scaling their AI operations faced a punishing trade-off: either accept exorbitant cloud compute infrastructure bills that compress operating margins, or restrict model sizes to levels inadequate for complex, real-world enterprise applications. This dynamic created a severe market distortion, allowing incumbent hardware vendors to extract outsized margins while enterprise buyers absorbed unsustainable capital outlays.
Risk mitigation in tech procurement has traditionally meant vendor consolidation. However, the sheer financial toll of scaling LLM inference has turned this logic on its head. CIOs and procurement committees are actively seeking infrastructure alternatives that offer regulatory compliance, robust supply chain resilience, and, above all, predictable cost models. The entry of a high-performance alternative alters the entire negotiation matrix of the enterprise hardware market.
Engineering the Breakthrough: MI355X, SGLang, and MoRI
The technical architecture underlying this cost-competitive breakthrough represents a masterclass in co-design across silicon, systems software, and algorithmic orchestration. At the hardware tier, the AMD Instinct™ MI355X brings monumental high-bandwidth memory (HBM) capacity and memory bandwidth to the table, solving the primary bottleneck that starves GPUs during massive autoregressive token generation.
However, raw hardware horsepower is insufficient without sophisticated software orchestration. This is where SGLang—a high-performance serving framework designed for complex LLM workflows—enters the equation. SGLang optimizes execution through novel primitives such as RadixAttention, which radically reduces redundant computation by caching KV (Key-Value) caches across multiple generation requests. When combined with MoRI (Mixture-of-Routing-Experts), the system achieves unprecedented efficiency in distributed inference.
Decoding Mixture-of-Routing-Experts (MoRI)
MoRI fundamentally rethinks how tokens are routed across distributed nodes in a cluster running Mixture-of-Experts (MoE) architectures or large-scale distributed models. Traditional routing mechanisms often lead to severe load imbalance, leaving expensive accelerators sitting idle while others experience queuing delays. MoRI introduces intelligent, latency-aware routing paradigms that optimize network fabric utilization and memory traffic simultaneously.
- Dynamic Load Balancing: Dynamically redistributes expert computation across the MI355X fabric, eliminating the idle-wait states that traditionally plague distributed tensor-parallelism.
- Bandwidth Maximization: Leverages AMD's high-speed interconnects to minimize inter-GPU communication latency during expert weight sharing and token handoffs.
- Memory Footprint Optimization: Integrates seamlessly with SGLang's memory management to maximize concurrent request handling, drastically driving down the capital cost per active user session.
Verified Technical & Economic Impact Matrix
| Metric / Parameter | Legacy Infrastructure Standard | AMD MI355X + SGLang + MoRI Stack | Strategic Enterprise Benefit |
|---|---|---|---|
| Inference Cost-Per-Token | Baseline High (Proprietary Lock-in) | Significantly Compressed | Immediate OpEx reduction & margin expansion |
| Memory Bandwidth Utilization | Bounded by traditional KV-cache limits | Maximized via SGLang RadixAttention | Higher concurrency & lower time-to-first-token |
| Cluster Routing Efficiency | Static / Naive token distribution | Dynamic, Latency-Aware via MoRI | Eliminates GPU starvation & maximizes cluster ROI |
| Supply Chain Risk Mitigation | Single-vendor dependency | Multi-vendor open-standard ecosystem | Enhanced pricing power & procurement flexibility |
Industry & Market Implications: Who Wins, Who Loses
The commercial rollout of this architectural stack carries profound implications for global market liquidity, capital allocation, and competitive positioning across the technology sector. Wall Street analysts tracking enterprise technology spend are already revising their valuation models to account for the deflationary pressure AMD is exerting on inference hardware pricing.
The Winners: Enterprise buyers, hyperscale cloud providers seeking margin relief, and mid-tier cloud service providers stand to gain immensely. By validating a high-performance open ecosystem that rivals proprietary alternatives, AMD empowers non-megacap enterprises to deploy cutting-edge AI agents and autonomous reasoning systems without breaking their balance sheets. Furthermore, software developers and systems integrators specializing in SGLang and custom model serving will see an explosion in demand as corporations race to optimize their infrastructure.
The Pressured: Incumbent hardware monopolists accustomed to commanding exorbitant gross margins must now confront a market with a credible, high-performance alternative. The era of unquestioned pricing power is drawing to a close. As enterprise procurement departments leverage the MI355X-MoRI benchmarks in contract negotiations, hardware average selling prices (ASPs) across the high-end accelerator market will face downward normalization.
Frequently Asked Questions (People Also Ask)
Frequently Asked Questions
What is the primary advantage of combining the AMD Instinct™ MI355X with SGLang and MoRI?
The primary advantage is a dramatic reduction in the total cost of ownership (TCO) for distributed LLM inference. By optimizing memory utilization through SGLang and eliminating cluster routing bottlenecks via MoRI, enterprises can achieve high-throughput, low-latency generation at a fraction of the operational cost associated with legacy proprietary systems.
How does MoRI improve distributed inference compared to traditional routing methods?
Traditional routing often creates severe load imbalances across multi-node GPU clusters, leaving expensive hardware underutilized. MoRI (Mixture-of-Routing-Experts) introduces dynamic, latency-aware routing that intelligently manages token distribution and expert weight sharing, optimizing both network fabric and memory bandwidth simultaneously.
What financial impact does this architecture have on enterprise IT budgets?
This technical stack exerts direct deflationary pressure on inference costs, allowing Chief Financial Officers and CIOs to scale their AI deployments without incurring unsustainable cloud compute bills. It transforms AI from a high-burn exploratory cost center into a predictable, highly optimized operational expenditure.
Is the AMD MI355X ecosystem compatible with existing enterprise software stacks?
Yes. Through frameworks like SGLang and deep integration with open-source machine learning tooling, AMD has prioritized frictionless enterprise adoption, ensuring compatibility with major model architectures and mitigating vendor lock-in risks.
Future Outlook and Strategic Milestones to Watch
As corporate IT spending pivots definitively from training to inference, the battleground for enterprise AI dominance will be fought in the trenches of cost efficiency, software maturity, and supply chain reliability. The deployment of the AMD Instinct™ MI355X through SGLang with MoRI marks a watershed moment in this evolution.
Over the next twelve to eighteen months, market watchers should monitor several critical milestones:
- Enterprise Adoption Velocity: Track the rate at which Fortune 500 financial institutions, healthcare giants, and telecommunications leaders migrate production-grade multi-billion parameter models to the AMD-SGLang-MoRI stack.
- Ecosystem Expansion: Observe further optimizations in open-source serving frameworks as developer communities build upon MoRI’s routing primitives to support even larger, more complex Mixture-of-Experts architectures.
- Competitive Pricing Dynamics: Monitor gross margin reports from major hardware vendors to gauge the extent to which AMD’s cost-competitive push is forcing industry-wide price adjustments.
Ultimately, the convergence of advanced silicon like the MI355X and intelligent algorithmic orchestration like MoRI signals the maturation of the enterprise AI market. Monopolies are being challenged, capital allocation is becoming disciplined, and the promise of accessible, cost-effective artificial intelligence is finally translating from boardroom aspiration into hard, verified financial reality.