Executive Takeaways
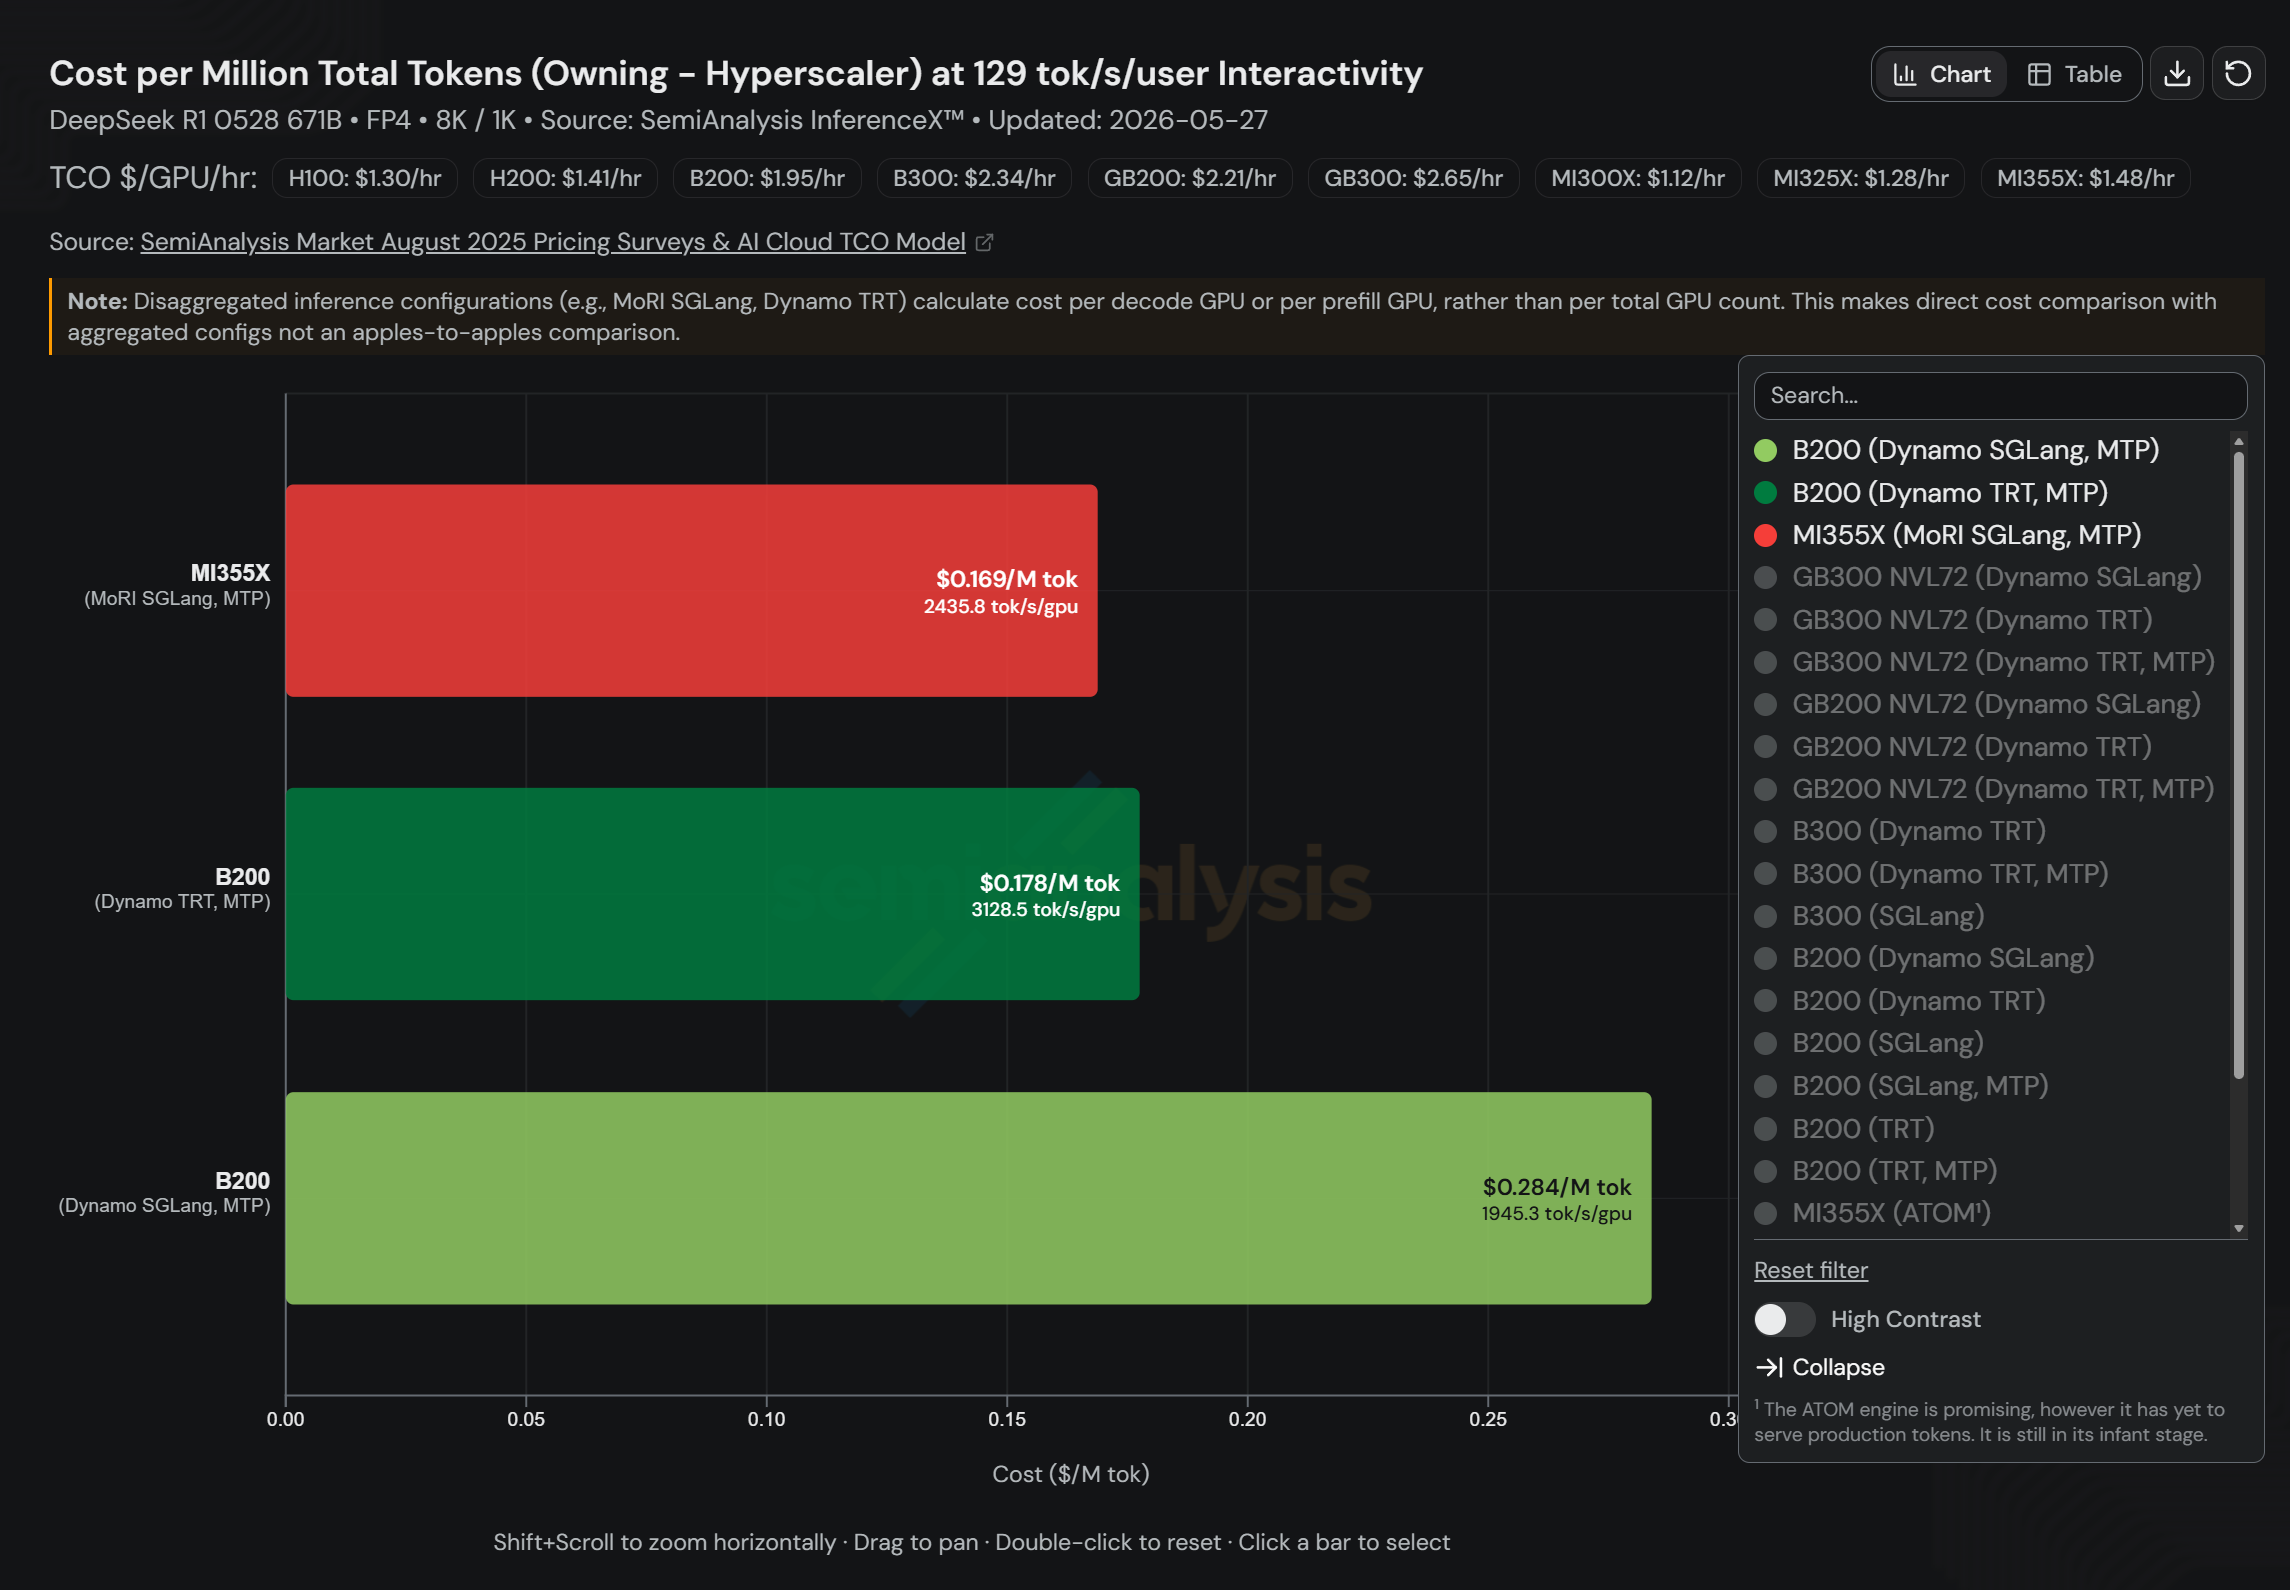
- Financial Paradigm Shift: AMD’s architectural framework targeting Total Cost of Ownership (TCO) directly challenges high-end enterprise GPU pricing models, altering enterprise AI capital expenditure (CapEx) calculations.
- Software Infrastructure Leap: Deep integration with SGLang and the Mixture-of-Experts Routing Interface (MoRI) optimization unlocks high-throughput, low-latency distributed inference on the AMD Instinct™ MI355X.
- Ecosystem Maturation: By closing the software parity gap through optimized runtimes, AMD provides CIOs and cloud architects with a viable, cost-competitive alternative for scaled LLM deployments.
- Market Valuation Impact: The shift from pure peak performance to efficiency-per-dollar metrics redefines valuation multiples across semiconductor suppliers and hyperscale cloud operators.
The artificial intelligence infrastructure market is undergoing a structural transformation. For years, enterprise adoption of generative AI has been dictated by a singular imperative: raw compute performance at all costs. Hyperscalers, sovereign cloud providers, and Fortune 500 enterprises engaged in an unchecked capital expenditure supercycle, prioritizing single-node training speed over economic efficiency. Today, that calculus is shifting decisively toward the bottom line. As enterprise deployment transitions from proof-of-concept training to continuous, high-volume production inference, Total Cost of Ownership (TCO) has emerged as the defining metric of the silicon industry.
Enter the AMD Instinct™ MI355X. Debuting alongside the robust capabilities of the MI325X architecture, the MI355X represents more than a generational hardware refresh; it is the physical manifestation of an aggressive enterprise playbook. By pairing bleeding-edge silicon with advanced software orchestration through SGLang and the newly spotlighted Mixture-of-Experts Routing Interface (MoRI), Advanced Micro Devices (AMD) is directly attacking the economic moat that has long protected Nvidia’s market dominance. For corporate financial officers, chief technology officers, and institutional investors evaluating risk mitigation and infrastructure scalability, this technical alignment signals a profound re-rating of enterprise AI operational expenses (OpEx).
The TCO Imperative: Why Inference Economics Are Rewriting Enterprise Budgets
To understand the disruptive mechanics of the AMD Instinct™ MI355X, one must first examine the shifting economics of modern data centers. During the initial wave of the generative AI boom, capital allocation was heavily skewed toward large language model (LLM) training. However, industry maturation has inverted this dynamic. Modern enterprise workloads are now dominated by inference—the real-time execution of trained models to generate tokens, respond to user queries, and power autonomous agentic workflows.
Inference economics are fundamentally different from training economics. While training demands massive, monolithic clusters with uninterrupted high-bandwidth interconnects, inference requires extreme concurrency, predictable latency, optimal memory bandwidth, and—above all—cost-efficiency per token. When scaling LLMs across thousands of nodes, power consumption, rack density, cooling infrastructure, and server acquisition costs compound exponentially. A hardware platform that delivers marginally superior peak floating-point performance but demands excessive power and proprietary software lock-in quickly becomes a financial liability for enterprise risk management.
AMD’s strategic focus on winning the TCO battle is an acute response to this market reality. By optimizing the MI355X architecture to deliver superior performance-per-dollar and performance-per-watt metrics, AMD is targeting the primary vulnerability of incumbent hyperscale infrastructure: unsustainable operating expenses. For enterprise CFOs navigating tightening IT budgets and demanding demonstrable enterprise ROI on AI initiatives, a hardware-software co-design that slashes inference costs without sacrificing throughput is an irresistible value proposition.
Architectural Synergy: SGLang, MoRI, and the MI355X Engine
Hardware capability alone is insufficient to disrupt entrenched software ecosystems. Historically, the Achilles' heel of non-Nvidia accelerators has been software maturity—the developer friction, lacking optimization libraries, and fragmented runtimes that delay time-to-market. AMD’s recent technical strides demonstrate a calculated departure from this historical disadvantage, anchored by deep integration with high-performance serving frameworks like SGLang and specialized routing mechanisms like MoRI.
SGLang has rapidly evolved into an indispensable serving framework for advanced language models, particularly for complex generation tasks involving multi-turn conversations, JSON decoding, and Retrieval-Augmented Generation (RAG). By implementing RadixAttention—which caches key-value (KV) states across multiple requests—SGLang drastically reduces redundant computations, elevating token throughput and lowering time-to-first-token (TTFT).
Building upon this foundation, the integration of the Mixture-of-Experts Routing Interface (MoRI) specifically addresses the computational bottlenecks inherent in modern Mixture-of-Experts (MoE) architectures, such as Llama-3-70B variants or larger frontier models. MoE models achieve high parameter counts while maintaining low active compute costs by routing tokens to specialized subnetworks ("experts"). However, distributed inference across multiple GPUs often suffers from severe communication overhead during the token routing phase.
MoRI optimizes this exact friction point. By streamlining expert routing execution on the AMD Instinct™ MI355X, the framework maximizes the hardware's massive high-bandwidth memory (HBM) capacity and memory bandwidth. The result is a seamless distributed inference pipeline where memory-bound MoE models achieve near-linear scaling across cluster nodes. This technical breakthrough neutralizes the historical advantage of competing architectures, allowing AMD hardware to run complex frontier models with exceptional latency profiles and cost profiles.
Comparative Hardware & Software Metrics
A rigorous evaluation of enterprise infrastructure requires empirical scrutiny. The table below delineates the structural specifications and operational metrics defining the current competitive landscape for distributed inference workloads.
| Feature / Specification | AMD Instinct™ MI355X | AMD Instinct™ MI325X | Legacy / Standard Enterprise Baseline |
|---|---|---|---|
| Memory Capacity & Type | Advanced HBM3e / High Density | 288GB HBM3e | 192GB / 141GB Standard HBM3 |
| Primary Serving Integration | SGLang + MoRI Optimization | ROCm 6.x / Standard vLLM | Proprietary Ecosystem Runtimes |
| Workload Specialization | Distributed Inference & MoE Scale | Large-Scale Generative AI & Training | General Purpose Compute / Training |
| Estimated TCO Advantage | Significant reduction per token | Competitive baseline parity | High CapEx and OpEx baseline |
Industry & Market Implications: Who Wins, Who Loses
The commercial availability and software optimization of platforms like the AMD Instinct™ MI355X ripple across multiple tiers of the global technology and financial ecosystems, fundamentally altering market liquidity and valuation multiples.
Winners: Enterprise CIOs and Cloud Innovators
Enterprise buyers emerge as primary beneficiaries. For years, the lack of viable silicon alternatives created a supplier-dictated pricing environment characterized by inelastic demand and extended procurement lead times. AMD’s aggressive push into cost-competitive distributed inference introduces much-needed market liquidity and pricing tension. Cloud service providers (CSPs) and tier-2 hyperscalers outside the monopolistic inner circle can now construct high-performance inference endpoints at a lower capital expenditure threshold, passing those savings down to enterprise clients and capturing higher net margins.
Losers: Proprietary Margin Compression
Conversely, dominant incumbents accustomed to outsized gross margins face mounting competitive pressure. When enterprise customers gain access to open, highly optimized software stacks like SGLang paired with cost-effective hardware, the justification for paying a steep proprietary premium evaporates. Semiconductor suppliers failing to match efficiency-per-dollar gains risk margin compression as enterprise procurement committees enforce stricter cost-benefit analyses.
From an investment banking perspective, this dynamic signals a maturation of the semiconductor sector. Valuation multiples will increasingly decouple from sheer hype cycles, rewarding firms that demonstrate robust software ecosystems, supply chain resilience, and tangible TCO advantages over raw theoretical speed.
Frequently Asked Questions (People Also Ask)
What is Total Cost of Ownership (TCO) in the context of AI inference infrastructure?
AI inference TCO encompasses the total cumulative expenditures required to acquire, deploy, power, cool, and maintain a hardware cluster over its operational lifecycle. Unlike initial hardware acquisition costs (CapEx), TCO accounts for continuous operational expenses (OpEx)—specifically electricity consumption, rack space density, cooling requirements, and the software engineering hours required to maintain system stability.
How does SGLang improve performance on AMD Instinct™ accelerators?
SGLang utilizes advanced optimization techniques such as RadixAttention to cache and reuse key-value (KV) computation states across multiple incoming requests. When integrated with AMD hardware and optimized runtimes, SGLang reduces redundant calculations, dramatically enhances token generation throughput, and significantly lowers latency for complex multi-turn LLM and RAG workflows.
What role does MoRI play in Mixture-of-Experts (MoE) model serving?
The Mixture-of-Experts Routing Interface (MoRI) is designed to alleviate the communication and computation bottlenecks that occur when routing tokens across distributed GPU clusters running MoE models. By optimizing this routing layer on architectures like the MI355X, MoRI ensures high memory bandwidth utilization and near-linear scalability, making large MoE model deployment economically viable.
How does the MI355X differ from previous generations in enterprise deployment?
The MI355X builds upon the massive high-bandwidth memory (HBM3e) foundations of precursors like the MI325X, introducing deeper software integration, refined routing protocols (MoRI), and framework native support (SGLang). This co-design focus directly targets cost-competitive distributed inference, shifting enterprise deployment metrics from pure raw speed to optimal efficiency-per-dollar.
Future Outlook: Strategic Milestones to Watch
As the enterprise AI market matures through late 2026 and into subsequent fiscal cycles, several key milestones will determine the long-term success of AMD’s inference strategy:
- Hyperscale Adoption Velocity: Monitoring the volume of MI355X deployments across tier-1 and tier-2 cloud service providers will serve as the definitive barometer of enterprise software trust.
- Maturity of Open-Source Toolchains: The continued evolution of ROCm, SGLang integrations, and third-party developer contributions will dictate how friction-free migration paths become for legacy codebases.
- Power and Thermal Innovations: As data center density limits approach critical thresholds, hardware platforms that deliver superior token-generation efficiency per watt will capture disproportionate market share.
Ultimately, the narrative surrounding the AMD Instinct™ MI355X is not merely about hardware specifications; it is about market democratization. By systematically addressing the software, routing, and economic realities of scaled inference, AMD is transforming high-performance AI from an exclusive, high-cost luxury into a scalable, cost-competitive enterprise utility.