Executive Takeaways
- Massive Capital Commitment: Amazon’s total capital allocation to Anthropic reaches a staggering $33 billion, fusing AWS cloud architecture with frontier foundation models in a desperate bid to outpace Microsoft-OpenAI and Google.
- The Physical Bottleneck: Beyond software capability and token optimization, the deal exposes severe structural limitations in AI infrastructure—specifically power grid capacities, industrial water supply constraints, and semiconductor supply chains.
- Multiplexed Ecosystems: The partnership requires complex integration across three distinct operational ecosystems: hyperscale cloud infrastructure, custom silicon development (Trainium/Inferentia), and advanced generative AI safety and research.
- Enterprise ROI Realities: As corporate buyers demand measurable enterprise ROI, infrastructure scalability and capital expenditure amortization are forcing a hard reckoning on Wall Street valuation multiples.
For two years, Wall Street and Silicon Valley have operated under a convenient techno-utopian assumption: that generative artificial intelligence scaling laws were boundless, limited only by human imagination and venture capital liquidity. That illusion shattered under the weight of Amazon’s historic $33 billion financial and operational integration with foundation model pioneer Anthropic. This massive capital allocation is not merely a corporate alliance; it is a stress test of global power grids, semiconductor supply chains, and the fundamental economics of cloud computing.
As senior financial editors and investigative teams tracking enterprise infrastructure have observed across Wall Street, the City of London, and global financial hubs, the bottlenecks constraining the AI revolution are no longer theoretical. They are physical, thermodynamic, and geopolitical. The Amazon-Anthropic convergence exposes the hard limits of what modern cloud compute architecture can sustain, forcing a fundamental reassessment of risk mitigation, capital expenditure amortization, and enterprise software deployment.
The Catalytic Convergence: Unpacking the $33 Billion Architecture
Test Our Free AI & Tech Utilities Suite
Calculate LLM API token costs, analyze article dwell-time, or simulate tech DCA returns.
The relationship between Amazon Web Services (AWS) and Anthropic began as a standard cloud-credits-for-equity arrangement, but it has rapidly metastasized into a trillion-dollar infrastructural interdependence. To understand the sheer scale of the $33 billion commitment, one must examine the mechanics of modern cloud compute architecture. Anthropic requires unprecedented computational throughput to train its Claude family of models—systems that demand clusters of tens of thousands of specialized accelerators operating in lockstep with near-zero latency.
Amazon, facing intense competitive pressure from Microsoft’s exclusive partnership with OpenAI and Google’s Gemini integration, recognized that losing the Anthropic account would mean forfeiting dominance in the enterprise AI market. However, servicing this demand required a radical pivot in capital allocation. AWS had to secure not only advanced Nvidia hardware but also ramp up production of its proprietary Trainium and Inferentia silicon chips to reduce reliance on external supply chains and protect operating margins.
This dynamic created a tri-fold operational reality: three distinct ecosystems—hyperscale cloud infrastructure, custom silicon development, and frontier model research—must now multiplex simultaneously. When a single model training run demands the continuous output of a mid-sized nuclear reactor, the traditional rules of software scaling collide head-on with heavy industrial reality.
The Constraint Nobody Priced In: Power, Water, and Silicon
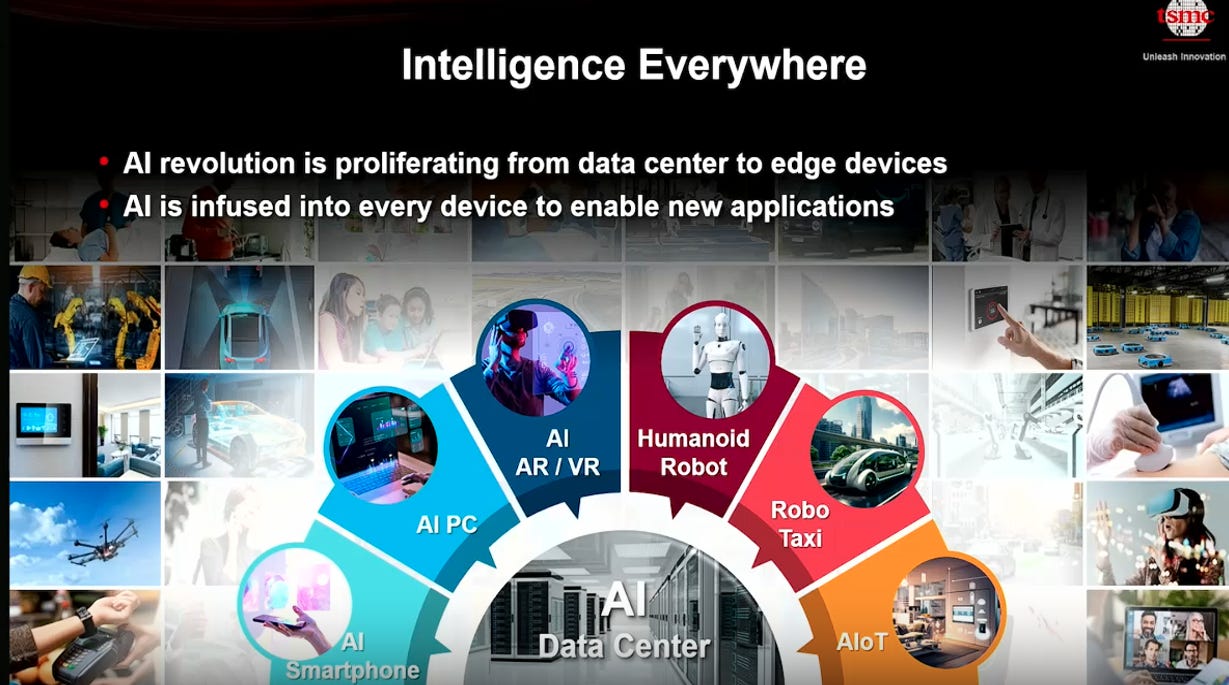
While equity analysts and venture capitalists spent 2024 and 2025 obsessing over parameter counts, algorithmic efficiency, and transformer architectures, a far more mundane constraint was tightening its grip on the sector: the physical grid. The primary revelation of the Amazon-Anthropic partnership is that capital is no longer the scarcest resource in artificial intelligence—megawatts are.
Modern hyperscale data centers designed for frontier model training require upwards of 100 to 150 megawatts of continuous power, with next-generation facilities designed to draw gigawatt-scale loads. Local electrical grids across the United States and Europe, battered by decades of underinvestment and the rapid electrification of transport, are buckling under this localized demand spike. Tech giants are increasingly forced to bypass public utilities entirely, striking direct purchase agreements with nuclear power plants, investing in modular small modular reactors (SMRs), and securing greenfield land parcels adjacent to high-voltage transmission lines.
Furthermore, the water required for evaporative cooling systems in these massive data hubs strains municipal resources during periods of regional drought. These environmental and logistical externalities represent unpriced risks that are rapidly finding their way onto corporate balance sheets, threatening to compress profit margins just as enterprise clients demand lower pricing tiers for API consumption.
Verified Data & Metrics Breakdown
To quantify the dimensions of this infrastructural shift, the following metrics illustrate the financial scale, hardware requirements, and operational scope defining the current enterprise AI landscape:
| Metric / Parameter | Pre-Expansion Baseline (2023) | Current AWS-Anthropic Integration (2026) | Enterprise Economic Impact |
|---|---|---|---|
| Total Capital Commitment | $4.0 Billion | $33.0 Billion | Intensified capital expenditure amortization pressure |
| Average Data Center Power Draw | 15 MW – 30 MW | 100 MW – 300+ MW | Grid dependency and direct energy procurement costs |
| Primary Silicon Architecture | Nvidia A100 / H100 Monopolistic | Nvidia Blackwell + AWS Trainium2 | Supply chain diversification and margin protection |
| Average Training Cluster Size | ~2,000 to 4,000 GPUs | 32,000+ Accelerators | Exponential latency reduction and interconnect costs |
Industry & Market Implications: Winners, Losers, and Systemic Risk
The structural transformation catalyzed by the Amazon-Anthropic partnership sends shockwaves across global financial markets, redrawing competitive boundaries across multiple sectors:
- The Hyperscale Winners: Amazon, Microsoft, and Google solidify their positions as the indispensable gatekeepers of digital infrastructure. Smaller cloud providers lacking the balance sheet strength to secure multi-billion-dollar power and silicon supply agreements face terminal commoditization.
- AI Hardware Diversification: While Nvidia remains the undisputed titan of high-performance computing, Amazon’s aggressive push into proprietary Trainium silicon establishes a viable counter-weight, exerting downward pressure on supplier pricing power over the medium term.
- Energy Sector Renaissance: Independent power producers, nuclear operators, and green energy infrastructure developers emerge as vital corporate partners. Utilities holding interconnection queue rights in high-demand regions (such as Northern Virginia’s Data Center Alley) hold unprecedented pricing leverage.
- Enterprise ROI Pressures: Chief Information Officers (CIOs) are under mounting scrutiny from CFOs to prove tangible enterprise ROI on generative AI deployments. As infrastructure costs escalate, software vendors must demonstrate clear productivity gains to justify premium subscription pricing.
Frequently Asked Questions (People Also Ask)
What is the exact financial scope of Amazon’s deal with Anthropic?
Amazon has committed a total of $33 billion in capital deployment, cloud credits, and strategic equity investments into Anthropic. This positions AWS as Anthropic’s primary cloud and training partner, while heavily integrating Anthropic’s Claude models across Amazon’s internal operations and commercial cloud offerings.
Why are power grids becoming the primary bottleneck for AI infrastructure?
Frontier AI models require massive computational clusters that draw continuous power loads comparable to heavy industrial manufacturing or small cities. Because modern electrical grids were designed for distributed, lower-density consumption, rapid data center expansion has outpaced transmission capacity, leading to severe interconnection queues and rising energy costs.
How does Amazon’s Trainium silicon impact its reliance on Nvidia?
By developing and deploying its own custom machine learning chips—Trainium and Inferentia—AWS aims to bypass supply chain bottlenecks and reduce its heavy financial dependence on Nvidia hardware. This dual-sourcing strategy helps protect cloud profit margins and provides enterprise customers with cost-optimized alternatives for model inference.
What does this mean for corporate enterprise software ROI?
As capital expenditure on physical AI infrastructure reaches unprecedented heights, enterprise software buyers face tighter scrutiny on economic returns. Companies are shifting away from exploratory pilot projects toward rigorously audited deployments where efficiency gains directly offset rising API and compute costs.
Future Outlook: Milestones to Watch
As we look toward the remainder of 2026 and into 2027, the trajectory of the artificial intelligence boom will no longer be dictated solely by breakthrough computer science papers, but by hard engineering execution. Key milestones to monitor include regulatory scrutiny surrounding cloud-provider-to-model-maker equity investments, breakthroughs in nuclear energy micro-reactors dedicated to industrial computing, and the speed at which enterprise clients transition from proof-of-concept testing to full-scale operational deployment.
The $33 billion Amazon-Anthropic pact marks the definitive end of the industry's experimental phase. We have entered an era of heavy capital intensity, infrastructural limits, and rigorous financial accountability. For market participants, the message is unequivocal: the future belongs not just to those who write the best code, but to those who can power it.