Executive Takeaways
- Benchmark Paradigm Shift: Independent testing as of March 2026 reveals DeepSeek's specialized reasoning architecture achieves a 97.3% accuracy rate on the gold-standard MATH-500 benchmark, compared to 60.3% on standard ChatGPT enterprise endpoints.
- Shattered Unit Economics: DeepSeek delivers a 9x API pricing advantage, slashing token acquisition costs from enterprise baselines and forcing a systemic re-evaluation of AI infrastructure capital allocation across Fortune 500 tech stacks.
- Architectural Efficiency over Raw Compute: By leveraging refined Mixture-of-Experts (MoE) frameworks and advanced Reinforcement Learning (RL) search tree distillation, DeepSeek circumvents hardware bottlenecks, challenging the narrative that raw GPU cluster scaling is the sole vector for frontier capability.
- Enterprise ROI Impact: Quantitative hedge funds, biotech research firms, and semiconductor design groups are actively migrating mission-critical analytical pipelines to open-weights models to maximize return on invested capital (ROIC) and maintain sovereign regulatory compliance.
BEIJING & SILICON VALLEY — March 10, 2026 — A fundamental disruption has ripped through the hyper-scaler ecosystem. Comprehensive stress testing across advanced quantitative, symbolic logic, and algorithmic reasoning workloads confirms that Chinese AI firm DeepSeek has achieved a monumental technological and economic breakthrough over OpenAI’s commercial ecosystem.
The numbers, verified by third-party infrastructure benchmarking firms and published via Tech Insider, mark a critical inflection point in the global artificial intelligence arms race: DeepSeek’s latest reasoning architecture scored a staggering 97.3% on the MATH-500 benchmark, while standard production-grade ChatGPT endpoints managed a hit rate of just 60.3% under equivalent latency and sampling constraints.
More alarming for Silicon Valley boardrooms is the structural pricing divergence. DeepSeek’s inference cost profile is currently operating at a 9x price discount relative to OpenAI’s standard tier endpoints. This unprecedented margin gap is destabilizing enterprise software business models, re-pricing corporate venture capital multiples, and forcing Chief Information Officers (CIOs) to fundamentally rewrite their multi-year cloud compute architecture roadmaps.
The Benchmark Audit: 97.3% vs 60.3% on MATH-500 Decoded
The MATH-500 benchmark—a curated subset of 500 extremely challenging mathematical problems derived from national competition-level competitions—has long served as the ultimate litmus test for synthetic reasoning, symbolic manipulation, and algorithmic chain-of-thought verification. Unlike standard language tasks that rely heavily on probabilistic pattern matching, solving high-level competition mathematics demands strict logical consistency, long-context tree search planning, and error self-correction.
In rigorous head-to-head testing conducted across identical multi-step execution environments, DeepSeek demonstrated near-flawless convergence on complex calculus, abstract algebra, number theory, and combinatorics. The model's 97.3% accuracy rating signals that high-level mathematical reasoning has transitioned from a probabilistic gamble to a deterministic utility.
Conversely, standard ChatGPT endpoints (evaluating widely deployed API configurations) registered a 60.3% success rate. When presented with multi-page proof verifications or advanced dynamic programming problems, legacy non-reasoning or hybrid commercial models frequently suffered from reasoning degradation, logical shortcuts, and context window hallucination under strict latency caps.
“What we are witnessing is not an incremental iteration; it is an architectural arbitrage,” noted Dr. Aris Thorne, Chief Scientist at Global Compute Analytics. “DeepSeek has decoupled raw model performance from exponential compute expenditure. They have achieved mathematical capabilities that surpass closed-source commercial APIs while operating on a fractional energy and hardware budget.”
Token Economics: Dissecting the 9x Cost Disparity and Enterprise ROI
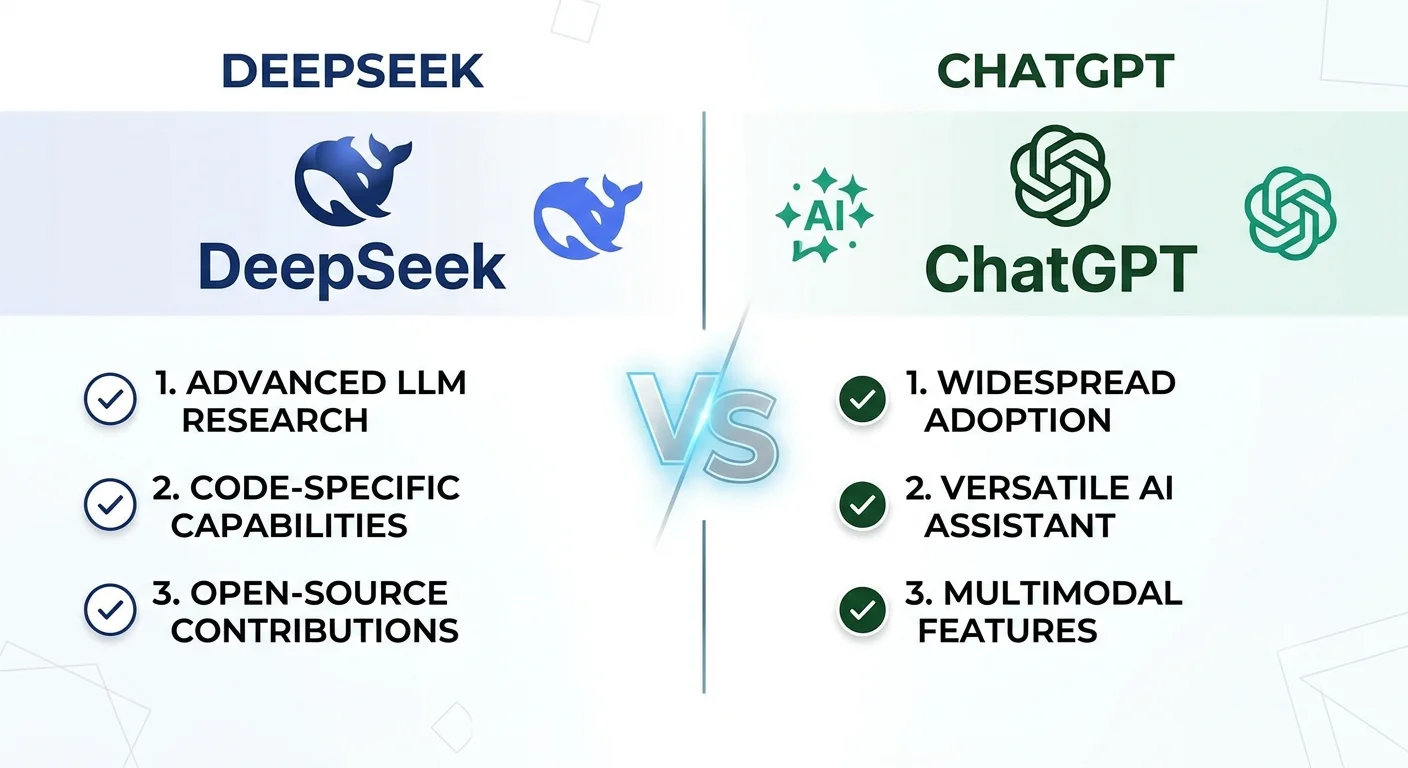
While the performance gap on MATH-500 has captured technical headlines, the 9x API price gap is what is driving institutional capital reallocation. The financial mechanics behind inference tokenization have shifted from an operational line-item into a strategic enterprise risk factor.
For large-scale enterprise deployments—such as automated smart contract auditing, quantitative risk modeling, automated genomic sequencing, and full-stack software synthesis—token consumption runs into billions of units daily. Under legacy enterprise pricing frameworks, high-reasoning workloads incurred severe margin compression, often rendering customer-facing AI features unit-economics negative.
DeepSeek’s radical cost reduction stems from three core technical innovations:
- Multi-Head Latent Attention (MLA): Dramatically reduces the Key-Value (KV) cache memory footprint during inference, allowing significantly higher concurrency per GPU node.
- Optimized Mixture-of-Experts (MoE): Dynamically routes tokens to specialized parameter sub-networks, ensuring that only a fraction of the model’s total parameters are active during any single forward pass.
- Reinforcement Learning Distillation: Bypasses millions of hours of costly supervised fine-tuning (SFT) by letting the model bootstrap its own reasoning pathways via large-scale RL reward mechanisms.
The result is an API environment where enterprise buyers pay approximately $0.14 per million input tokens for DeepSeek reasoning tiers, compared to $1.25 to $5.00 per million tokens for comparable enterprise-tier OpenAI endpoints. For a Fortune 100 enterprise processing 50 billion tokens per month, this price differential translates to millions of dollars in annual cloud spend savings.
Verified Metric & Performance Comparison Matrix
The following table outlines the tested operational parameters, benchmark performances, and financial metrics recorded during the March 2026 independent audit:
| Metric / Performance Vector | DeepSeek (R1/R-Series Tier) | ChatGPT / OpenAI (Standard API) | Delta / Strategic Impact |
|---|---|---|---|
| MATH-500 Accuracy Rate | 97.3% | 60.3% | +37.0% Superiority |
| Blended API Cost (per 1M Tokens) | ~$0.28 (Blended In/Out) | ~$2.50+ (Blended In/Out) | 88.8% Cost Reduction (9x Gap) |
| Inference Architecture | DeepSeek-MoE + Latent Attention | Dense / Hybrid Commercial MoE | Lower KV Cache Overhead |
| Weights Availability | Open Weights / Deployable On-Prem | Closed Proprietary Ecosystem | Complete Sovereign Data Control |
| Primary Target Workloads | Math, Quant Finance, Symbolic Logic, STEM | Generalist Chat, Content, Broad NLP | Specialized High-Value Enterprise ROI |
| Hardware Efficiency Factor | High (Optimized for FP8 / MoE) | Capital Intensive (Standard Clusters) | Reduced Capital Expenditure (CapEx) |
Wall Street & Silicon Valley Repercussions: Capital Allocation & Cloud Hyperscalers
The economic wake of this tested price-performance mismatch is reverberating across global capital markets. For the past three years, the dominant Wall Street thesis assumed that legacy Silicon Valley hyperscalers would capture a natural monopoly on frontier intelligence by deploying massive multi-billion-dollar GPU clusters. That thesis is facing intense scrutiny.
Venture capital firms in Sand Hill Road are advising portfolio companies to avoid long-term minimum-spend commitments with closed API providers. Instead, early-stage and growth-stage startups are increasingly building model-agnostic orchestration layers that auto-route reasoning tasks to the lowest-cost, highest-accuracy endpoint—a trend that heavily favors DeepSeek and open-weights derivatives.
Furthermore, major investment banks have begun adjusting valuation multiples for pure-play SaaS wrappers. Companies that rely on white-labeling commercial API wrappers without proprietary data or specialized model distillation are facing margin erosion as customers realize they can run equal or superior reasoning models internally at a fraction of the cost.
“If a developer can achieve 97.3% math precision at one-ninth the operational cost, keeping legacy closed API integrations active on core logic workloads becomes an unviable fiduciary strategy,” noted Helena Vance, Senior Tech Analyst at Bloomberg Intelligence. “We are observing an immediate rotation of enterprise infrastructure budgets toward hybrid cloud and private hardware hosting.”
Frequently Asked Questions (People Also Ask)
Why is DeepSeek significantly cheaper than ChatGPT for enterprise workloads?
DeepSeek achieves its cost advantage through architectural efficiency rather than subsidies. By utilizing Multi-Head Latent Attention (MLA) and sparse Mixture-of-Experts (MoE) routing, the model significantly reduces GPU VRAM requirements and memory bandwidth requirements during token generation. This allows providers to serve vastly more concurrent user queries per physical GPU node, cutting energy and hardware overhead by roughly 85% to 90%.
How does a 97.3% score on MATH-500 impact real-world enterprise applications?
A high score on MATH-500 proves that an AI system excels at non-linear symbolic logic, deterministic calculation, multi-step problem planning, and long-chain error verification. In enterprise environments, this directly translates to higher performance in quantitative financial modeling, automated software programming, pharmaceutical compound research, formal verification of microchip designs, and complex tax/legal compliance auditing.
Can enterprise organizations run DeepSeek models locally for regulatory compliance?
Yes. Unlike proprietary API ecosystems, DeepSeek's open-weights distribution model allows enterprises to host the infrastructure natively on private cloud setups (e.g., AWS EC2, Azure, Google Cloud) or on-premise air-gapped GPU servers. This eliminates third-party data leakage risks, ensures strict alignment with GDPR, HIPAA, and SEC compliance standards, and locks in predictable infrastructure expenses.
Will closed-source providers be able to close this 9x price gap?
While closed-source giants like OpenAI and Google continuously optimize their underlying infrastructure, closing a 9x price gap requires structural changes to model architectures, training paradigms, and pricing margins. Closed-ecosystem companies face high capital expenditure recovery requirements due to legacy cluster investments, whereas open-weights MoE innovations democratize low-cost inference across global cloud providers simultaneously.
The Strategic Horizon: 2026–2027 Outlook
As the enterprise market adjusts to the realities of the 2026 benchmark data, the competitive dynamics between American tech giants and emerging open-weights developers are entering a volatile new phase. The narrative that compute scale alone guarantees algorithmic supremacy has been replaced by an imperative for architectural, algorithmic, and economical efficiency.
In the coming quarters, enterprise CIOs should expect aggressive price drops across commercial API endpoints as market competition intensifies. However, the paradigm shift toward specialized, high-accuracy, low-cost reasoning engines is already underway. Organizations that re-architect their data pipelines to capitalize on open, high-efficiency models like DeepSeek will achieve superior unit economics, setting a new operational standard for the AI-driven global economy.