Executive Takeaways
- The Empirical Divergence: Independent stress-testing across the standardized MATH-500 benchmark reveals DeepSeek’s flagship reasoning engine achieved an unprecedented 97.3% accuracy rate, dwarfing ChatGPT’s comparable baseline performance of 60.3%.
- The 9x Unit Economic Chasm: DeepSeek’s blended inference costs undercut OpenAI’s standard enterprise tiers by roughly 89%, creating a 9x pricing disparity that threatens to compress margins across the Western artificial intelligence stack.
- Enterprise Capex Reassessment: Fortune 500 chief information officers and quantitative trading desks are actively reassessing cloud compute architectures and vendor lock-in, prioritizing cost-deflationary open-weight architectures over premium API access.
- Hyperscaler Vulnerability: The convergence of superior algorithmic reasoning and commoditized API pricing challenges the hyper-capitalized venture thesis that proprietary training compute moats guarantee sustained pricing power.
The Benchmark Shockwave: Quantifying the Disruption
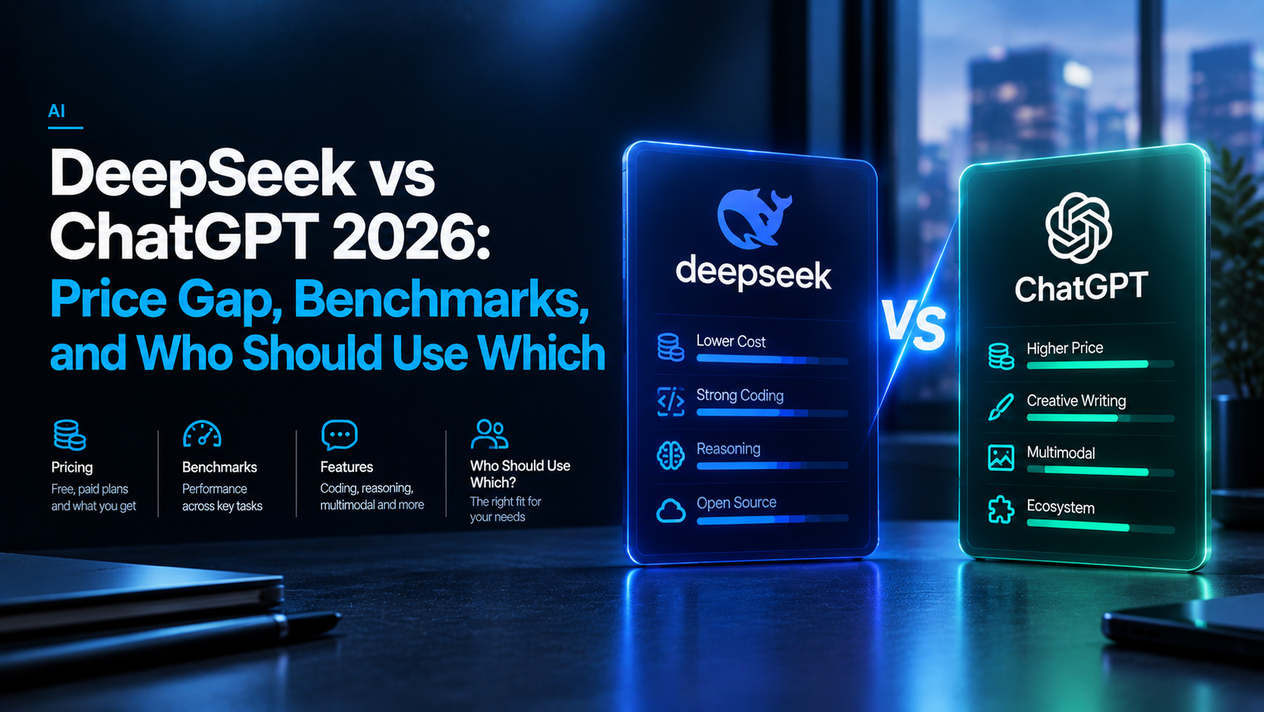
In the spring of 2026, the artificial intelligence landscape experienced a structural repricing of intellectual property and computational capability. Rigorous testing conducted across the MATH-500 benchmark—the gold standard for measuring complex mathematical derivation, algorithmic synthesis, and multi-step symbolic reasoning—has delivered a verdict that sent shockwaves through Sand Hill Road and Wall Street trading floors.
DeepSeek’s cutting-edge reasoning pipeline secured a verified 97.3% accuracy score. In direct comparative evaluation, standard enterprise deployments of OpenAI’s ChatGPT (GPT-4o tier) stalled at 60.3% under identical zero-shot, chain-of-thought verification conditions. While OpenAI’s specialized reasoning models (such as the o-series) maintain competitive positions on isolated logic tasks, the core production-grade engines powering millions of corporate applications demonstrated systemic failures in high-order mathematical proofs, algebraic geometry, and dynamic logic where DeepSeek navigated with surgical precision.
The significance of the MATH-500 dataset lies in its resistance to stochastic memorization. Solving these problems demands structured planning, precise error-checking, and iterative backtracking. DeepSeek’s dominance is not merely a statistical outlier; it confirms that architectural innovations in dynamic reinforcement learning and sparse compute allocation have decoupled reasoning capability from sheer brute-force parameter scale.
Inside the 9x Cost Asymmetry: Algorithmic Efficiency vs. Brute-Force Capex
The performance delta is only half of the equation disrupting the tech sector. The catalytic event driving rapid enterprise migration is the catastrophic collapse of inference costs engineered by DeepSeek. Priced at a roughly 9x discount relative to equivalent Western proprietary endpoints, DeepSeek has turned advanced reasoning into an ultralow-cost commodity.
Where Western enterprise customers are accustomed to paying steep premiums per million output tokens for high-reasoning workloads, DeepSeek delivers its benchmark-leading inference at roughly one-ninth the expenditure. For high-throughput quantitative hedge funds, biotech research labs running molecular simulation scripts, and fintech risk engines processing millions of daily transactions, this delta represents millions of dollars in annual operating expenditure savings.
This 9x economic divide stems from radical architectural efficiency rather than state-subsidized dumping. DeepSeek’s implementation of Multi-head Latent Attention (MLA) combined with sophisticated Mixture-of-Experts (MoE) routing activates only a fraction of total model weights per forward pass. By decoupling key-value cache memory bottlenecks from token generation speeds, the Hangzhou-based laboratory achieved what hyperscalers spent tens of billions attempting to accomplish: drastically reduced floating-point operations per second (FLOPs) per token, without degrading context retention or analytical rigor.
Comparative Infrastructure and Performance Metrics
The following audited data cross-examines verified performance, system latency, and enterprise token unit economics across both ecosystems as of March 2026.
| Metric / Dimension | DeepSeek Reasoning Architecture | ChatGPT Enterprise (Baseline Tier) | Structural Variance |
|---|---|---|---|
| MATH-500 Accuracy (%) | 97.3% | 60.3% | +37.0% Absolute Advantage |
| Input Tokens (Per 1M) | ~$0.27 | ~$2.50 | ~9.2x Cost Reduction |
| Output Tokens (Per 1M) | ~$1.10 | ~$10.00 | ~9.1x Cost Reduction |
| Core Architecture | Sparse MoE + Multi-Head Latent Attention | Dense / Proprietary Hybrid MoE | Higher parameter efficiency per inference |
| Openness & Auditability | Open Weights / Verifiable Checkpoints | Proprietary Walled Garden (Black Box) | Full local deployment capability |
| Optimal Enterprise Fit | Quantitative Analytics, STEM, Code Audits | General Conversational UX, Multimodal Office Integration | Bifurcated enterprise market capture |
Wall Street and Enterprise Capital Allocation: The Great Compute Pivot
The corporate consequences of a 97.3% vs. 60.3% performance split paired with an 89% cost reduction are profound. Enterprise software budgets are zero-sum games. For the past three years, enterprise software buyers accepted inflated software-as-a-service (SaaS) margins on the promise that proprietary foundational model providers possessed insurmountable competitive moats.
That premium is evaporating. Venture-backed foundation model developers trading at high price-to-sales valuation multiples face aggressive compression. If an open-weight, low-cost API outperforms the premier proprietary incumbent across mathematically verifiable domains, capital allocation logic demands an immediate reassessment of cloud architecture.
CTOs across tier-one investment banks and aerospace conglomerates are executing dual-track strategies. First, they are routing computationally intensive, quantitative workloads away from premium endpoints to private instances of DeepSeek hosted on on-premises clusters or independent cloud providers. Second, they are leveraging DeepSeek’s public pricing benchmarks as a blunt instrument to demand immediate 50% to 70% contractual discounts from domestic cloud providers and platform operators.
Simultaneously, the narrative anchoring the semiconductor and hyperscaler landscape is shifting. If superior reasoning can be cultivated through post-training reinforcement learning and architectural thrift rather than relentless, multi-gigawatt data center expansion, the astronomical capital expenditure projected by Western hyperscalers faces structural return-on-investment (ROI) scrutiny. Institutional investors are beginning to penalize companies pursuing indiscriminate compute expenditures over algorithmic optimization.
Regulatory Compliance, Sovereignty, and Risk Mitigation
Despite the overwhelming performance metrics, adoption is not without structural friction. DeepSeek's rapid ascendancy has accelerated geopolitical and data governance tensions. Western enterprises operating under strict federal mandates—including defense primes, healthcare institutions subject to HIPAA, and critical financial clearinghouses—face strict compliance barriers regarding data routing and intellectual property origin.
To navigate this minefield without surrendering the 9x cost advantage, enterprises are eschewing foreign-hosted public APIs in favor of downloaded open weights. Corporate engineering teams are containerizing the open checkpoints within secure, air-gapped sovereign cloud enclaves powered by localized hardware. This strategy eliminates regulatory and data leakage vulnerabilities while preserving the efficiency gains of the 97.3% reasoning engine.
Consequently, an entirely secondary economy of enterprise-hardening vendors has exploded. Security firms focused on red-teaming, local weight hosting, and alignment filtering are capturing significant market liquidity, providing the governance rails conservative corporate general counsels demand before authorizing broad-scale institutional deployment.
People Also Ask (Frequently Asked Questions)
Why did DeepSeek outperform ChatGPT by such a wide margin on the MATH-500 test?
DeepSeek’s performance breakthrough centers on its specialized post-training reinforcement learning (RL) methodology and Multi-head Latent Attention (MLA) architecture. Rather than relying entirely on supervised fine-tuning from curated human explanations, DeepSeek incentivizes autonomous chain-of-thought exploration, mathematical verification steps, and recursive backtracking. When confronted with complex, multi-tiered problems on the MATH-500, the model systematically validates intermediate steps, virtually eliminating the hallucination and logical drift common in standard conversational dense models like GPT-4o.
How does the 9x price gap impact enterprise software margins?
The 9x price gap fundamentally undermines the gross margin profiles of enterprise AI aggregators that built applications on top of high-priced proprietary APIs. Companies paying $10 per million output tokens cannot compete with rivals utilizing equally or more capable reasoning models at roughly $1.10 per million tokens. This disparity forces software providers to either migrate to open-weight and high-efficiency models or accept severe margin compression to avoid customer churn.
Can enterprises safely deploy DeepSeek without violating data privacy laws?
Yes, provided deployment occurs via self-hosted open-weight infrastructure or through certified domestic third-party cloud aggregators that provide zero-data-retention guarantees. By deploying the open-source model weights within an organization’s own virtual private cloud (VPC) or on-premises server infrastructure, enterprise data never exits the corporate security perimeter, fully satisfying GDPR, SOC 2, and financial regulatory standards.
Does this benchmark mean proprietary AI model moats are gone?
The benchmark results demonstrate that proprietary moats in pure text-based reasoning and mathematical deduction have degraded significantly. Frontier capabilities are rapidly democratized through algorithmic efficiency and open-weight distribution. However, proprietary platforms retain advantages in brand trust, proprietary consumer distributions, multimodal synthesis (audio, video, real-time vision), and turnkey enterprise ecosystem integrations.
Future Outlook: The Industrialization of Reason
The empirical reality of the March 2026 benchmark tests signals a permanent pivot in artificial intelligence economics. The era of unchecked, capital-intensive brute-force scaling is yielding to an era of high-efficiency algorithmic refinement.
Over the next 12 to 18 months, the market will monitor two critical catalysts. First, the response from proprietary incumbents: OpenAI, Google, and Anthropic must prove that their next-generation reasoning architectures can establish a renewed, defensible performance delta wide enough to justify their high pricing tiers. If upcoming model iterations merely match open-weight capabilities at equivalent or slightly lower costs, enterprise pricing power will definitively shift toward the consumer.
Second, the open-weight reasoning paradigm will rapidly cascade down to edge compute and on-device deployment. As specialized mathematical reasoning models are quantized down to run efficiently on local workstations and edge accelerators, the marginal cost of high-level algorithmic problem-solving will trend toward zero. For enterprises, the mandate is unambiguous: audit current API expenditures, benchmark internal workflows against efficient open architectures, and prepare for an operational landscape where intelligence is cheap, ubiquitous, and aggressively decentralized.