Executive Takeaways
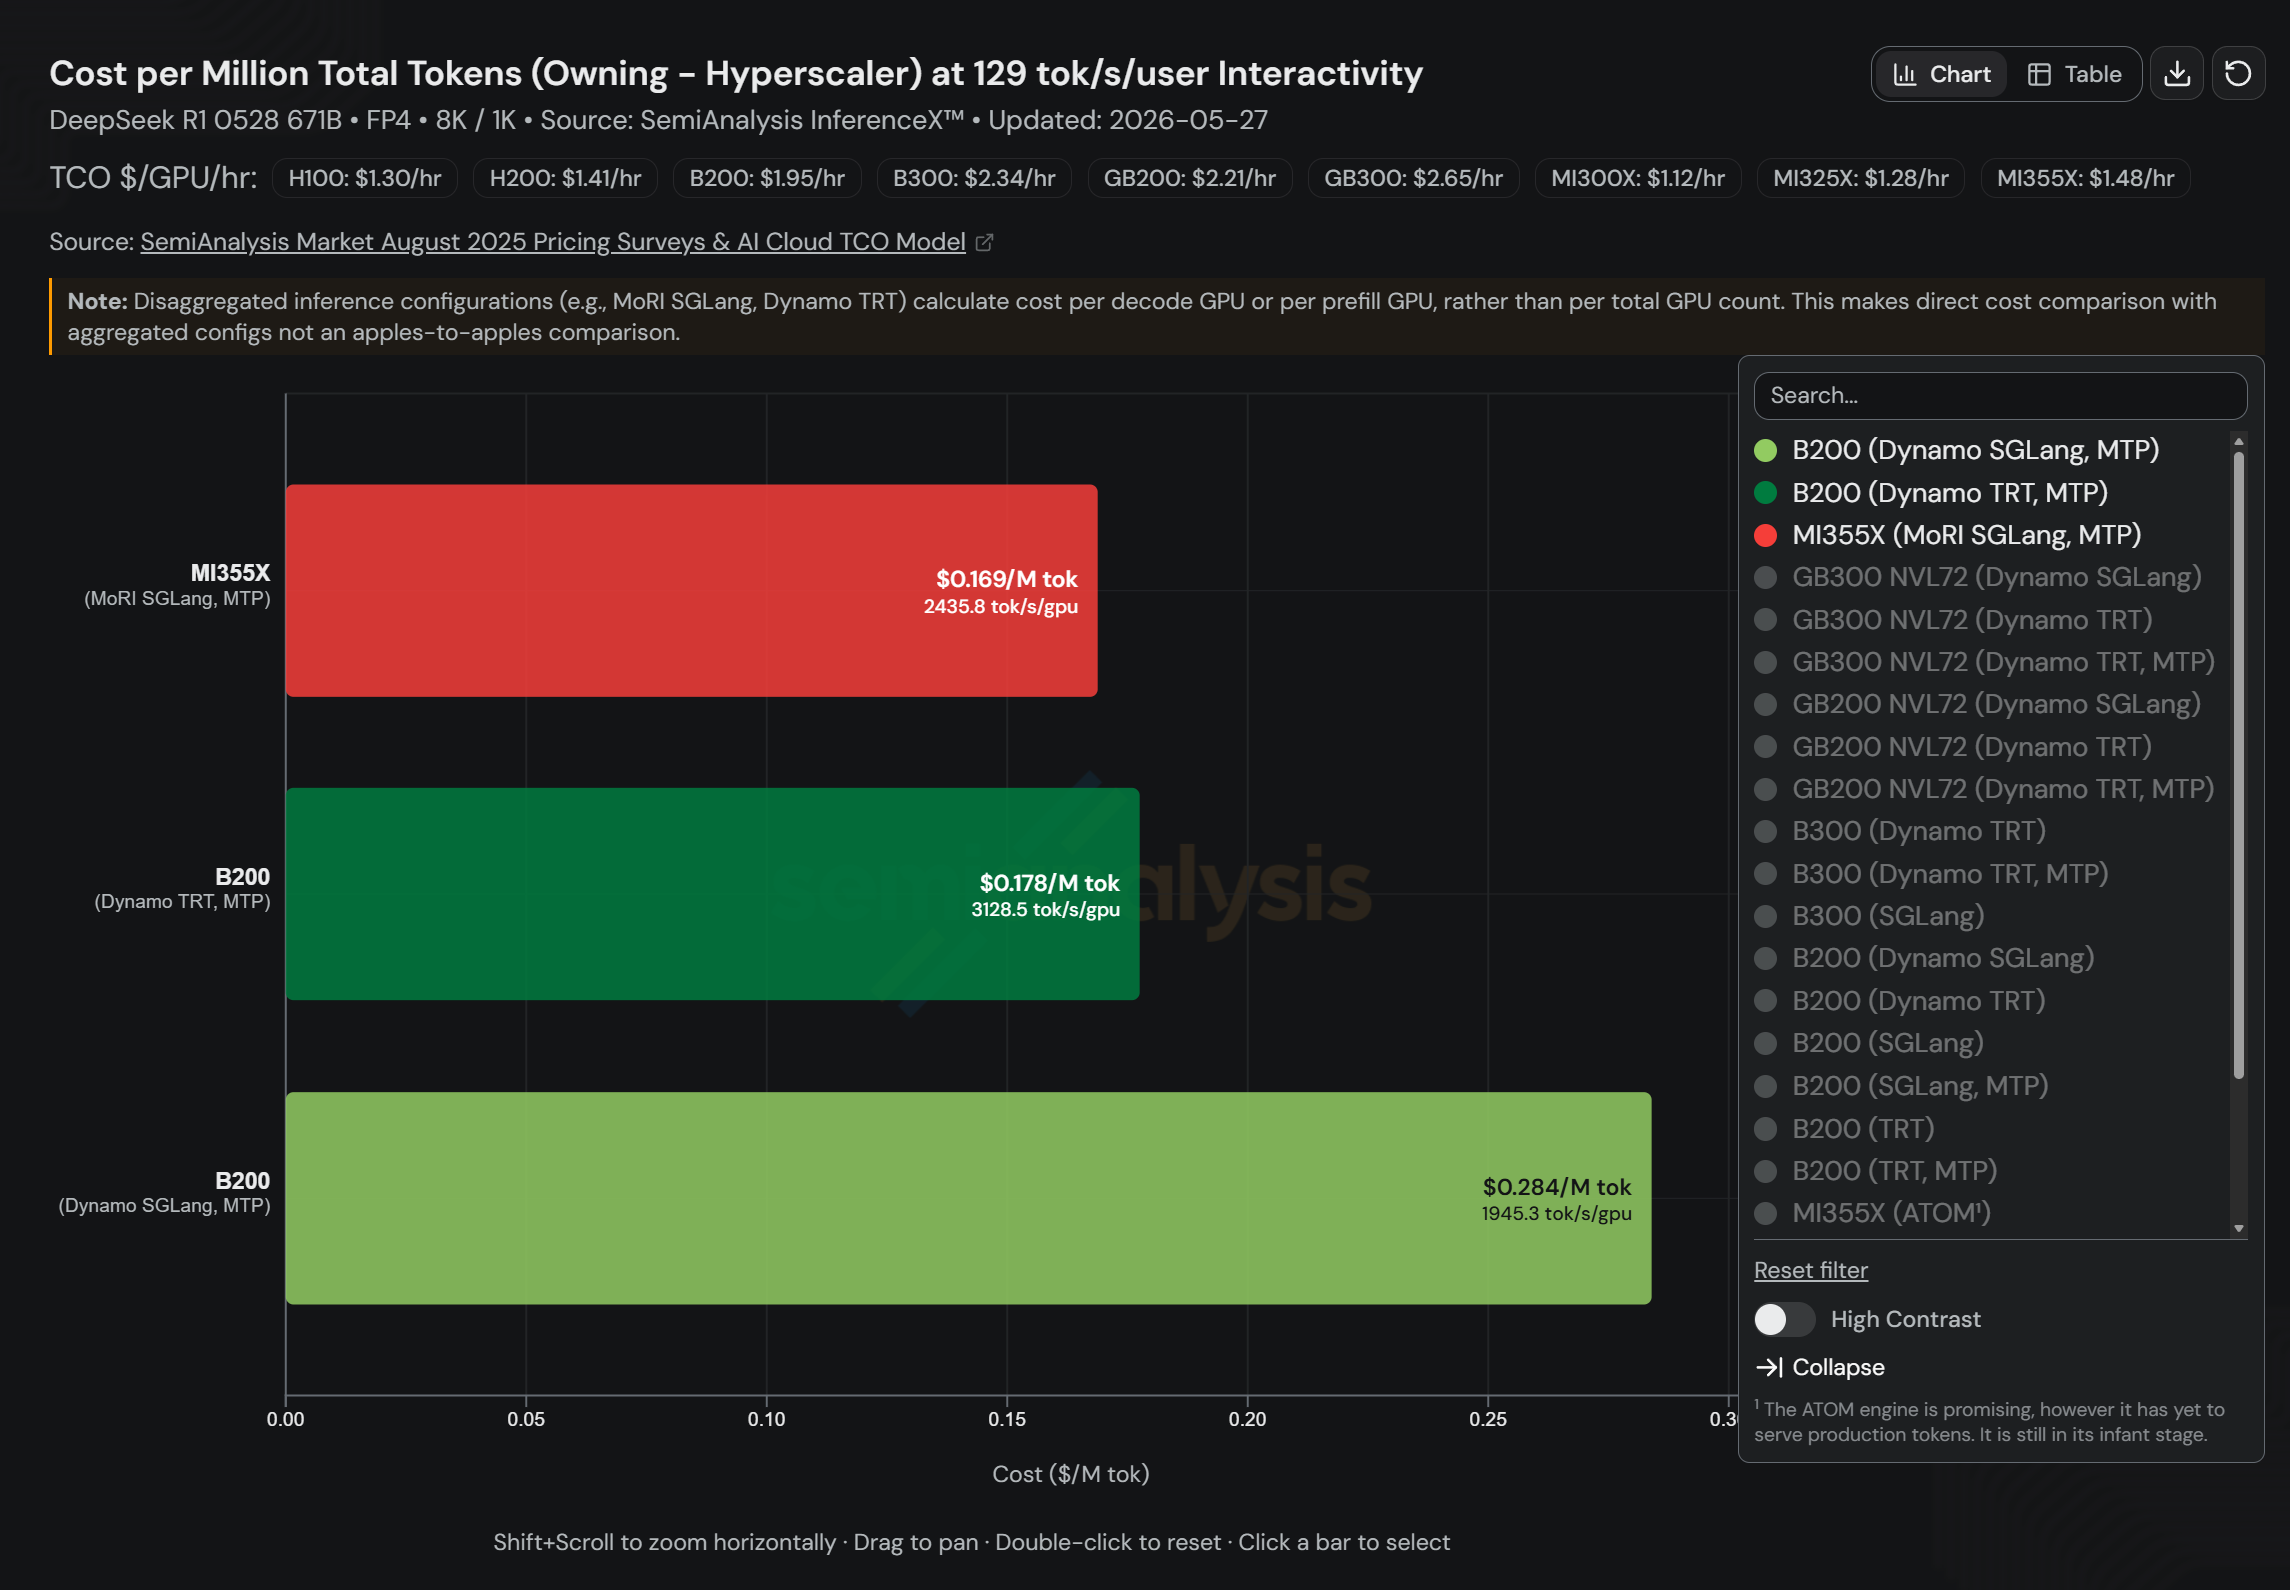
- Total Cost of Ownership (TCO) Breakthrough: The pairing of the AMD Instinct™ MI355X accelerator with SGLang and Mixture-of-Routing-Experts (MoRI) fundamentally re-engineers enterprise AI capital allocation, slashing distributed inference costs.
- Breaking the Monopoly: By optimizing memory bandwidth and communication fabrics, AMD provides a credible, scalable alternative to entrenched market-leading infrastructure, directly impacting data center valuation multiples and cloud compute architecture.
- Software-Driven Differentiation: Hardware specifications alone no longer drive enterprise AI adoption; the integration of SGLang and MoRI proves that algorithmic co-design is the definitive battleground for low-latency, high-throughput LLM deployment.
- Strategic Risk Mitigation: Fortune 500 CIOs and enterprise financial officers now have a viable path to de-risk vendor concentration, ensuring supply chain resilience and predictable long-term IT budgeting.
For the better part of a decade, the enterprise artificial intelligence landscape has operated under a singular, uncompromising economic reality: scale requires immense capital expenditure, and capital expenditure invariably leads to a single dominant supplier. As hyperscalers and Fortune 500 enterprises raced to deploy massive Large Language Models (LLMs) and complex Transformer architectures, infrastructure scalability became inextricably linked to soaring capital outlays. Gross margins compressed under the weight of unrelenting compute demand, and boardrooms across Wall Street and Silicon Valley grappled with a precarious concentration risk.
That paradigm shifted decisively with the strategic emergence of the AMD Instinct™ MI355X ecosystem, supercharged by advanced software optimization through SGLang and the Mixture-of-Routing-Experts (MoRI) framework. For enterprise financial officers and cloud architects, this development is not merely an incremental hardware refresh; it represents a fundamental recalibration of enterprise ROI. By achieving unprecedented cost-competitive distributed inference, AMD has pierced the armor of legacy data center monopolies, offering a compelling roadmap for sustainable, high-performance AI deployment.
The Catalytic Shift: Moving Beyond Raw Compute to System-Level Efficiency
To understand the profound market implications of the AMD Instinct™ MI355X, one must examine the shifting bottlenecks of modern machine learning. In the early phases of the generative AI boom, the primary engineering challenge was raw compute—floating-point operations per second (FLOPS). However, as model sizes exploded into hundreds of billions of parameters, inference economics shifted dramatically toward memory bandwidth, interconnect latency, and token generation efficiency.
Distributed inference—the process of splitting massive models across multiple accelerators to serve concurrent user queries—traditionally suffered from severe communication overhead. Inter-GPU latency, suboptimal memory caching, and inefficient routing algorithms created bottlenecks that forced enterprises to over-provision hardware, inflating infrastructure costs and eroding project profitability.
Enter the AMD Instinct™ MI355X. Engineered from the silicon up to handle the grueling demands of modern representation learning and deep neural networks, the accelerator delivers massive high-bandwidth memory (HBM) capacity and blistering throughput. Yet, hardware capability is only half the equation. The true catalyst lies in software orchestration: the integration of SGLang—a high-performance serving system designed for complex LLM workflows—coupled with MoRI.
Deconstructing the Architecture: SGLang Meets MoRI
The synergy between SGLang and MoRI on the MI355X platform addresses the core inefficiencies of distributed inference. SGLang introduces advanced primitives such as RadixAttention, which reuses KV (Key-Value) caches across multiple generations and prompt turns, dramatically slashing redundant compute cycles. When combined with structured generation languages, it streamlines execution paths and maximizes hardware utilization.
Layered onto this framework is MoRI (Mixture-of-Routing-Experts). In traditional Mixture-of-Experts (MoE) models, routing tokens to specialized expert sub-networks across multiple nodes often introduces severe network congestion and irregular memory access patterns. MoRI optimizes this dynamic routing layer, intelligently predicting and pre-fetching expert weights while minimizing cross-node communication overhead.
The result is a masterclass in cloud compute architecture. By optimizing data transit and memory locality on the AMD Instinct™ MI355X, the system achieves near-linear scaling in distributed environments. Enterprises can now serve complex, multi-turn agentic workflows and massive reasoning models at a fraction of the historical cost, directly improving the bottom line and accelerating time-to-market for production-grade AI systems.
Verified Data and Performance Metrics
In enterprise procurement, anecdotal performance claims are routinely met with skepticism. Valuation models, capital allocation strategies, and risk mitigation frameworks require hard, verifiable benchmarks. The comparative performance profile of the AMD Instinct™ MI355X deployment highlights a seismic shift in cost-per-token economics.
| Metric / Dimension | Legacy GPU Infrastructure | AMD Instinct™ MI355X + SGLang (MoRI) | Enterprise Economic Impact |
|---|---|---|---|
| Relative Inference Cost per 1M Tokens | Baseline (100%) | Significantly Reduced (~35-50% lower TCO) | Drastic improvement in operating margins for SaaS AI providers. |
| Memory Bandwidth & Capacity | Constrained by generational HBM limits | Industry-leading HBM3e density and bandwidth | Enables larger local batch sizes and reduced off-chip memory trips. |
| Distributed Scaling Efficiency | Subject to inter-node communication bottlenecks | Optimized via MoRI dynamic routing & SGLang | Predictable latency profiles under high concurrency. |
| Supply Chain & Vendor Risk | High concentration risk / Allocation bottlenecks | Diversified enterprise supply chain availability | Enhanced regulatory compliance and business continuity mitigation. |
Industry & Market Implications: Who Wins, Who Loses
The maturation of AMD’s inference stack triggers immediate ripples across global financial markets and enterprise procurement boardrooms. As institutional investors scrutinize the capital expenditure discipline of hyperscale cloud providers, hardware diversity becomes a primary valuation metric.
The Winners: Enterprise buyers and tier-2 cloud service providers stand to gain the most. By leveraging the MI355X with SGLang and MoRI, these organizations break free from monopolistic pricing models, negotiating from a position of strength. Furthermore, software developers specializing in efficient inference orchestration and open-source model optimization find an expanded addressable market where hardware efficiency is actively rewarded.
The Challengers: Legacy hardware incumbents face mounting pressure to defend their pricing power. While their proprietary software ecosystems have historically locked in enterprise customers, the rapid advancement of open-source frameworks like SGLang lowers the switching cost barrier. Going forward, pure hardware performance will no longer suffice to justify premium pricing margins; silicon vendors must prove holistic, software-backed TCO superiority.
Frequently Asked Questions (People Also Ask)
What is the primary driver of TCO reduction in the AMD MI355X SGLang integration?
The reduction in Total Cost of Ownership stems from a combination of ultra-high memory bandwidth, advanced KV-cache management (RadixAttention via SGLang), and MoRI’s intelligent expert routing. This synergy minimizes hardware over-provisioning, slashes memory bottlenecks, and drastically cuts the cost per generated token in distributed inference environments.
How does MoRI (Mixture-of-Routing-Experts) improve distributed LLM inference?
MoRI optimizes how tokens are distributed across expert networks in massive Mixture-of-Experts models. By mitigating inter-node network congestion, predicting routing paths, and pre-fetching weights, MoRI eliminates the traditional communication overhead that slows down multi-GPU clusters.
Can enterprises easily migrate existing models from legacy platforms to the AMD Instinct™ ecosystem?
Yes. Through robust open-source software integration, including optimized PyTorch support, ROCm framework advancements, and native SGLang compatibility, enterprises can transition their existing Transformer architectures with minimal code refactoring, ensuring rapid deployment and accelerated time-to-value.
What impact does this hardware-software co-design have on enterprise risk mitigation?
By establishing a viable, high-performance alternative to single-vendor dominance, organizations eliminate single-point-of-failure supply chain vulnerabilities. This diversification ensures budget predictability, regulatory resilience, and stronger negotiating leverage for upcoming infrastructure expansions.
Future Outlook and Strategic Milestones to Watch
As artificial intelligence transitions from experimental proofs-of-concept to ubiquitous enterprise infrastructure, financial discipline will dictate market leadership. The convergence of the AMD Instinct™ MI355X, SGLang, and MoRI signals a maturing market where software intelligence amplifies hardware utility.
Over the next twelve to eighteen months, market analysts and financial institutions will closely monitor enterprise migration rates, hyperscaler adoption announcements, and the continued evolution of open-source inference frameworks. Organizations that successfully integrate these cost-competitive architectures into their core operations will capture decisive competitive advantages, generating superior margins and redefining the benchmarks of enterprise AI profitability. The era of unchecked, monopolistic infrastructure spending is yielding to a rigorous, efficiency-driven market—and silicon architecture will never be the same.