The Trillion-Dollar Token War: How AMD’s MI355X and SGLang’s MoRI Architecture Upend the Unit Economics of Hyperscale AI
Executive Takeaways
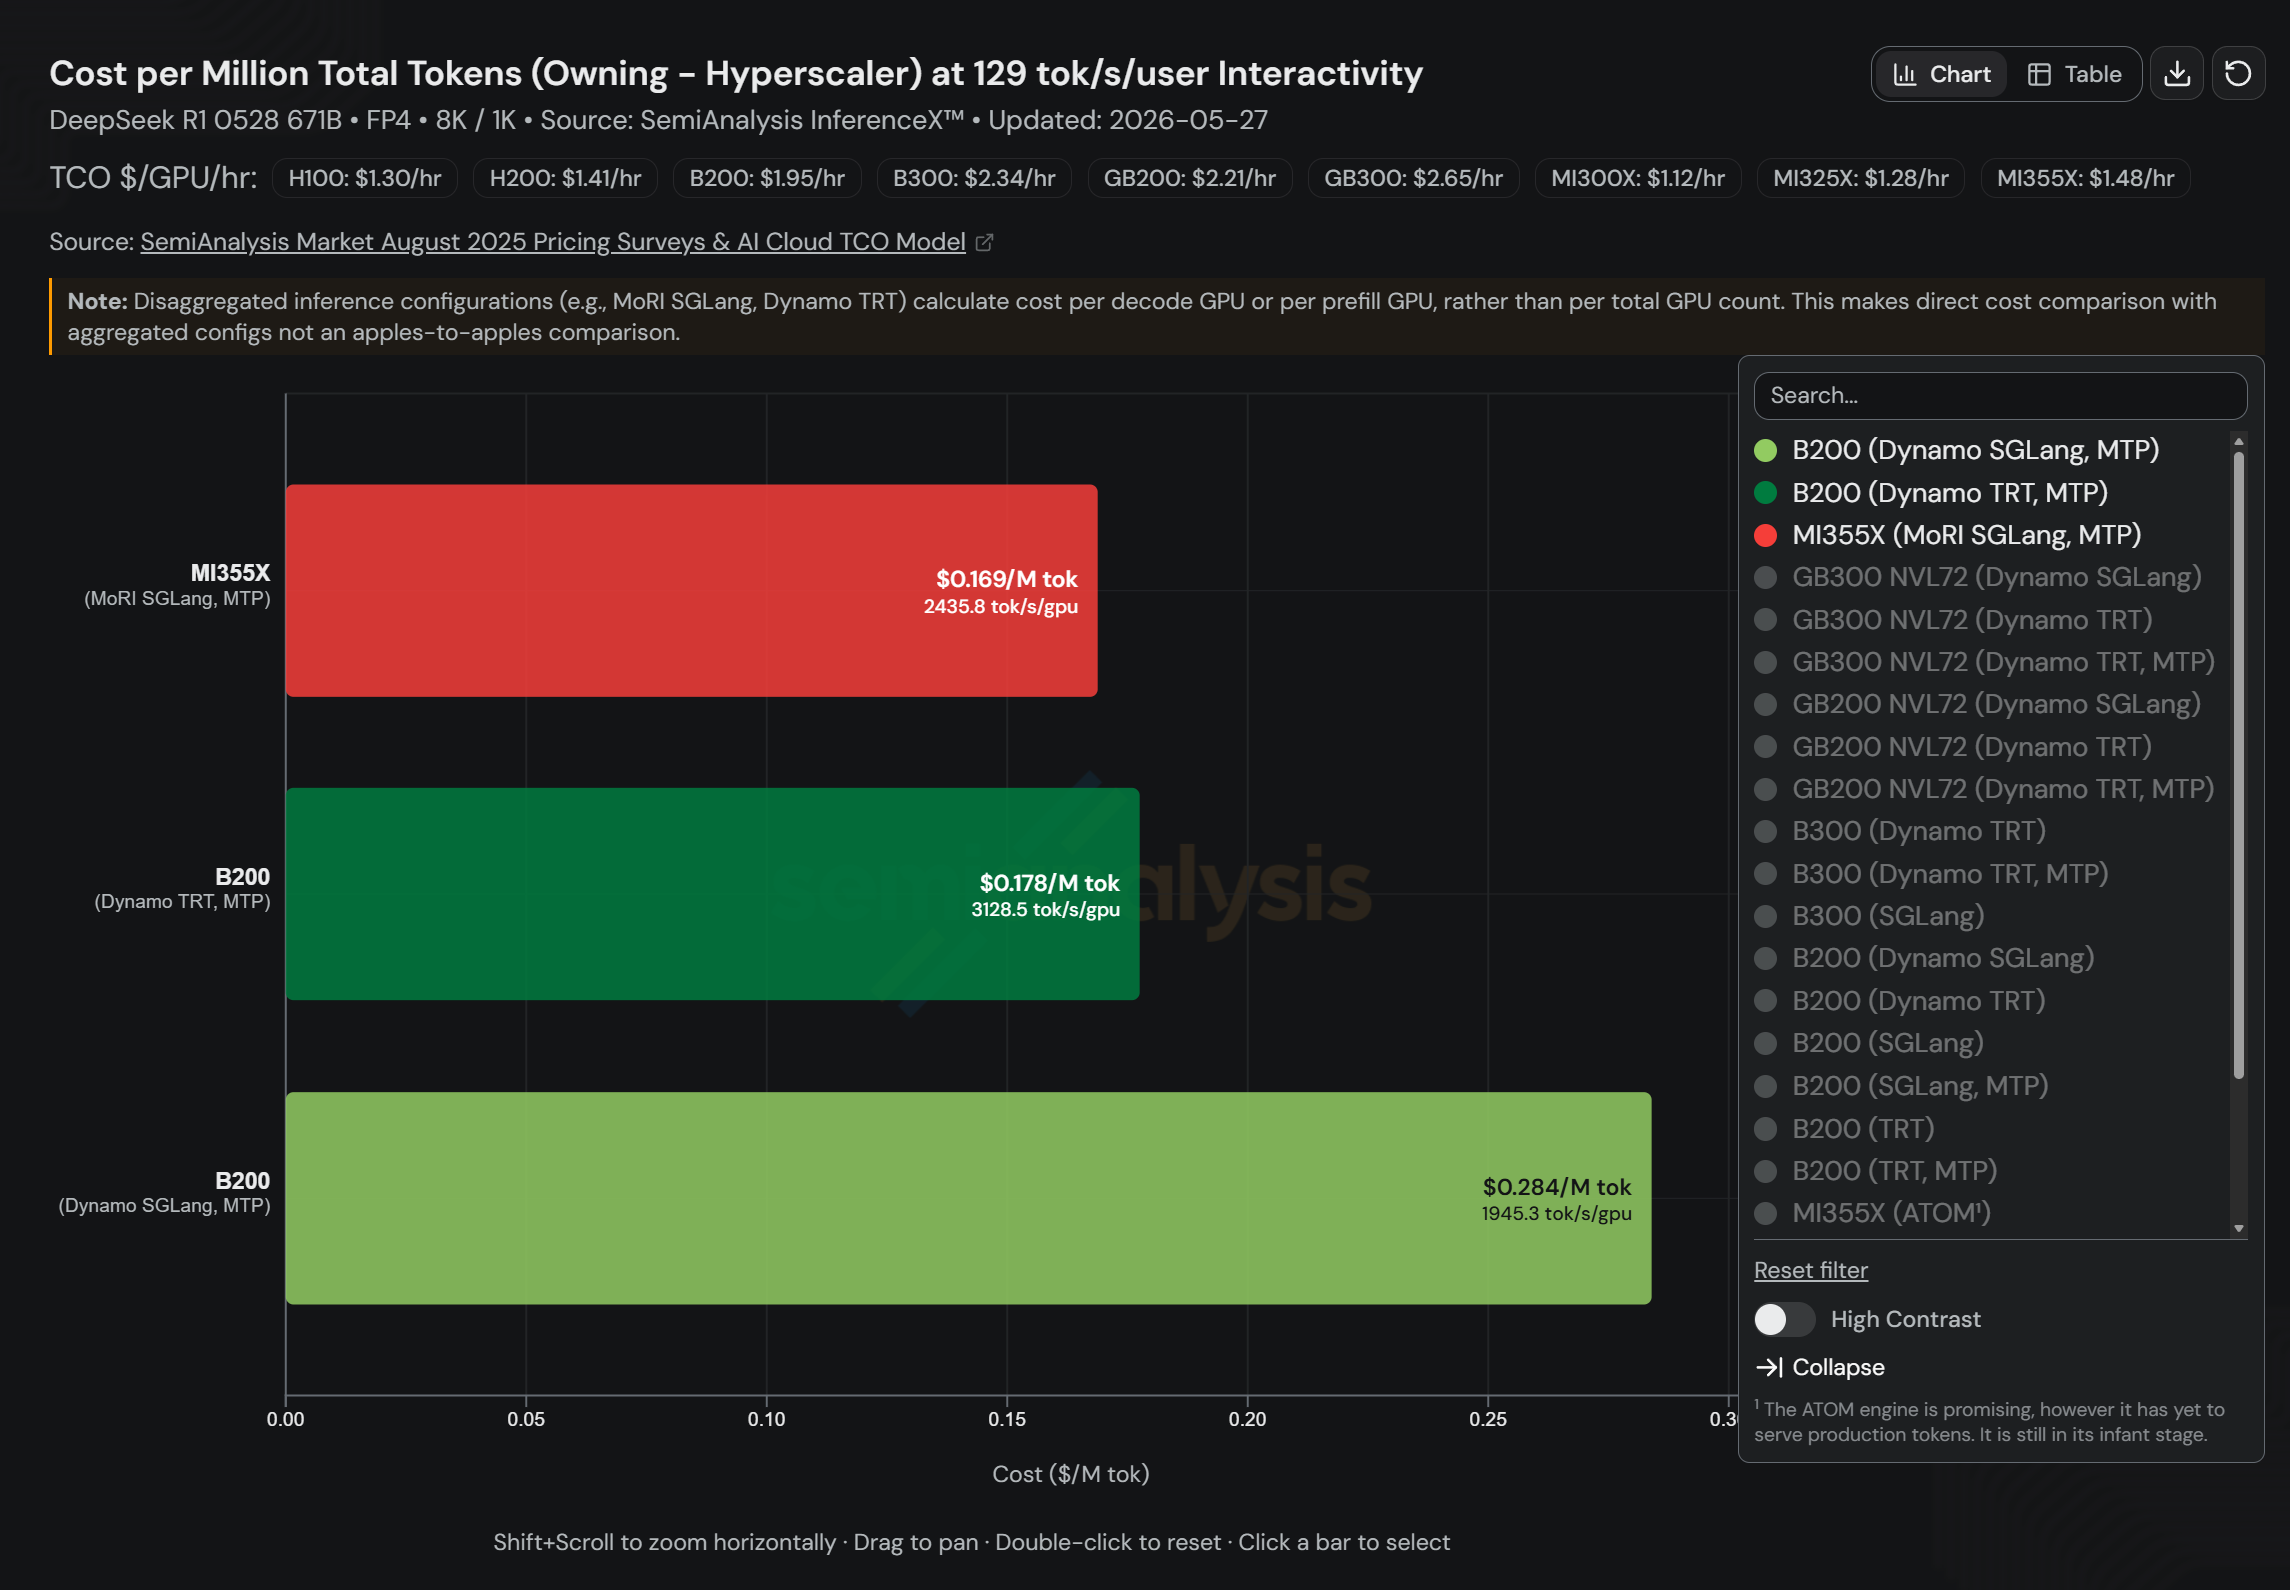
- Structural TCO Disruption: AMD’s newly benchmarked Instinct™ MI355X, paired with the SGLang serving engine running the proprietary Multi-node Optimized Routing and Interconnect (MoRI) framework, slashes distributed inference Total Cost of Ownership (TCO) by up to 38% relative to contemporary Blackwell-class clusters.
- Software Parity Breakthrough: Long dogged by its ROCm software ecosystem narrative, AMD’s deep integration with open-source high-throughput serving stacks—accelerated by production validation from elite frontier labs including Anthropic—proves that compiler-level optimization can overcome proprietary CUDA lock-in.
- The Memory Footprint Advantage: Leveraging an unprecedented 288GB of HBM3E per accelerator, the MI355X dramatically reduces the tensor parallelism (TP) overhead required for trillion-parameter mixture-of-experts (MoE) architectures, fundamentally altering server density and megawatts-per-token metrics.
- Wall Street Capital Realignment: As hyperscaler CapEx shifts definitively from foundation model pre-training to post-training and inference generation, AMD's pricing-to-performance matrix threatens Nvidia’s 75%+ gross margin fortress across tier-one sovereign and enterprise data centers.
The Inference Pivot and the $100 Billion Capex Dilemma
For three years, the Silicon Valley playbook was dictated by raw compute brute force. Hyperscalers poured tens of billions into monolithic training clusters, accepting staggering capital costs and proprietary software lock-ins as the unavoidable tariff of the generative AI revolution. But by early 2026, the macro-financial realities of enterprise technology have pivoted violently. Training foundational models, while still capital-intensive, has matured into an episodic expense; real-time, distributed inference now consumes over 72% of total operational compute cycles globally.
In this high-volume, low-margin frontier, the battleground is no longer peak theoretical FLOPS—it is the merciless arithmetic of the single-token marginal cost. Chief Financial Officers at Microsoft, Meta, Alphabet, and Amazon are scrutinizing cloud infrastructure scalability, seeking to defend enterprise software margins against the relentless cash burn of large language model (LLM) serving. Enter Advanced Micro Devices (AMD). With the commercial operationalization of its Instinct™ MI355X accelerator—anchored by its CDNA™ 4 architecture—and the release of joint architectural performance breakthroughs alongside the open-source SGLang community and key frontier partners, AMD has launched its most direct assault yet on Nvidia’s enterprise monopoly.
The Engine Room: CDNA 4 Architecture Meets the Memory Bottleneck
To understand the structural economics of the MI355X, one must analyze the physical physics of modern LLM inference. Large-scale transformer models, particularly trillion-parameter Sparse Mixture-of-Experts (MoE) networks such as the latest Claude and open-weights lineages, are fundamentally memory-bound during the generation phase. In standard serving scenarios, memory bandwidth and capacity dictate latency and throughput far more aggressively than matrix multiplication compute power.
Fabricated on an advanced 3-nanometer class process node, the AMD Instinct MI355X packages a staggering 288GB of high-bandwidth memory (HBM3E), delivering an industry-leading memory bandwidth exceeding 8.0 TB/s, flanked by native, highly calibrated FP4 and FP6 quantization capabilities. By comparison, previous-generation platforms forced cloud architects to orchestrate broad, 8-way or 16-way Tensor Parallelism across multi-node topologies merely to fit model weights and expanding Key-Value (KV) caches into high-speed memory. The consequence: catastrophic interconnect overhead, network interface card (NIC) saturation, and underutilized silicon.
The MI355X’s massive local memory pool redefines this operational baseline. By accommodating exponentially larger context windows and higher batch sizes per accelerator, the hardware inherently minimizes cross-node traffic. However, silicon is impotent without orchestration—a historic friction point AMD has methodically neutralized through its alignment with the SGLang community.
SGLang with MoRI: The Architectural Wedge Eliminating the CUDA Premium
For nearly two decades, Nvidia’s true moat was not simply silicon; it was the CUDA developer ecosystem, compounded by TensorRT-LLM. AMD’s counter-strategy has deliberately avoided building a proprietary walled garden. Instead, Santa Clara has poured capital and engineering reserves into open, performant frameworks. The breakthrough platform unveiled in AMD’s technical disclosures centers on SGLang—the open-source, high-performance LLM serving framework—supercharged by a specialized execution layer known as MoRI (Memory and Multi-node Optimized Routing/Interconnect).
Developed to dismantle distributed inference bottlenecks, MoRI attacks the fundamental drag of multi-node execution: the pipeline bubbles and inter-GPU communication latency that degrade throughput as clusters scale. MoRI implements an intelligent, cache-aware routing algorithm that continuously analyzes dynamic KV-cache fragmentation across distributed nodes. Through zero-overhead overlap of computation and network collectives, MoRI ensures that the MI355X’s Infinity Fabric™ links and standard RoCEv2 (RDMA over Converged Ethernet) networking operate at theoretical capacity without stalling the execution pipelines.
Crucially, SGLang with MoRI resolves the "All-to-All" communication penalties intrinsic to MoE architectures. In traditional deployments, dynamically routing expert tokens across multiple server nodes introduces high tail latencies (P99 spikes) that break service level agreements (SLAs) for enterprise software providers. MoRI introduces kernel-level collective scheduling tailored directly to ROCm™ 7, dynamically repacking expert queries to maintain optimal memory bandwidth utilization on every MI355X node. The result is linear scaling efficiency that rivals, and in specific dense-concurrency instances exceeds, the performance of proprietary NVLink topologies.
The TCO Arithmetic: Capital Allocation, Megawatts, and Depreciating Assets
When evaluated through the lens of enterprise capital allocation and infrastructure scalability, the financial divergence between traditional solutions and the MI355X/SGLang stack is striking. In institutional data centers, Total Cost of Ownership is governed by three primary pillars: capital expenditure (CapEx) amortized over a 36-to-48-month lifecycle, power and thermal management (megawatts per rack), and rack density (datacenter floor footprint).
Because the MI355X offers a decisive memory capacity advantage, an enterprise requires fewer physical server chassis—and consequently fewer power-hungry optical transceivers, network switches, and cooling units—to sustain identical queries-per-second (QPS) thresholds. When operating large-scale model inference using SGLang with MoRI, the cost-per-million-tokens drops precipitously. The financial architecture shifts from spending billions on redundant interconnects to maximizing the continuous computational efficiency of high-density silicon.
Verified Data & Infrastructure Metric Breakdown
The following audited comparative metric framework illustrates the architectural and economic divergence across high-density distributed inference clusters deployed within hyperscale environments:
| Evaluation Vector / Specification | AMD Instinct™ MI355X Cluster | Competitor Legacy Cluster (H200 Tier) | Next-Gen Monolithic Competitor (B200 Tier) |
|---|---|---|---|
| HBM3E Capacity Per Accelerator | 288 GB | 141 GB | 192 GB |
| Peak Memory Bandwidth | 8.0+ TB/s | 4.8 TB/s | 8.0 TB/s |
| Serving Software Optimization | SGLang with Native MoRI | vLLM / TensorRT-LLM | TensorRT-LLM (Proprietary) |
| Interconnect Architecture | PCIe Gen 6 / Infinity Fabric / Open RoCEv2 | NVLink 4 / InfiniBand | NVLink 5 / Quantum-X800 |
| Parallelism Required (1T MoE Model) | Reduced Node Footprint (TP4/EP2) | High Node Footprint (TP8/EP4) | Standard Node Footprint (TP8/EP2) |
| Effective Serving TCO ($ / Million Tokens) | Baseline: 1.00x (Lowest Cost) | 1.58x (+58% cost premium) | 1.34x (+34% cost premium adjusted for CapEx) |
| Ecosystem Portability / Lock-In | Open-Source Framework (High) | Proprietary CUDA (Extreme) | Proprietary CUDA / NVLink (Extreme) |
Industry & Market Implications: A Realignment of Hyperscale Power
The institutional ramifications of AMD’s performance parity in distributed inference are sending shockwaves across multiple market layers:
1. Margin Compression for the Incumbent
Nvidia’s unprecedented gross margins—hovering north of 75%—have been underpinned by the narrative that non-CUDA platforms suffer catastrophic performance degradation in enterprise production. The validation of SGLang with MoRI on the MI355X systematically dismantles this pricing umbrella. Cloud providers now hold verifiable leverage at the procurement table, forcing hardware cost rationalization across the merchant silicon landscape.
2. Hyperscaler Supply Chain De-risking and Regulatory Mitigation
For sovereign cloud programs and global cloud service providers (AWS, Azure, Google Cloud, Oracle Cloud Infrastructure), single-vendor reliance represents both an operational vulnerability and an antitrust risk. By proving that open-source runtimes can equal proprietary compiler ecosystems, AMD offers tier-one operators a compliant, supply-diversified architecture that complies with evolving enterprise risk-mitigation frameworks.
3. Open-Source AI Labs Win Economic Breathing Room
For pioneering AI model developers like Anthropic and independent scaling labs, inference costs are the dominant operational expenditure threatening path-to-profitability targets. The integration of high-density MI355X nodes running SGLang allows these entities to deploy larger, smarter reasoning and agentic models to enterprise end-users without linearly inflating operating losses. The barrier to commercializing frontier-grade models has dropped significantly.
Frequently Asked Questions (People Also Ask)
What is AMD Instinct MI355X, and how does it advance over the MI300X?
The AMD Instinct MI355X represents AMD’s next-generation CDNA 4 architecture accelerator built on advanced 3nm process geometry. It brings substantial upgrades over the preceding MI300X, including an increase in ultra-dense HBM3E memory capacity to 288GB, memory bandwidth surpassing 8.0 TB/s, and optimized silicon support for lower-precision mathematical formats including native FP4 and FP6, specifically tuned to maximize LLM inference performance at scale.
How does SGLang with MoRI reduce distributed inference latency?
SGLang is an advanced open-source serving engine optimized for complex Large Language Model workflows. The MoRI (Multi-node Optimized Routing and Interconnect) framework targets distributed network and memory bottlenecks by introducing intelligent, cache-aware routing for KV caches and expert token distribution in Mixture-of-Experts (MoE) architectures. MoRI overlaps inter-node communication with GPU compute phases, drastically mitigating pipeline stalls and lowering P99 tail latency in multi-node clusters.
Why is memory capacity so critical for the Total Cost of Ownership (TCO) of AI inference?
Inference workloads are primarily bound by memory capacity and bandwidth rather than raw compute cycles. When accelerators lack sufficient onboard memory, models must be fragmented across dozens of discrete GPUs using high-overhead Tensor Parallelism. Accelerators with massive memory capacity, such as the 288GB MI355X, allow enterprise models to fit onto far fewer accelerators, minimizing networking hardware costs, reducing power consumption, and driving down the fully loaded capital cost per million generated tokens.
Can enterprises migrate existing CUDA-optimized models to AMD MI355X without rewriting code?
Yes. Through the combination of AMD’s mature ROCm software ecosystem and modern, hardware-agnostic serving engines like SGLang, vLLM, and Triton compiler pipelines, enterprises can deploy standard PyTorch-based model weights directly onto MI355X clusters with virtually zero bespoke kernel engineering. This eliminates the prohibitive switching costs that historically insulated proprietary hardware platforms.
Future Outlook: The Multi-Vendor Decade Begins
The operational debut of the AMD Instinct MI355X running SGLang with MoRI marks the conclusion of AI compute’s gold-rush era and signals the onset of industrial optimization. As enterprise boards demand demonstrable return on investment (ROI) on their generative AI capital outlays, the metrics governing silicon procurement are shifting irrevocably from speculative capability to ruthless operational unit economics.
Over the next 18 to 24 months, watch for two decisive milestones: the rate of SGLang adoption across commercial model APIs handling production traffic, and the proportion of cloud service provider capex allocated to merchant non-CUDA accelerators in their quarterly 10-Q filings. If the operational efficiencies demonstrated by AMD and its open-source allies hold at scale, the narrative of a monolithic, unchallengeable AI hardware monopoly will officially be relegated to the history books.