
Executive Takeaways
- Architectural Breakthrough: LMSYS Org's landmark deployment showcases how a cluster of just 96 NVIDIA H100 GPUs can efficiently run massive open-source Mixture-of-Experts (MoE) models using Prefill-Decoding (PD) disaggregation.
- Capital Allocation Shift: By decoupling compute-bound prompt ingestion from memory-bandwidth-bound token generation, enterprises can slash total cost of ownership (TCO) and bypass massive cluster expenditure.
- Market Disruption: The deployment directly challenges traditional hyperscaler infrastructure scaling models, forcing a re-evaluation of enterprise AI ROI, capital expenditure (CapEx) multiples, and hardware amortization schedules.
- Operational Efficiency: Large-scale Expert Parallelism eliminates previous GPU memory bottlenecks, enabling high-throughput, low-latency inference previously thought to require thousands of enterprise-grade accelerators.
The global race for generative artificial intelligence infrastructure has entered a hyper-rationalized phase, dictated not by raw chip accumulation, but by algorithmic efficiency and structural system optimization. According to landmark technical disclosures released by LMSYS Org, a production-grade deployment of the open-source DeepSeek model architecture using Prefill-Decoding (PD) disaggregation and large-scale expert parallelism across a modest cluster of 96 NVIDIA H100 GPUs has fundamentally rewritten the rules of enterprise infrastructure scalability.
For executive leadership teams, chief technology officers, and institutional investors navigating high-stakes capital allocation decisions, this breakthrough represents more than an academic milestone. It is a severe structural stress test for the prevailing "more silicon, more capital" narrative that has dominated Wall Street technology valuations and cloud compute architecture over the past three decades. By demonstrating that tier-one inference performance can be extracted from constrained hardware footprints, the DeepSeek blueprint offers a masterclass in risk mitigation, margin expansion, and asset utilization.
The Catalytic Shift: Deconstructing the GPU Bottleneck
Since the commercialization of large language models, the enterprise playbook for deployment has been linear and capital-intensive: procure massive clusters of enterprise-grade GPUs, bind memory and compute tightly within monolithic server nodes, and absorb soaring energy and infrastructure costs. However, this monolithic approach suffers from a severe operational flaw: the fundamental divergence between prefill phases (which are compute-bound, processing massive prompt tokens simultaneously) and decoding phases (which are memory-bandwidth-bound, generating tokens sequentially).
When deploying Mixture-of-Experts (MoE) models like DeepSeek, these operational inefficiencies multiply. MoE architectures route tokens through sparse subnetworks ("experts"), causing uneven workload distributions across GPUs and triggering severe inter-node communication latency. Traditional distributed inference frameworks struggled to maintain high GPU utilization rates, leaving expensive silicon idle while waiting for memory fetches or network synchronization.
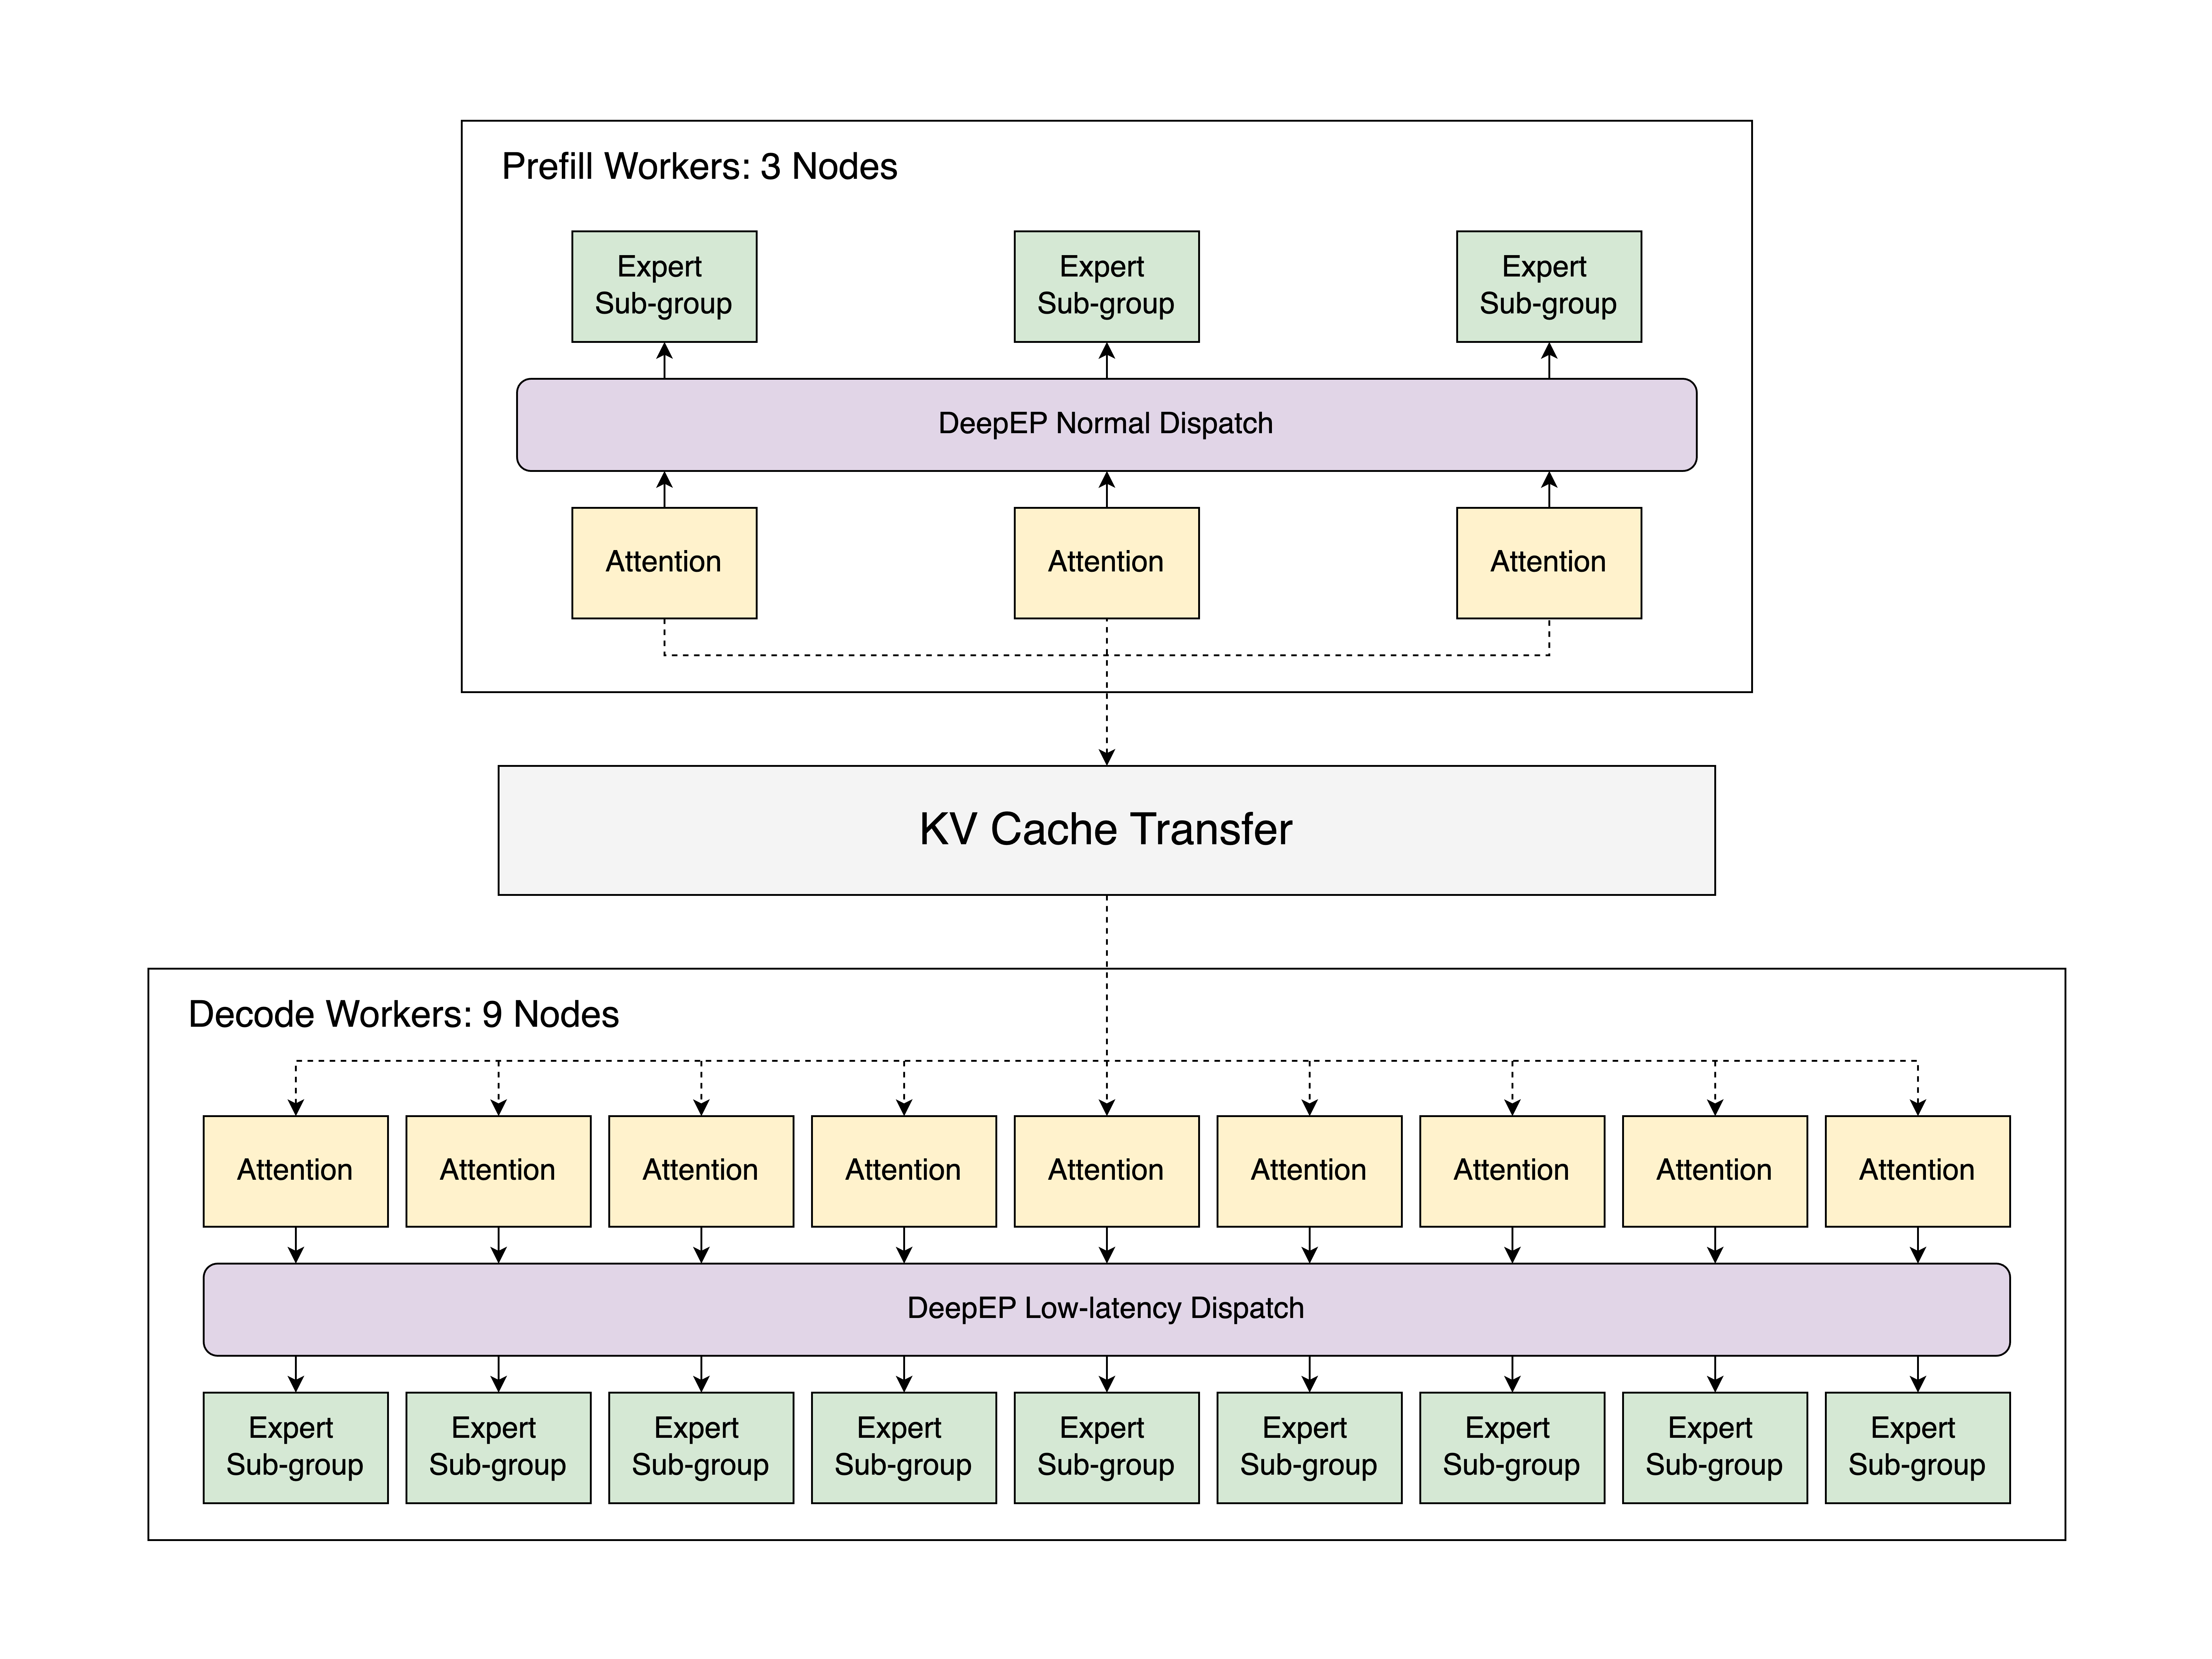
LMSYS Org's breakthrough addresses this core pathology through PD Disaggregation. By physically and logically separating the prefill nodes from the decoding nodes within a streamlined 96-GPU cluster, system architects can independently optimize hardware for its specific operational profile. Prefill nodes are configured for raw compute throughput, while decoding nodes are tuned for maximum memory bandwidth and rapid token generation. Coupled with Large-Scale Expert Parallelism (EP), the system dynamically balances expert routing across the network fabric, ensuring that high-speed NVLink and InfiniBand interconnects are saturated with productive data traffic rather than idle waiting cycles.
Granular System Architecture: The 96 H100 Paradigm
To understand the profound financial and operational implications of this deployment, one must examine the underlying engineering mechanics. Operating within a constrained cluster of 96 NVIDIA H100 GPUs requires rigorous resource governance and network optimization.
In standard configurations, running massive open-source models with active parameter counts exceeding hundreds of billions would trigger out-of-memory (OOM) exceptions or severe throughput degradation. The LMSYS implementation leverages advanced tensor parallelism, pipeline parallelism, and expert parallelism simultaneously (often termed 3D or hybrid parallelism) tailored specifically to the H100’s Hopper architecture, including its Transformer Engine and fourth-generation Tensor Cores.
By implementing PD disaggregation, the engineering team eliminated the interference between long-context prompt processing and real-time generation latency. When a client submits a massive document for summarization or analysis, the prefill cluster absorbs the heavy lifting without stuttering the token generation pipeline currently serving downstream users. This decoupling maximizes the operational utility of each individual H100 GPU, driving up effective queries-per-second (QPS) per dollar invested.
Verified Data & Metrics Breakdown
The following comparative matrix illustrates the structural differences between traditional monolithic GPU scaling and the optimized PD Disaggregation with Expert Parallelism model demonstrated on the 96 H100 footprint.
| Metric / Parameter | Traditional Monolithic Deployment | DeepSeek with PD Disaggregation & EP (96 H100s) |
|---|---|---|
| Primary Hardware Footprint | Massive clusters (512+ GPUs) required for acceptable latency | Lean, highly optimized 96 NVIDIA H100 GPU cluster |
| Compute vs. Memory Handling | Interleaved; prefill and decode phases contend for identical GPU memory and cycles | Strictly disaggregated; dedicated prefill and decode node pools |
| Expert Parallelism Scale | Limited by inter-node communication bottlenecks and routing imbalance | Large-scale, fine-grained routing maximizing NVLink fabric efficiency |
| Enterprise Infrastructure TCO | Extremely high capital expenditure and ongoing power consumption | Radically reduced CapEx; significantly higher throughput-per-dollar |
| Regulatory & Compliance Posture | Requires massive sovereign cloud footprints to achieve scale | Deployable on-premises or in private sovereign clouds with controlled hardware |
Industry & Market Implications: Winners, Losers, and Economic Realities
The operational success of running advanced open-source architectures like DeepSeek on restricted hardware sends shockwaves across the financial and technology sectors. Market valuations in the AI ecosystem have long priced in perpetual hyper-growth for foundational infrastructure providers, specialized chipmakers, and hyperscale cloud providers selling raw compute by the hour.
Who Wins:
- Enterprise End-Users & Mid-Market Corporates: Organizations previously priced out of elite generative AI capabilities can now deploy state-of-the-art reasoning models on localized or right-sized cloud infrastructure, dramatically accelerating enterprise ROI.
- Open-Source Ecosystem Advocates: Developers and independent researchers gain validated engineering blueprints that prove proprietary moats built solely on hardware scale are increasingly vulnerable to algorithmic innovation.
- Pioneers in Cloud Compute Architecture and orchestration software who specialize in workload disaggregation and low-latency cluster scheduling.
Who Faces Headwinds:
- Hyperscale Cloud Providers: Margin pressures could intensify if enterprise customers discover they can achieve equivalent performance using a fraction of the leased GPU instances previously deemed mandatory.
- Hardware-Centric Valuation Models: Venture capitalists and institutional investors who underwrite AI startups based strictly on the number of GPUs secured must pivot toward software efficiency metrics and unit economics.
Frequently Asked Questions (People Also Ask)
What is Prefill-Decoding (PD) Disaggregation in LLM deployments?
PD disaggregation is an architectural optimization technique that separates the two distinct phases of large language model inference—the prefill phase (processing input prompts) and the decoding phase (generating output tokens sequentially). By isolating these workloads onto dedicated hardware nodes, system operators eliminate resource contention, maximize GPU compute and memory bandwidth utilization, and dramatically reduce end-to-end latency.
Why is Large-Scale Expert Parallelism critical for running models like DeepSeek?
Mixture-of-Experts (MoE) models utilize sparse activation, meaning only a subset of network parameters is invoked for any given token. Large-scale expert parallelism distributes these specialized subnetworks across multiple GPUs and high-speed interconnects. This prevents memory bottlenecks on individual accelerators and balances computational loads, enabling massive models to run efficiently on surprisingly compact hardware footprints.
How does deploying DeepSeek on 96 H100 GPUs impact enterprise AI budgets?
By proving that high-end inference can be achieved using dozens rather than thousands of enterprise GPUs, this deployment lowers the barrier to entry for private cloud and on-premises deployments. It cuts hardware acquisition costs, curtails ongoing power consumption overhead, and accelerates enterprise ROI by optimizing unit compute economics.
Is this deployment methodology restricted solely to NVIDIA H100 hardware?
While LMSYS Org utilized NVIDIA H100 GPUs for this specific benchmark due to their dominant market share and high-bandwidth NVLink capabilities, the underlying architectural principles—PD disaggregation and expert parallelism—are fundamentally hardware-agnostic. They can be adapted to alternative enterprise accelerators, AMD Instinct lines, and emerging custom ASIC inference chips.
Future Outlook: Strategic Milestones to Watch
As the enterprise AI landscape matures through 2025 and beyond, the blueprint established by LMSYS Org signals a permanent maturation of the market. The era of brute-force scaling is giving way to an era of disciplined systems engineering. Executive leadership must monitor several critical milestones:
- Standardization of Disaggregated Inference Frameworks: Watch for enterprise orchestration platforms (such as vLLM, SGLang, and TensorRT-LLM) to natively bake PD disaggregation and automated expert placement into their core releases.
- CapEx Realignment Across Cloud Giants: Institutional equity analysts will closely examine capital expenditure guidances from major cloud service providers as software efficiencies reduce per-customer hardware demand.
- Sovereign and On-Premises AI Adoption: With hardware requirements dropping into manageable ranges (such as the 96-GPU threshold), heavily regulated sectors like financial services, healthcare, and defense will accelerate sovereign AI deployments without relying entirely on public cloud hyperscalers.
Ultimately, the deployment of DeepSeek with PD disaggregation and large-scale expert parallelism on 96 H100 GPUs is not merely a technical achievement—it is a financial and strategic realignment. In the new economic paradigm of artificial intelligence, intelligence is no longer bought by the rack; it is engineered by the algorithm.


